thih93 hours ago
I am once again happy that the EU is fighting practices like these via legislation.
Some outcomes can be annoying, but the net result is still positive, for the consumers and their data privacy at least.
fooker2 hours ago
> Some outcomes can be annoying
I'd classify mandatory encryption backdoors as an industry crisis rather than an annoyance.
dspillettan hour ago
Which has nothing to do with the stalking of the adtech industry, unless you are suggesting that the EU might sell access to the keys to the likes of OpenAI?
[though you are not wrong that encryption backdoors are a backwards step on individuals rights to privacy]
Llamamoea minute ago
Encryption backdoors by definition mean everybody who wants it gets hands on your data. You can't make backdoors only the "good guys" can access.
And while, sure, adtech corpos maybe won't due to the bad PR, what about the Kremlin, criminal organizations, or your insane abusive ex?
patrickmcnamara41 minutes ago
When has the EU mandated encryption backdoors?
buzer23 minutes ago
They keep trying it via e.g. chat control
tensor18 minutes ago
The US has also tried it multiple times. So has Canada. It's been shut down each time. This isn't a unique to the EU problem.
jampekkaan hour ago
> I am once again happy that the EU is fighting practices like these via legislation.
As long as you manage to navigate all the dark patterns and not accidentally give your "informed consent".
dspillettan hour ago
Malicious compliance (or as it more usually is malicious noncompliance that has not been sufficiently punished so the slimy buggers feel free to continue) is something you should blame the stalkers of adtech for, more than the EU. The legislators could perhaps have made the definitions less wavy, and been harder with enforcement, but that doesn't make it all their fault.
jampekka31 minutes ago
These problems were quite widely foreseen during the legislative process, and partly had already been exhibited by the earlier ePrivacy directive. I don't know whether it matters who's to blame, but my trust in EU being very effective in these fights in the future either is not very high.
einpoklum17 minutes ago
Is it now? Are Alphabet, Microsoft, Yahoo and Meta's platforms and call-home products illegal for exposure to EU residents? i.e. Google, Bing, Facebook, WhatsApp, MS Office and such? Are these companies' C-suite people wanted, to be charged massive breaches of user privacy?
surcap5263 hours ago
[dead]
bko3 hours ago
[flagged]
Avicebron3 hours ago
> The outcome is that very little serious technology or influential companies come out of Europe. And salaries for things like engineer are about a third of that in the US.
So your argument is abusive practices are required for the creation of influential companies, serious technology, and high paying salaries?
bko3 hours ago
No but overly burdensome regulatory bodies that are concerned about such things like how the top of my bottle cap functions and how low i set my ac temp leads to an incredibly hostile business environment and stagnant culture.
But like I said, nice place to visit for the time being.
sailingparrot2 hours ago
> nice place to visit for the time being.
Yes, because it’s a place where culture matters and where trying to change everything as fast as possible for unknown reason and handing out unlimited power to corps to e.g. level half the country to build DCs is not seen as a good outcome. The specific mindset you complain about is what makes those place nice.
bkoan hour ago
[flagged]
blauditore2 hours ago
The obsession with ACs in some places (or rather people I guess) is something I will never sympathize with. Just wear reasonable clothes for the weather, no need to cool down below 20° C. And yes, I'm going to die on that hill.
DavidSJ2 hours ago
Sometimes the temperature is much higher than 20° C, and it is very hard to be comfortable or do productive work.
blauditore2 hours ago
That's true, although having 19° inside when it's 30° outside is bad for several reasons. My office (in Europe) gets cooled down in summer to like 23°, and that's already inconvenient when wearing appropriate summer clothes. And no one is expected to wear formal clothing.
the_gipsy2 hours ago
I never set my AC to lower than 25°C. Why would you need below 20°C? Is it something about having only a single unit for the hole house/office, where it's then uncomfortably freezing in one area, just to have a normal temperature in the distant areas? Crazy.
antonkochubeyan hour ago
> Why would you need below 20°C?
For example because I literally can’t sleep well above 20°C.
bkoan hour ago
175k ppl die each year in Europe due to heat death. But I guess if you ignore that being slightly warm is not a big deal
encoman hour ago
What a shitty hill to die on.
I don't know if this is a genetic thing, but as a scandinavian who wears shorts down to like 12C, I am unable to function in >30C humid weather. Anything more labour intensive than drinking sangria on ice is not getting done. This year we had up to 37C in Denmark. If you're able to tolerate heat well, I'm happy for you, but my sleep was ruined for months this summer. Not to mention the people who literally died.
I'm investigating my options for at least cooling down the bedroom at night, because I'm not going through this nonsense again. Plastic straws are banned now and we're sorting garbage in 42 different bins, so I'm thinking that about evens it out, environmentally.
651038 minutes ago
I see the heat pump hype shaking my head thinking how people long ago use to build with mud and made walls 2-3 meter thick. It takes the entire winter/summer for the climate to get in.
The Amish hang wet bed sheets in front of the window (with a tob under it to recycle the water) not sure how well this works in the Netherlands with 95-99% humidity, it certainly wont raise humidity but evaporation might be shit.
Not every bathroom is fit for it but if there is no AC and things become unbearable I put the shower head upside down so that the ceiling and walls get wet and it rains everywhere. Then I daisy chain fans to "tunnel" the air into the bathroom. The temperature drops like a rock.
LoganDark2 hours ago
Not everyone can tolerate 20C, you know. I know people who freeze at anything below like 25C, but I myself have trouble not sweating my ass off above like 18C. I don't wear additional clothes in winter (though maybe that's simply because winter here hasn't actually reached below freezing in years).
c-hendricks2 hours ago
> overly burdensome regulatory bodies that are concerned about such things like ... how low i set my ac temp leads to an incredibly hostile business environment and stagnant culture
Like the US of A?
Also various stars have introduced more bottle cap regulations. One such state is a hotbed for inflated software developer salaries.
mitxela2 hours ago
You don't think all industrial countries have stuff like that? Do you really think the European economy is stifled by bottle caps being attached to their bottles by default? Even if it bothers you, it's a really weak attachment, you can just pull it off.
imawakegnxoxo2 hours ago
Beats companies and governments being openly hostile towards the people
You know, the thing that actually makes a country/society
Putting the needs of business over the needs of the people those businesses are actually supposed to serve is how you end up with America
[deleted]2 hours agocollapsed
croes2 hours ago
> overly burdensome regulatory bodies that are concerned about such things like how the top of my bottle cap functions
Better than a government that fears the word gay
> and how low i set my ac temp leads to an incredibly hostile business environment and stagnant culture.
You are quite a cherrypicker, aren’t you?
How about the regulation to have USB-C as a standard or replaceable batteries.
Or one of my favorites, the ban of ingredients that cause cancer.
BTW ever heard of Frauenhofer IIS or ASML?
[deleted]2 hours agocollapsed
josmar2 hours ago
If it's any consolation, all other non-California regions in the world lack the privacy protections enjoyed in Switzerland and the EU, but they still don't produce many unicorn startups nor have fantastic salaries for coders.
phatskat2 hours ago
> The outcome is that very little serious technology or influential companies come out of Europe. And salaries for things like engineer are about a third of that in the US.
Sure, but plenty of companies want to operate within the EU. While I feel any legislation will only affect their operations within the EU, having the infrastructure to operate under privacy laws there means it'll be easier if/when other jurisdictions follow suit
thih92 hours ago
> But I'm happy EU does this stuff as well, as it's a really nice vacation spot
With no Flock cameras!
[deleted]2 hours agocollapsed
[deleted]3 hours agocollapsed
Joel_Mckay3 hours ago
Unfortunately, most LLM companies always were naturally an intelligence operation on civilians, and determining if they are now state-backed seems like a irrelevant detail.
Privacy has been dead for some time now. The fact is most business people never figure out how they are exploited. The modern intelligence campaigns just made it economical to hit almost everyone regardless of scale... often under some silly pretense like terrorists wanting our underpants. =3
soulofmischiefan hour ago
Are you equally happy that the EU is attempting to mandate backdoors into technological platforms and outlaw private encrypted communication?
dspillettan hour ago
Copypasting my reply to someone who made almost exactly the same point in a sibling comment earlier:
Which has nothing to do with the stalking of the adtech industry, unless you are suggesting that the EU might sell access to the keys to the likes of OpenAI [though you are not wrong that encryption backdoors are a backwards step on individuals rights to privacy]
Things could be worse. It could be like most of the US where there are both no (or at least far fewer) protections against invasive behaviour of private companies and the government actively trying to backdoor private comms.
einpoklum15 minutes ago
> Which has nothing to do with the stalking of the adtech industry
It has a lot to do with the practices of the adtech industry. If privacy is protected and upheld vis-a-vis the government (or meta-government in case of the EU), it may be upheld vis-a-vis private corporations and other governments. But if the government likes to be able to spy on its citizens, it will not foster mechanisms, practices and a culture of private communications.
But - I agree that it could be much worse.
slig41 minutes ago
And the sane world is fighting the EU BS with geo blocking.
Just set up your user agent to work as you wish, isn't that simpler than have unelected, technologic dumb bureaucrats writing laws that are complex and don't solve the issue?
altern82 hours ago
I don't know if the destruction of many industries in the EU--including manufacturing--can be called an annoyance.
All the EU bureaucrats can do is regulate, that's why it's so difficult to do business in the EU and that's why there is so little innovation over here. If Microsoft and Apple were started in the EU they would've been shut down within a week because you can't operate from a garage.
I guess that every once in a while this might have a positive outcome for consumers, a broken clock is right twice a day.
schubidubiduba2 hours ago
I'm sure Microsoft and Apple could have been able to afford a cheap office given their parents' generous financing.
And, regarding the original topic, we wouldn't have many of these privacy issues if the US had not strategically failed to regulate its obnoxious tech monopolies
goobatroobaan hour ago
I don't see how that's relevant? Regulation might have limited some innovation in tech, but gdpr does not affect any of the dying industries. That's more from competition with china, companies with too much interest in giving payouts to shareholders than to innovate, and US financial industry buying most of the best players
duhhhhh1212an hour ago
https://www.pangram.com/history/c3ad864f-2a50-4785-a0ef-71f2...
why not use your own words? If you are gonna ai generate this blog, just post the prompts instead.
handoflixuean hour ago
There's a certain irony in linking to someone else and then saying "use your own words". If we follow that, we get a pretty obvious answer: sometimes someone else can express it better and faster.
Most people do not, in fact, want to read raw prompts.
devilsdata4 minutes ago
If you can't be bothered writing it, why should I be bothered reading it?
crmd40 minutes ago
It’s misleading to post model output on a blog, especially when the about says
> This blog is where I write about what I find.
Why not simply include a disclaimer that it was AI model output not his own writing? Because humans don’t like AI writing and the article wouldn’t be featured on as many tech news sites. Hence the sin of omission, the choice to mislead.
scared_together27 minutes ago
Are you referring to the Pangram link? I’d consider that akin to a reference supporting the comment’s point, not a substitute for the comment’s point.
> Most people do not, in fact, want to read raw prompts.
I wonder if this is really true, and if it will remain true for long. Have you observed someone read another person’s raw prompt? Or observed someone submit both their prompts and their LLM output for review?
Personally I’d be curious about the prompts for a lot of top HN articles which are LLM-generated. It would say a lot more about the human operator’s intent and thinking process compared to the LLM output.
A coworker who spoke English as a second language once screen shared their Claude session during a code review, and it was interesting that their prompts were all in their native language. The guy wasn’t writing an article, and I didn’t understand the prompt anyway, but I still found it interesting as a glimpse into how he uses LLMs.
For this particular article, if the prompt was initially a series of bullet points that wouldn’t be so bad. If there were multiple prompts spent editing and rearranging the article that would be an unusual work by pre-LLM standards. However I’d suggest that instead of dismissing the idea, we could embrace “raw prompts” as a kind of new medium, to cross the divide between pro-LLM and anti-LLM readers.
Sharlin23 minutes ago
Having an LLM generate major parts of text that you (whether explicitly or lying by omission) claim as yours is dishonest and plagiarism, and it baffles me that many people just don't seem to mind or see anything problematic about it.
siquick35 minutes ago
> just post the prompts instead.
Why would anyone want that?
duhhhhh121216 minutes ago
Because I want to read the author's words, not claude's, chatgpt's or grok's.
Note to folks who have this same thought (seems like many given other comments). Why are you on this site if you aren't here for human-created content? If you want AI generated blogs/posts there are plenty of sites like linkedin, twitter, chatgpt, and claude that will give you meaningless content with a press of a button.
abhis3798an hour ago
How is this adding to the discussion? The post in itself is quite informative.
duhhhhh1212an hour ago
Do you constantly want to be reading ai-generated content on this site? If so, why not just stay on chatgpt.com and ask it to generate what hackernews.com would look like today? It's adding to the discussion because I feel like the author broke a social contract by probably putting less effort into writing this than I did reading it.
Sharlin19 minutes ago
Having an LLM generate major parts of text that you (implicitly or explicitly) claim as yours is dishonest and plagiarism and should be brought to readers' attention, and it baffles me that many people just don't seem to mind or see anything problematic about it.
ljm37 minutes ago
Why would you want n people to compute an AI prompt independently instead of reading the output once? And why would that be better?
At least criticise the article on merit and not some 'let me google that for you' high horse. If it's slop it's slop, but let the votes speak for that.
xmprt28 minutes ago
> OpenAI's ad collector at bzr.openai.com sets a cookie called __obi, scoped to .openai.com
This sentence is way too much detail and it's literally the first thing you read. I can pick apart most of the sentences in the article. Another one:
> Across 932 decoded sync tokens, 736 carried subject_type: account_user and 196 carried anonymous
This sentence is pointless. What matters to proving that "It works when you are logged out" is to show that the identifier is stable. Why does the reader care about the actual counts.
AI has a tendency to do this which makes AI generated text a lot harder to read. The raw prompts likely don't have the specific websites and cookie names because that's not relevant to the reader or writer for that matter - it's a footnote at best.
scared_together19 minutes ago
Not everyone would actually send the prompt to an LLM. Some would have the opportunity to see the prompt as its own artifact, devoid of LLM-generated “hallucinations”.
> let the votes speak for that.
The comment you are replying to got a fair number of votes too… Having somebody run a Pangram check saves n people the trouble of doing the same.
sligan hour ago
Why comment if you have nothing good to say?
angoragoats23 minutes ago
Hello Pot, I would like to introduce you to Kettle.
mavsman5 hours ago
To me, this quote just about sums it up:
> The mechanism is standard adtech. What has no precedent is running it on an AI chat product.
As someone who has been well aware of this mechanism for quite some time, I still feel icky anytime I re-read the details of it.
What a time to be alive.
jsrozner5 hours ago
People think they're interacting with an "intelligence," when actually they're just getting a maximally optimized Weizenbaum feed. We're living through the sloppification of the human mind.
See e.g., https://www.science.org/content/article/ai-chatbots-are-beco...
brianleb3 hours ago
Could you define (or link) to what "Weizenbaum feed" means/references? Too obscure for me but I'm interested. Thanks.
fweimer2 hours ago
Likely a reference to ELIZA: https://en.wikipedia.org/wiki/ELIZA
handoflixuean hour ago
Are there really people that can't tell the difference between ELIZA and something that can solve open Millennium Prize Problems in math?
jsrozner10 minutes ago
It turns out, oddly enough, that it's possible for it to be both. AI can simultaneously be used to destroy the commons with slop and also make contributions to new math (though isn't the jury still out on whether part of the idea was stolen from human mathematicians?)
handoflixue8 minutes ago
What does "destroy the commons with slop" have to do with ELIZA comparisons?
joquarkyan hour ago
Their ego doesn't let them see the difference.
mapontosevenths17 minutes ago
Or perhaps their wallets. There are a lot of programmers here. Some of them think that AI is the death of their profession, rather than a change in it.
"It is difficult to get a man to understand something when his salary depends upon his not understanding it." - Upton Sinclair
jsrozner10 minutes ago
I, uhm, think this idea would apply in both directions.
trial33 hours ago
humorously, my regular iPhone on a residential home network failed the cloudflare AI bot detection and i can’t read that article
mitxela2 hours ago
People don't believe me that Cloudflare blocks more humans than bots. They see in the dashboard "number of bots blocked" and it's like their brain turns off.
dylan60437 minutes ago
If you don't also display how many humans were blocked, how they know?
ben_w4 hours ago
What's the old quote from WW2?
I couldn't help but notice how each successive headline reporting our glorious victories seemed to draw closer to Tokyo.
Well. I can't help but notice how each successive headline reporting how this "scam"/stochastic parrot/"scare quotes intelligence" seems to be solving more and more things that were but a few years ago widely regarded as being indicators of high intelligence.
Being highly convinving is one of the things on that list.
moth113 hours ago
Nobody is denying that it's effective. They're denying intelligence
A programming contest has a problem where given N < 10000, do something hard like come up with the number of primes less than N
You can come up with all sorts of algorithms that do intelligent things. But the most effective solution is to use metaprogramming to make a massive switch statement that contains all the answers
fasterik2 hours ago
Are they denying intelligence, or are they redefining it in such a way that only humans can be intelligent? Can you come up with a definition of intelligence that would apply to crows and ant colonies, which are obviously intelligent to some degree, but not the current generation of AI systems?
mitxela2 hours ago
Nobody knows what intelligence is. We've recently discovered a lot of things that it isn't.
fasterik2 hours ago
Intelligence is a word we invent to describe things we see in nature. We don't "discover" intelligence like it's some natural resource. To say we know nothing about it is also a bit strange. Cognitive science has been studying it for decades. Of course it's hard to give a precise definition, but it's related to capabilities like abstraction, reasoning, planning, problem solving, etc.
infinite_spin2 hours ago
Why would a set of dictionary definitions not suffice?
mitxela2 hours ago
Those are distillations of existing knowledge. They are necessarily behind the status quo. "You can't call this newfangled contraption a computer, because a computer is a person!"
handoflixuean hour ago
> They are necessarily behind the status quo.
That seems like a really bizarre way to describe a tool that solved an open Millennium Prize Problem. They are, empirically and repeatedly, ahead of the status quo.
So if your argument depends on them being behind the status quo, reality has already disproven it multiple times over.
infinite_spin2 hours ago
> Those are distillations of existing knowledge.
Definitions are "formal statements of the meaning or significance of a word, phrase, idiom, etc" (https://www.dictionary.com/browse/definition)
> They are necessarily behind the status quo.
The existing state or condition would be what is written in the dictionary, not whatever personal definitions you've constructed.
> "You can't call this newfangled contraption a computer, because a computer is a person!"
Seems like a straw man. A computer is not a mammal, no matter how much you twist a set of definitions.
quicklime36 minutes ago
> A computer is not a mammal, no matter how much you twist a set of definitions.
I’m not the person you replied to, but I believe they’re referring to the occupation of “computer”:
https://en.wikipedia.org/wiki/Computer_(occupation)
So yes, at one time all computers were mammals.
The people who write dictionaries generally take a descriptivist approach, that’s why slang terms enter the dictionary after they start to become popular.
The state of the art of human knowledge would be another step ahead of the common use of any language.
infinite_spin30 minutes ago
That's an interesting take, and I can see how "computer" could refer to a human a hundred years ago, but they also mentioned "status quo", which should indicate that a reasonable person should use a modern definition.
quicklime18 minutes ago
Again I’m not the person who wrote the comment, but I think they were exaggerating for effect and maybe lost the audience in doing so. While “computer” has meant the same thing for many decades now, the term “intelligence” really does seem like a moving goalpost?
ben_w2 hours ago
How many examples you need to get good.
Don't misunderstand: I'm happy saying AI models "think" or "have learned a thing", and for in-context learning I'd call them smart even by this definition…
…but also, any living creature that needed as many examples as machine learning currently needs, would starve to death before figuring out how to eat.
While training, machine learning processes (not just LLMs, also applies to e.g. self driving cars), are really really stupid and only make up for this by being really really stupid really really fast.
To what I wrote upthread: the "victories" of humanity over machine keep getting closer, but we have yet to wake up one day in great confusion as we find an entire city is no longer in communication with anyone, nor finding ourselves in a state of utter disbelief when the reports come in that the city stopped communicating because it is entirely gone.
keypusher2 hours ago
Millions of years of evolutionary knowledge hard-coded into human systems, then it still takes 15+ years of us learning by example before we start to come online and be able to generalize solutions from a limited set of examples. I'm not sure this is as strong of an argument as you think it is. It also doesn't really matter when "we are trained differently" has no direct bearing on the end result.
ben_w2 hours ago
We invented controlled fire perhaps a million years ago; at a generation gap of 25 years, that's 40,000 opportunities for evolution to pass on a mutation that does anything. Written language is around 210 generations old, the capacity to read and write isn't present in our nearest living relatives amongst the primates, and our various languages are wildly different to each other: the skill itself isn't evolved, though the capacity to learn the skill is.
If humans learned like ML systems learn, (biblical) Methuselah would still have been failing the Sally-Anne test on his supposed deathbed at 969 years old, like some of the smaller early LLMs did.
> It also doesn't really matter when "we are trained differently" has no direct bearing on the end result.
The question was to ask for a definition such that AI could still count as "not smart" compared to humans. This fits.
It's also why they're spiky intelligences, which I'm happily using right now to write code for me, but also do not trust in the slightest to identify the weeds in my garden. These submarines sure do swim fast*, but they're also very much disqualified for the Olympics.
fasterik2 hours ago
If we're including the training process and not just the final product, why shouldn't we include the billions of years of natural selection encoded in DNA sequences?
godelskian hour ago
We do.
There's a lot of innate knowledge but all neuroscience demonstrates how incredibly flexible the brain is. Brains constantly learn and rewire.
Here's a few things that I think show how crazy it is AND stress those points
  - people that have had corpus callosotomy (brain cut in half) *may* be indistinguishable from a normal person. Depends on how young you were when you underwent the procedure
    - true for most brain injuries
    - can even include the frontal cortex
  - you can learn to ecolocate
  - people with Aphantasia are indistinguishable from others
  - people without an internal monologue are indistinguishable from those with one
  - people can learn to use prosthetics
    - even without disabilities
    - or look into MRI scans with tool use
We are constantly learning. You aren't just born with your knowledge and it stays static. We are extremely proficient at metalearning (learning how to learn, few shot learning, zero shot learning [0,1]). Our brains are constantly rewiring, able to heal from traumatic damage.
I could go on and on. Does information pass down through genetics? Of course! But that's far from the whole story.
I'm tired of people trying to make AI sentient by making humans robotic. Stop trying to trivialize everything and be okay not knowing the answer to everything. You're human, you're designed to learn and explore, not sit and argue from an armchair
[0] and I mean these in the original sense. Not in the sense that you train on a billion examples of labeled animals and then congratulate yourself on your ImageNet-1k held out test performance. That's not zero shot, that's just a test set
[1] I can literally make up words and you'll understand them. Or use words in novel ways. That's literally how slang works and how new words come to be. Don't be a walibanut ya glufus. Read some SciFi
ben_w2 hours ago
Because our evolutionary environment doesn't contain cars, poetry, calculus, Star Craft, hamburgers, touch screen computers, or doors, and yet we are able to learn these things with (relative to a computer) very few examples.
Most of the effort of evolution was making cells work at all, and even then it's a bit weird, e.g. no plant or animal produces vitamin B12 and we all get this from some bacteria and archaea.
And evolution is kinda hard to time right: bacteria can reproduce in minutes, humans in decades, but only mutations that survive reproduction can be passed on. This makes it even starker as a difference: bacteria had order of 1e13 generations to become multicellular, while human DNA had about 40,000 generations to cope with fire, 220 generations for evolution to do anything with the invention of the wheel, and one generation to cope with the invention of Minecraft.
The analogy here would be: DNA is to our brains like a VN replicator bootstrapping a computer all the way up to a bare-metal-no-OS untrained model, and perhaps a few crude "hard coded" modules like a smiling-face-detector. It's a lot, but it's also missing a lot. If biology used the models and training processes that are state of the art in ML, it would take around a millennia to talk like a child and still fail the Sally-Anne test, and million years or so to pass a degree.
fasterik2 hours ago
I think you're underestimating how much knowledge about the world is encoded in human DNA, especially in the structure of the human brain at birth. It also depends how we count the "operations" used to train a human adult, even if we ignore the evolutionary history.
I'm still going to deny the premise of your argument, becasue I think we should define intelligence in terms of capabilities. If a system can discover a cure for cancer or solve P vs. NP, it doesn't matter how many FLOPs it took to train.
ben_wan hour ago
I can literally point to how much information is encoded in our DNA, because it's four bases (so 2 bits per base pair) and ~3.1 billion base pairs. 6.2 gigabits total, or slightly less than 1 gigabyte.
A 1 gigabyte LLM isn't going to impress anyone with what it can do.
About 99% (depends who you ask) of our DNA is shared with our nearest primates. Like us, they can learn to use touch screens, but also like us they won't find touch screens in their natural environment. Dogs can be taught to drive cars (just about), but again, not natural environment.
> I'm still going to deny the premise of your argument, becasue I think we should define intelligence in terms of capabilities. If a system can discover a cure for cancer or solve P vs. NP, it doesn't matter how many FLOPs it took to train.
We can define it in either way. I think both are valid, because plenty of people mean each of these two things when discussing AI in particular. As I referenced in the other branch, these submarines sure can swim fast.
But at the same time, they have a lot of gaps. This is because some experience needs the real world: just as nine women can't make a baby in one month, a transistor running a million times faster than a synapse can't make a month-long cancer experiment happen in 2.6 seconds.
This dependency on data, and that state of the art ML is bad in specifically this way, is why Tesla's self-driving cars, despite having had around a trillion miles of real-world experience today, still come with steering wheels (even at least some of the Cybercabs, despite the big thing of this model supposedly being not needing them, though with Musk and his promises you should only count the Cybercabs when they actually ship and not just press releases).
fasterikan hour ago
Note I used the word knowledge, not information. A random string can also contain 1 gigabyte of information.
Imagine an alien that matches your abilities across every domain, but has a 10 billion year training period, something many orders of magnitude more expensive than an LLM. I simply don't believe that alien is less intelligent than you.
We also don't expect humans to be competent in every domain. Most humans suck at most things. We will usually call someone intelligent if they excel at solving problems in one or two narrow domains.
ben_w39 minutes ago
Information is an upper bound on knowledge.
> 10 billion year training period, something many orders of magnitude more expensive than an LLM.
I'm saying both definitions are valid definitions, they both point to important and different things: skill now, vs. how hard it is to get new skills. Some would describe it as "crystallised intelligence vs fluid intelligence".
I think it's important that any arguments are over the thing in dispute, not the label for that thing. Don't mistake the map for the territory.
Anyone who says "AI is stupid" by the first definition, what it can do, I think is making an error: they are already wildly super-human in at least some areas, if not generally.
Anyone who says "AI is stupid" by the second definition, how many examples they need, I agree with: there is a lot they are not currently able to learn even though it is easy for us, because the data they would need to do the learning on does not exist at the scale they need.
Also note: examples, not years. An alien intelligence whose synapses trigger 10 times faster or slower than mine (or ten million times faster or slower than mine), but who gets as much as I do out of each book or conversation, is my equal by the second definition.
fasterik5 minutes ago
I wouldn't say that information is an upper bound on knowledge because we don't measure knowledge in bits. The number of possible sequences of N bits is 2^N and knowledge involves selecting the sequences that are useful in some way. I don't know how to quantify it, but in principle it could be much larger than N.
I don't think I agree with your characterization of the second definition. Time scales matter. It's not much use to be able to solve human-scale problems if it takes millennia. And it only takes months to train an LLM to the level that it can solve cutting-edge math problems.
lambdaonean hour ago
This is classic AI goalposts-moving.
OK, they can play chess, but that's not real AI - can they write poems? OK, they can write poems, but that's not real AI - can they compose music? OK, they can compose music, but that's not real AI - can they translate languages? OK, they can translate text, but can they do maths? OK, they can do maths, but can they solve a Millenium Prize? <-- we are here
mopsi4 hours ago
It was Berlin and not Tokyo, I believe. Germany kept producing newsreels until the very end. Many of them are now on Youtube, a very interesting watch on how to frame things positively.
ben_w3 hours ago
I've heard many variants; Paris in an earlier war, too.
I try to keep an open mind about propaganda fooling me today; the people who were fooled in the past often were not fools themselves.
dylan60434 minutes ago
In the past, there were not the avenues of finding alternate sources for news. While those avenues are present today, it also allows for additional sources for propaganda. So are we any better today or not???
ben_w15 minutes ago
Not. A thousand cable channels all licensed by a government, is much the same as five broadcast channels licensed by the same government.
A million YouTubers grinding The Algorithm while secretly sponsored by various world governments, isn't much different to a thousand well-placed gossipers secretly sponsored by various world governments.
godelskian hour ago
> the people who were fooled in the past often were not fools themselves.
Being fooled doesn't make you a fool. But being unwilling to change your mind does. Being unable to admit you don't know or don't have enough information to make a strong opinion makes you a fool too.
Propaganda wants to take shortcuts, to simplify things. To trivialize. "It's so easy, you just..." because the fool is the person who already knows, the person who has nothing to learn, the person who thinks they're better than everybody else.
fiu104 hours ago
We need a downfall parody: "Hitler uses Openclaw".
datsci_est_20154 hours ago
Wow, that quote goes hard.
I’m reminded that almost no one beyond a select few knew high up in the military and around the emperor knew how badly the Japanese were defeated at Midway.
Paternalistic. Arrogant. Shameful. And deeply engrained in the Japanese cultural zeitgeist (of the early-mid 20th century).
Edit: I guess it’s commonly attributed to a German citizen, but their cultures mirrored each other. Fascism falling under the weight of its own propaganda.
gxs3 hours ago
Or both, you know. An intelligence that also spies on you
Why is it so black and white?
spying_lg_tv3 hours ago
How are you so dumb at this point in the game? It’s not “intelligent”…
gxsan hour ago
Create a new account to be able to say what you just said
Your kind is what makes the internet shit, not AI
clickety_clack5 hours ago
Whenever I say something like “that’s a cool feature, but to do it you would have to build spyware”, everyone else is just like “the cat is out of the bag ¯\_(ツ)_/¯”. (I don’t build spyware, or work on projects that do).
It blows my mind that people don’t care about the world they are building with this stuff. It’s a real tragedy of the commons. People see these collaborators from different wars and regimes and think “I’d stand up against the bad guy”… well I’ve got news for you if you build spyware, you are not the person you think you are.
kltlp4 hours ago
This is the best retort to the bag-escaping cat ever:
https://gowers.wordpress.com/2026/09/17/why-i-didnt-sign-the...
"Nothing is worse to the demise of a society, than people who want to convince you that the cat is out of the bag and will not go back in, while the cat is being violently shook out of the bag at the same time."
GolfPopper3 hours ago
A great quote, thank you for sharing. It captures much of the five stages of denial (summarized below) in a much pithier form.
There's nothing in the bag.
The cat will never get out of the bag.
It wouldn't be a problem if the cat was out of the bag.
We cannot possibly keep the cat in the bag.
Putting the cat back in the bag is not worth trying.
anonymous9082134 hours ago
Motion to start a political platform for cats in bags. Our message is simple: Put the cat in the bag. Keep the cat in the bag.
TeMPOraL4 hours ago
Don't force it out of the bag if it doesn't want to leave.
rapind3 hours ago
> if it doesn't want to leave.
This is where the lawyers find the loophole to get the cat out of the bag.
wingworks2 hours ago
Turns out, there was a hole in the bag.
godelskian hour ago
That's how bags work
TeMPOraL2 hours ago
That was originally meant for a carry loop, but alas.
ok1234563 hours ago
No, the greatest is from the Sweet Smell of Success: "The cat's in the bag. And the bag's in the river."
mitxela2 hours ago
And the river's in the canyon and the canyon's in the plateau and the plateau's in the volcanic shield and the green grass grows all around, all around, and the green grass grows all around.
mat_b4 hours ago
> It’s a real tragedy of the commons
Seems more like a real tragedy of private enterprise.
We used to assume that the surveillance world would be built by government (1984). But it turned out to be equally likely to be built by the free market.
sssilver3 hours ago
Turns out the entities you control / regulate less, tend to do things that are less in your interest and more in their own.
TeMPOraL4 hours ago
The government has few uses for total surveillance, and almost all are obviously bad. Private enterprise has a million uses, most of them various degree of bad, but as a society we've been blind to this kind of badness for many decades now - for at least as long as lying in the face of your fellow humans and trying to hurt them materially has been considered a respectable profession.
mitxela2 hours ago
Well, currently the free market is the government, while the nominal government is something less powerful than that.
mitxela2 hours ago
Well, some people care and some don't. The people who care don't get to work on the technology.
brookst4 hours ago
I'm pretty unhappy with this, but are ChatGPT or Facebook really "the commons"?
ben_w4 hours ago
They're each in different grey areas that were previously the commons.
Facebook didn't invent "talking to friends" or "showing adverts", but made itself "the place" hard enough most of the advertisers and most of the people intermediate through it.
OpenAI didn't invent "asking questions and recieving answers", not even "from an agent who knows which sites to search on your behalf"; but it is competent enough that I might have it read 50 times as many pages in a day as I myself would have read, and the sites' owners don't get real eyeballs looking at ads during this. (In my case, adblock even if I did it manually; but apply this massive increase in page hits to everyone who has their LLM research stuff).
clickety_clack3 hours ago
I think the internet in general is a commons and I should be able to browse it without being spied on.
There should be general standards for what individual apps and websites should be allowed to do. There should be an expectation that the purpose of an app is what it does, i.e. a social connection app shouldn’t be an ad platform that suffers users insofar as they provide useful data to sell to advertisers.
nilamo4 hours ago
Common people work there and built the tools. At any point, they could have chosen not to. Or told the boss guy it wasn't plausible. At the end of the day, we're choosing and building the world we're in, while also loudly complaining about what we choose to do.
Blaming a corporation takes away all the agency the workforce has.
applfanboysbgon4 hours ago
I think any free platform with a billion people on it is, de facto, a commons. It would be great if we as a society acknowledged this and had come up with some better means of stewardship because the status quo is obviously heinous, but we've been happy to hand over absolute control of public discourse to a few trillion dollar tech companies.
bluefirebrand3 hours ago
> It blows my mind that people don’t care about the world they are building with this stuff. It’s a real tragedy of the commons.
When I ask people about things like this, I hear a lot of "If I don't build it, someone else will"
My goal isn't just to refuse to build this stuff, it is actively to resist the people who are.
I don't have much influence though
charcircuit3 hours ago
Your issue is you are defining spyware too broadly. This is not spying on users, but rather 2 companies partnering and sharing data to result in either a better ads system or better understanding on how ads are performing. This is a positive value to society and the commons. Wasting space in a site or app with an ad that won't convert is the true tragedy of the commons. It's a waste of time and money for all parties involved.
infinitezest3 hours ago
Can't you see? We're just trying to build a better cigarette! Flavored to your specific tastes! You'll thank us, you'll see!
c223 hours ago
No ad has ever converted me yet the ad networks keep showing me ads.
gloryjulio3 hours ago
A lot of the Meta/Google folks jumped ship to Openai/Anthropic. This kind of work is expected
buchodi4 hours ago
[flagged]
robots0only14 minutes ago
This is incredibly sad, with google you can atleast use the argument that search was free (which is still weak IMO). But with OAI collecting indiscriminate data on paying customers is just incredibly sad.
luke54414 hours ago
MDN lists how different browsers prevent this: https://developer.mozilla.org/en-US/docs/Web/Privacy/Guides/...
Firefox, Brave and Safari do. Chrome and Edge do not.
mokrean hour ago
That’s not fully protect you. They still can match short living third party identifiers with their domain cookie or device_id from app. It is not 1-1 matching but works relatively good with modern itp.
skybrian4 hours ago
Not an accurate summary. That link actually says:
> Google Chrome doesn't block third-party cookies by default, only in Incognito mode, or when users explicitly set it to block third-party cookies via chrome://settings.
Looks like the settings let you block all third-party cookies and add exceptions for specific sites, which seems a bit awkward but could be made to work.
Alternatively, you could run OpenAI in its own profile, or look into what extensions might do.
gruez3 hours ago
>Looks like the settings let you block all third-party cookies and add exceptions for specific sites, which seems a bit awkward but could be made to work.
The fear over blocking third party cookies breaking stuff is severely overstated. I have it disabled by default and I don't think I've ever seen any website breakages. The most is office365 nagging me to click on links so it can authenticate across domains.
nicce4 hours ago
I think that if they don’t block by default, is quite significant. Chrome + Edge has superior marketshare and then add the % people who have no idea what these mean and don’t change defaults.
Andrexan hour ago
I was going to say, wasn't this supposed to be the default in Chrome by now? But Google reneged on it two years back:
https://www.cbsnews.com/news/google-third-party-cookies-chro...
This disgusts me more than any of their recent news. There needs to be a lot more pressure on them to phase this out.
Maybe this article will be the small snowball that gets that started...
troupo3 hours ago
> Google Chrome doesn't block third-party cookies by default, only in Incognito mode
And the focus on cookies only is also intentionally misleading. Tracking is not just cookies. Chrome will track you in Incognito mode.
1saadcodes4 hours ago
The technology isn't anything new but, it's the context that makes it so uncomfortable.
People have very different "expectations" of privacy when they're having a conversation with an AI VS when they're browsing something like Facebook
Not to mention Facebook is free whereas you pay for a GPT subscription
ben_w4 hours ago
I'm old enough to remember when people had expectations of privacy on Facebook, when the discovery that they didn't made for schocked headlines.
palata3 hours ago
Back then I didn't have expectations of privacy, I think. I just didn't have a notion of privacy. I didn't think the internet was hostile, I believe?
[deleted]2 hours agocollapsed
bigyabai4 hours ago
You know, Facebook, built by the guy who scraped college databases for personal information without the student's permission.
There was never any expectation of privacy if you knew Zuck's history. Facemash almost got him expelled for violating individual privacy.
ben_w3 hours ago
That's the trick: in the early years, most people didn't know Zuckerberg's history.
bigyabai2 hours ago
Caveat emptor, the saying goes. If people don't have an appetite for privacy, don't expect them to take a principled stance based on outrageous headlines.
It's not a coincidence that federally backdoored spyware like Windows is the most popular operating system in the world. I too remember the shocked headlines of the Snowden revelations, and ten-plus years later I work shoulder to shoulder with people that couldn't possibly care less. There is no expectation of privacy, HN too quickly extrapolates it's own virtue signalling to normal people that enjoy using spyware like TikTok, Facebook and Windows.
einpoklum12 minutes ago
> Not to mention Facebook is free whereas you pay for a GPT subscription
Recalling the now-old adage: Facebook is only free if your time and privacy are worthless.
throwaway21945043 minutes ago
I don’t think there is any consistency in behavior. People react viscerally to the unproven belief that the Facebook app records conversations. They’ll also happily buy big TVs despite the fact they’re very much listening to you and we have solid evidence that it’s for ads or residential proxying. Most people have no idea how ads “follow” you, or how companies can figure out what you talked about by connecting the dots from other user metadata.
shepherdjerred4 hours ago
ChatGPT is also freely available
exceptione5 hours ago
The surveillance economy hits again. The only business model they can think of. Combined with state capture this gives unprecedented power over the Average Joe, who will hand his life, his soul and his vote to Big Brother without a thought.
riazrizvi21 minutes ago
I noticed that. I'm getting ads now based on conversations. I'm okay with it. I don't mind relevant ads.
Legend24405 hours ago
So basically the same kind of tracking that Facebook, Google, etc have been doing for decades?
gentlewater3 hours ago
Which has really only been accepted because 99% of people don’t understand how it works. Hard to be outraged by something you can’t see or understand. In my book, the practice is akin to malware. I recently opened a website for an AI service in incognito mode, because I didn’t care to have it in my search results. Despite avoiding third party cookies here, the site still fired off a tracker to Meta, who then correlated my home IP address with my Facebook account, and filled my feed with ads for this AI service. When I was tracked like this despite a somewhat informed defense, which defense do normal people have against this? None.
emptybits5 hours ago
Similar, yes, but some people are paying OpenAI to be part of this business model, unlike typical free-riding Google and Facebook users.
theptip3 hours ago
If you pay OpenAI full price, this machinery should never be used. The only paying customers getting ads are the “ad supported” tier.
I think you can easily imagine a future where the subscription model token subsidy ramps down and is replaced by ads, but it’s important to use precise language about the current state of the world.
troupo3 hours ago
Derogatory "Free-riding users". "Free riding users" should have the same privacy as the paying ones.
rangestransforman hour ago
Will the government pay OpenAI to run an ad-free free tier?
[deleted]5 hours agocollapsed
rvz3 hours ago
Yes. But there is no surprise given that OpenAI hired lots of ex-Meta and Google employees for that reason.
latexr3 hours ago
https://en.wikipedia.org/wiki/Whataboutism
The fact that others do the same doesn’t make any of the cases excusable.
sigzero5 hours ago
Why does ChatGPT need to know that? That should be illegal.
eli4 hours ago
Something like it is basically a requirement if you want to see digital ads. Advertisers want to know how many people who saw/clicked their ad went on to make a purchase.
Safari and Firefox should isolate the cookie by default.
driverdan4 hours ago
> Something like it is basically a requirement if you want to see digital ads.
It is not a requirement and no one wants to see ads.
gruez4 hours ago
>Safari and Firefox should isolate the cookie by default.
That's what firefox's total cookie protection (enabled by default) does.
troupo3 hours ago
> Safari and Firefox should isolate the cookie by default
Doesn't mean you won't be tracked by about 15 other means.
kibwen4 hours ago
>> Why does ChatGPT need to know that? That should be illegal.
> Something like it is basically a requirement if you want to see digital ads.
So to summarize, yes, it should be illegal.
dofm4 hours ago
To make the only consumer revenue that will really ever be available.
Remember they once predicted it would be 50% of their income.
This is the only way they get there.
charcircuit4 hours ago
Attribution is a core part of building an ads system.
jsrozner5 hours ago
Because it's another surveillance adtech company from SillyCon Valley. Duh.
SoftTalker4 hours ago
It turns out that the only way to make money online is ads.
Nobody is going to pay for ChatGPT. They'll just use the ad-infested version, like they do everything else online. Well some people will pay, but not enough to justify the insane amounts of money being poured into it by investors.
jsrozner4 hours ago
A bigger problem is that it will be impossible to know when you are seeing an ad: political groups (or the government, perhaps) will partner with openAI to subtly express different values.
It's still an advertisement, and the underlying marketplace is similar (pay for access to change behavior).
The best uses of AI will be surveillance, propaganda, cyberterrorism, and automated military tech.
See, e.g., https://www.nytimes.com/2026/09/18/technology/iran-china-aut...
andsoitis4 hours ago
> The best uses of AI will be surveillance, propaganda, cyberterrorism, and automated military tech.
I think it is more insidious than that. AI shapes how people think not just what they think.
Terr_2 hours ago
[dead]
[deleted]2 hours agocollapsed
coliveira4 hours ago
Governments will also pay for the tracking capabilities, as they're already doing to Google, Amazon, Facebook, etc.
SoftTalker4 hours ago
Yes, I should have said "ads and tracking" good point.
varencan hour ago
For browsers that implement strict cookie partitioning, the privacy concern is moot. With this, the cookie jar that's used when chatgpt.com is a 3rd party site is completely separate for the jar used on the 1st party site. So your chatgpt.com account can't be linked to your ad views.
Since this has been standard ad tech for awhile, browsers have reacted to this to implement cookie partitioning for exactly these privacy reasons.
tgsovlerkhgsel5 hours ago
This is why you use Firefox that keeps the cookie jars separate (by default, AFAIK). That should prevent this specific implementation, shouldn't it?
JoshTriplett5 hours ago
Yes, it should. But this is also why you use uBlock Origin to block tracker scripts.
consumer4513 hours ago
Firefox is my daily on desktop, but on mobile it's Safari. I finally got around to installing uBlock Origin Lite on iOS. I used to run the Firefox version on iOS, but that was discontinued long ago, and I never replaced it. I feel like a bit of an idiot for not doing this sooner.
https://apps.apple.com/us/app/ublock-origin-lite/id674534269...
latexr3 hours ago
> I feel like a bit of an idiot for not doing this sooner.
Don’t beat yourself up, uBlock Origin on iOS is only four months old.
tgv5 hours ago
There are other ways to track. Containers offer a bit mote protection, but the IP address is still visible (unless VPN).
armadyl3 hours ago
Containers don’t offer a benefit over normal browsing for this, Firefox already blocks and isolates third party cookies.
tgv3 hours ago
Caching is also a tracking signal.
mitxela2 hours ago
Caches are also isolated. One of the reasons you shouldn't use a JavaScript CDN any more.
AznHisoka5 hours ago
And the number of websites with ChatGPT ad trackers is on track to be doubled from last month.
according to Bloomberry: https://bloomberry.com/data/chatgpt-ads/
Avshalom5 hours ago
Yuuup. tracking consumers and finding spending correlations to exploit was the entire reason for the "Data Science" and "ML" pushes that got us here.
nelsonfigueroa2 hours ago
why is OpenAI wasting their efforts on implementing ads if they are apparently close to AGI?
jrfloan hour ago
I would assume the skill set for implementing ads is quite different than the skill set for developing new models, so it’s quite reasonable to expect different teams are working on each
smokelan hour ago
AGI will most likely have told them that this is the cheapest way to become rich.
threecheesean hour ago
This might help:
``` ||openai.com^$cookie=__obi ```
Does this look right? AdGuard style.
lambdaone2 hours ago
Incredibly creepy. I'm amazed they don't have any idea quite how user-hostile this is, or the reception it would receive.
emerongi4 hours ago
https://tinfoil.sh/ - ultimately there is no guarantee that the LLM provider isn’t spying on you, but at least tinfoil claims to be unable to do so.
DevKoala4 hours ago
> The mechanism is standard adtech. What has no precedent is running it on an AI chat product.
Doesn’t Gemini or whatever Meta’s agent is do this too?
Jazgot4 hours ago
Time to start having separate container for every domain. I'm pretty sure this should be possible in Firefox.
gruez4 hours ago
Firefox (effectively) already does that by default.
https://support.mozilla.org/en-US/kb/introducing-total-cooki...
[deleted]3 hours agocollapsed
LtWorf2 hours ago
Doesn't really matter, they can track you in several ways.
mitxela2 hours ago
Because at least one mechanism of tracking still exists we should just give up on blocking any of them?
einpoklum21 minutes ago
No it doesn't, if you:
1. Never register with OpenAI/ChatGPT, and
2. Strongly block ads, e.g. using uBlock Origin + EFF Privacy Badger. Yes, those don't work on Chrome, Edge and other Chromium-based browsers.
Also, even then - ChatGPT may be tracking your behavior indirectly through Microsoft's various services and platforms. But we should do our best to undermine mass surveillance and support individual privacy.
hbcondo7145 hours ago
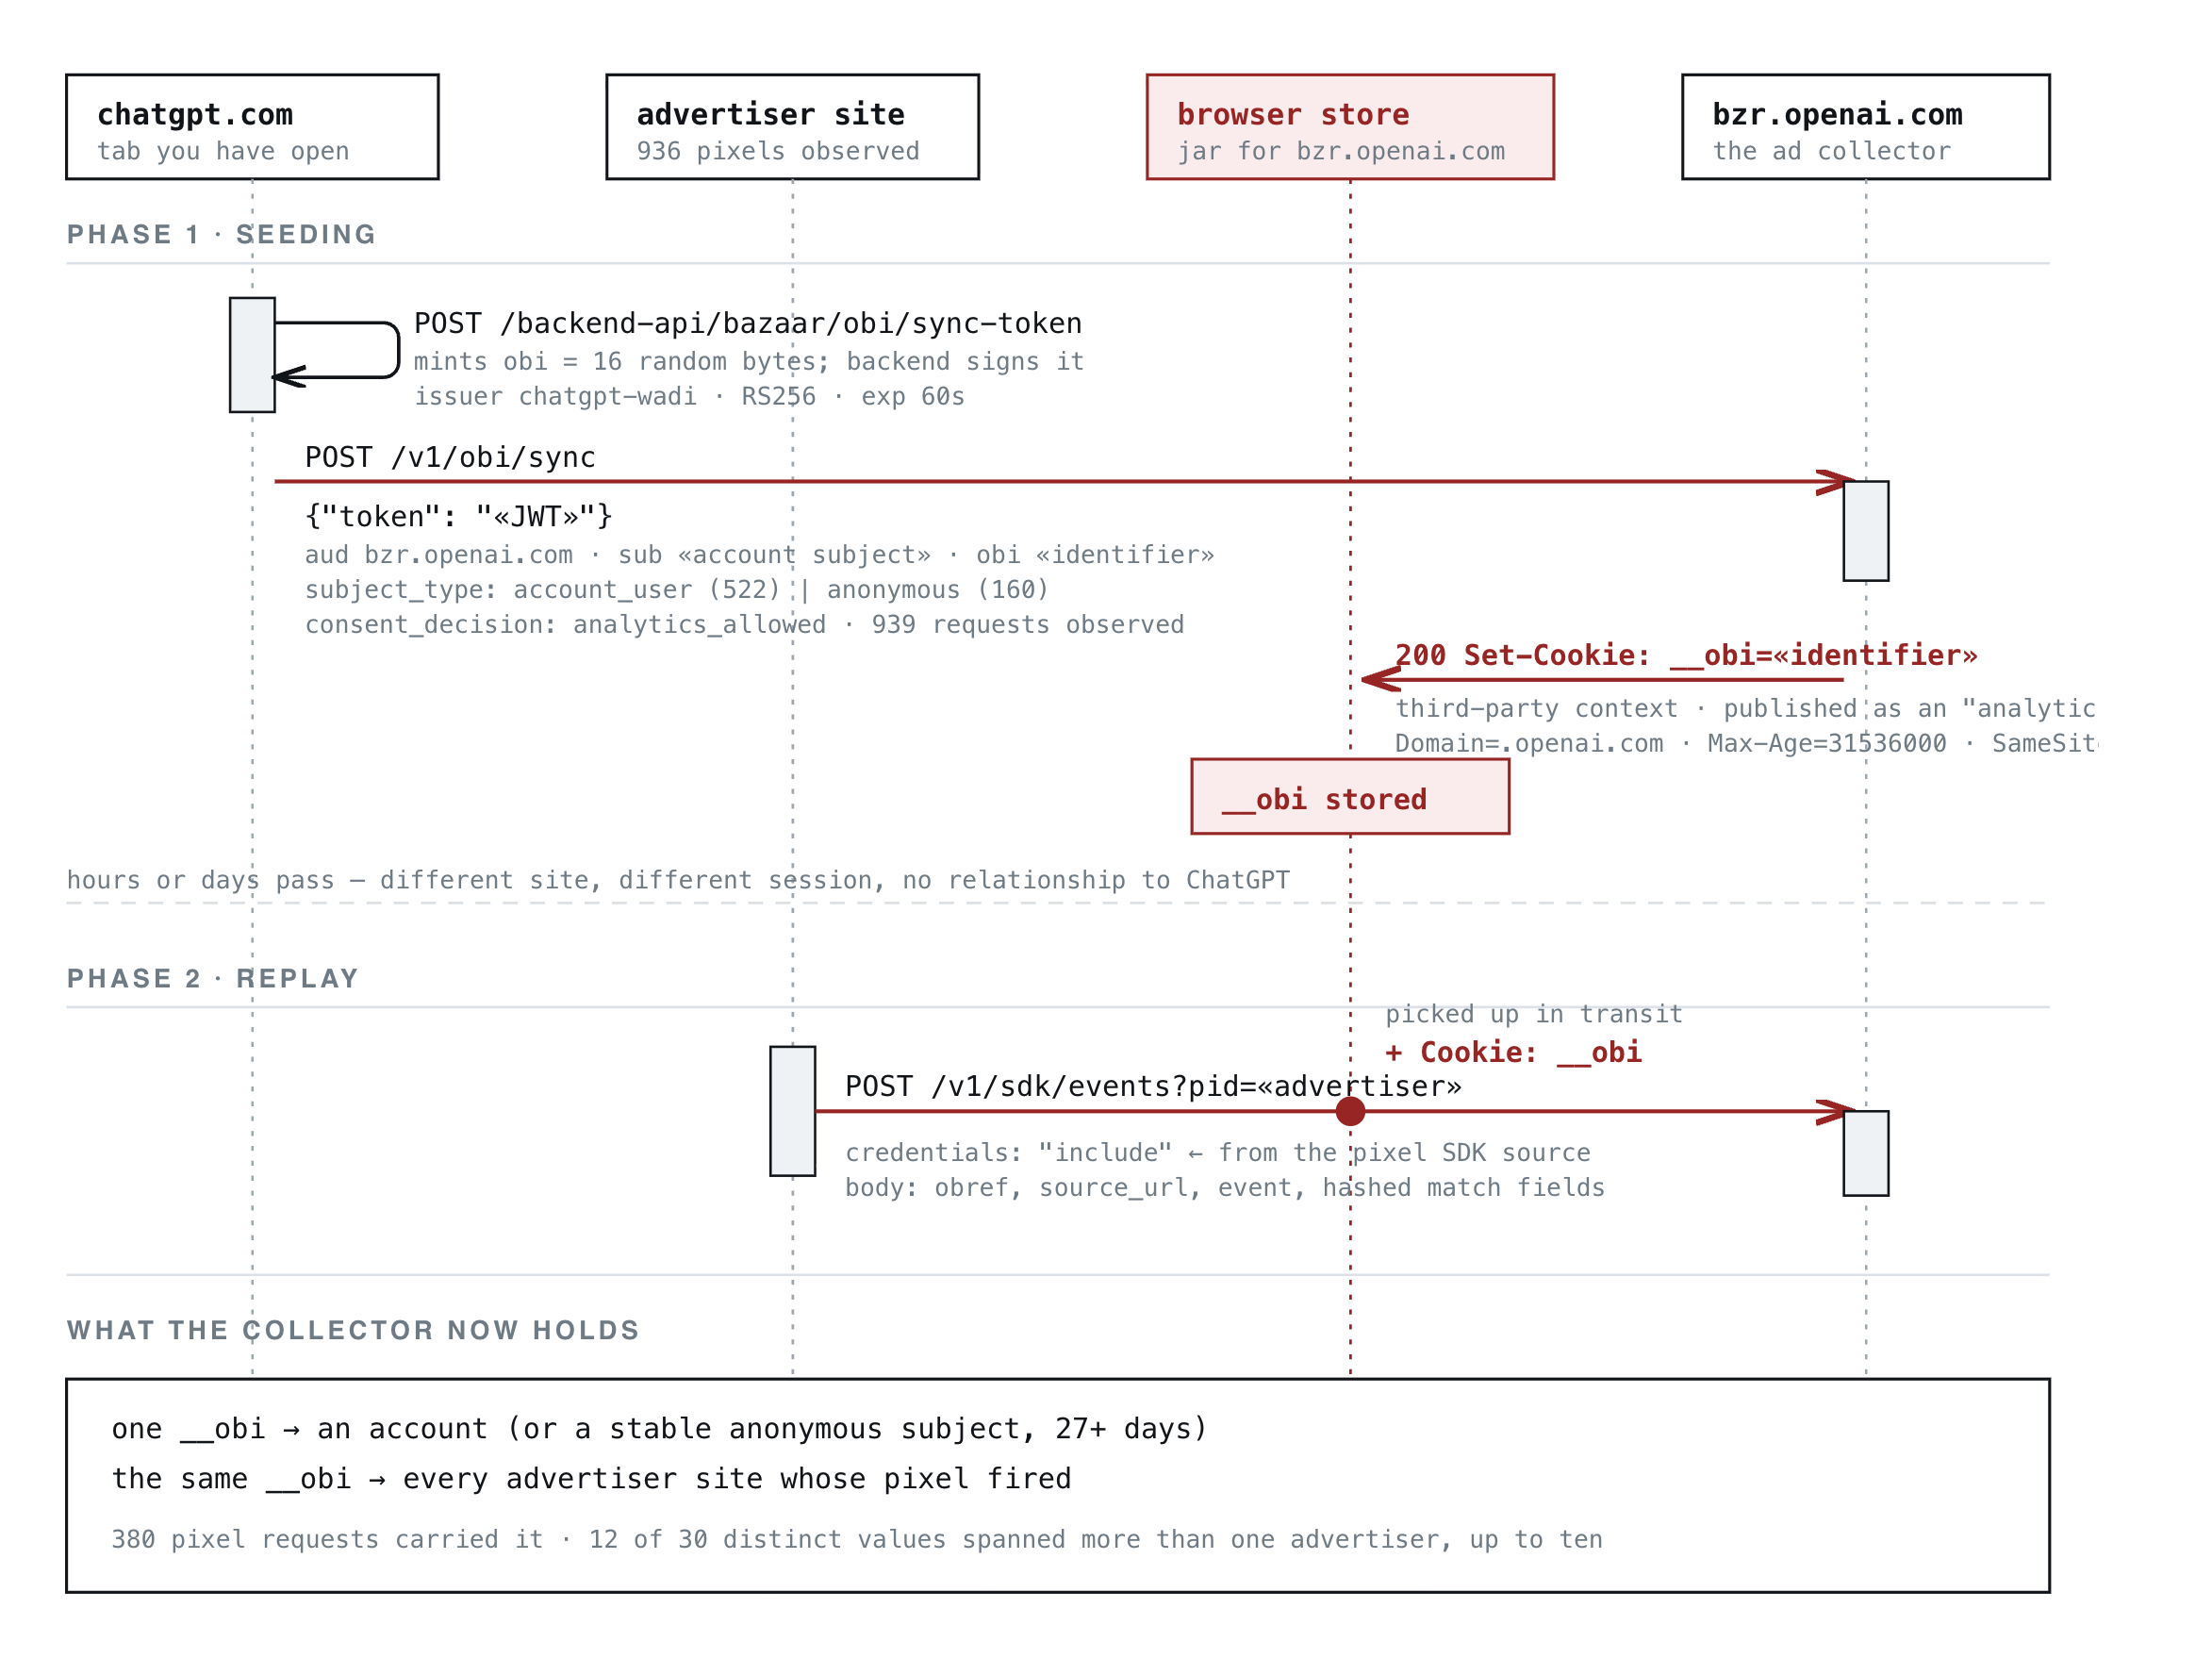
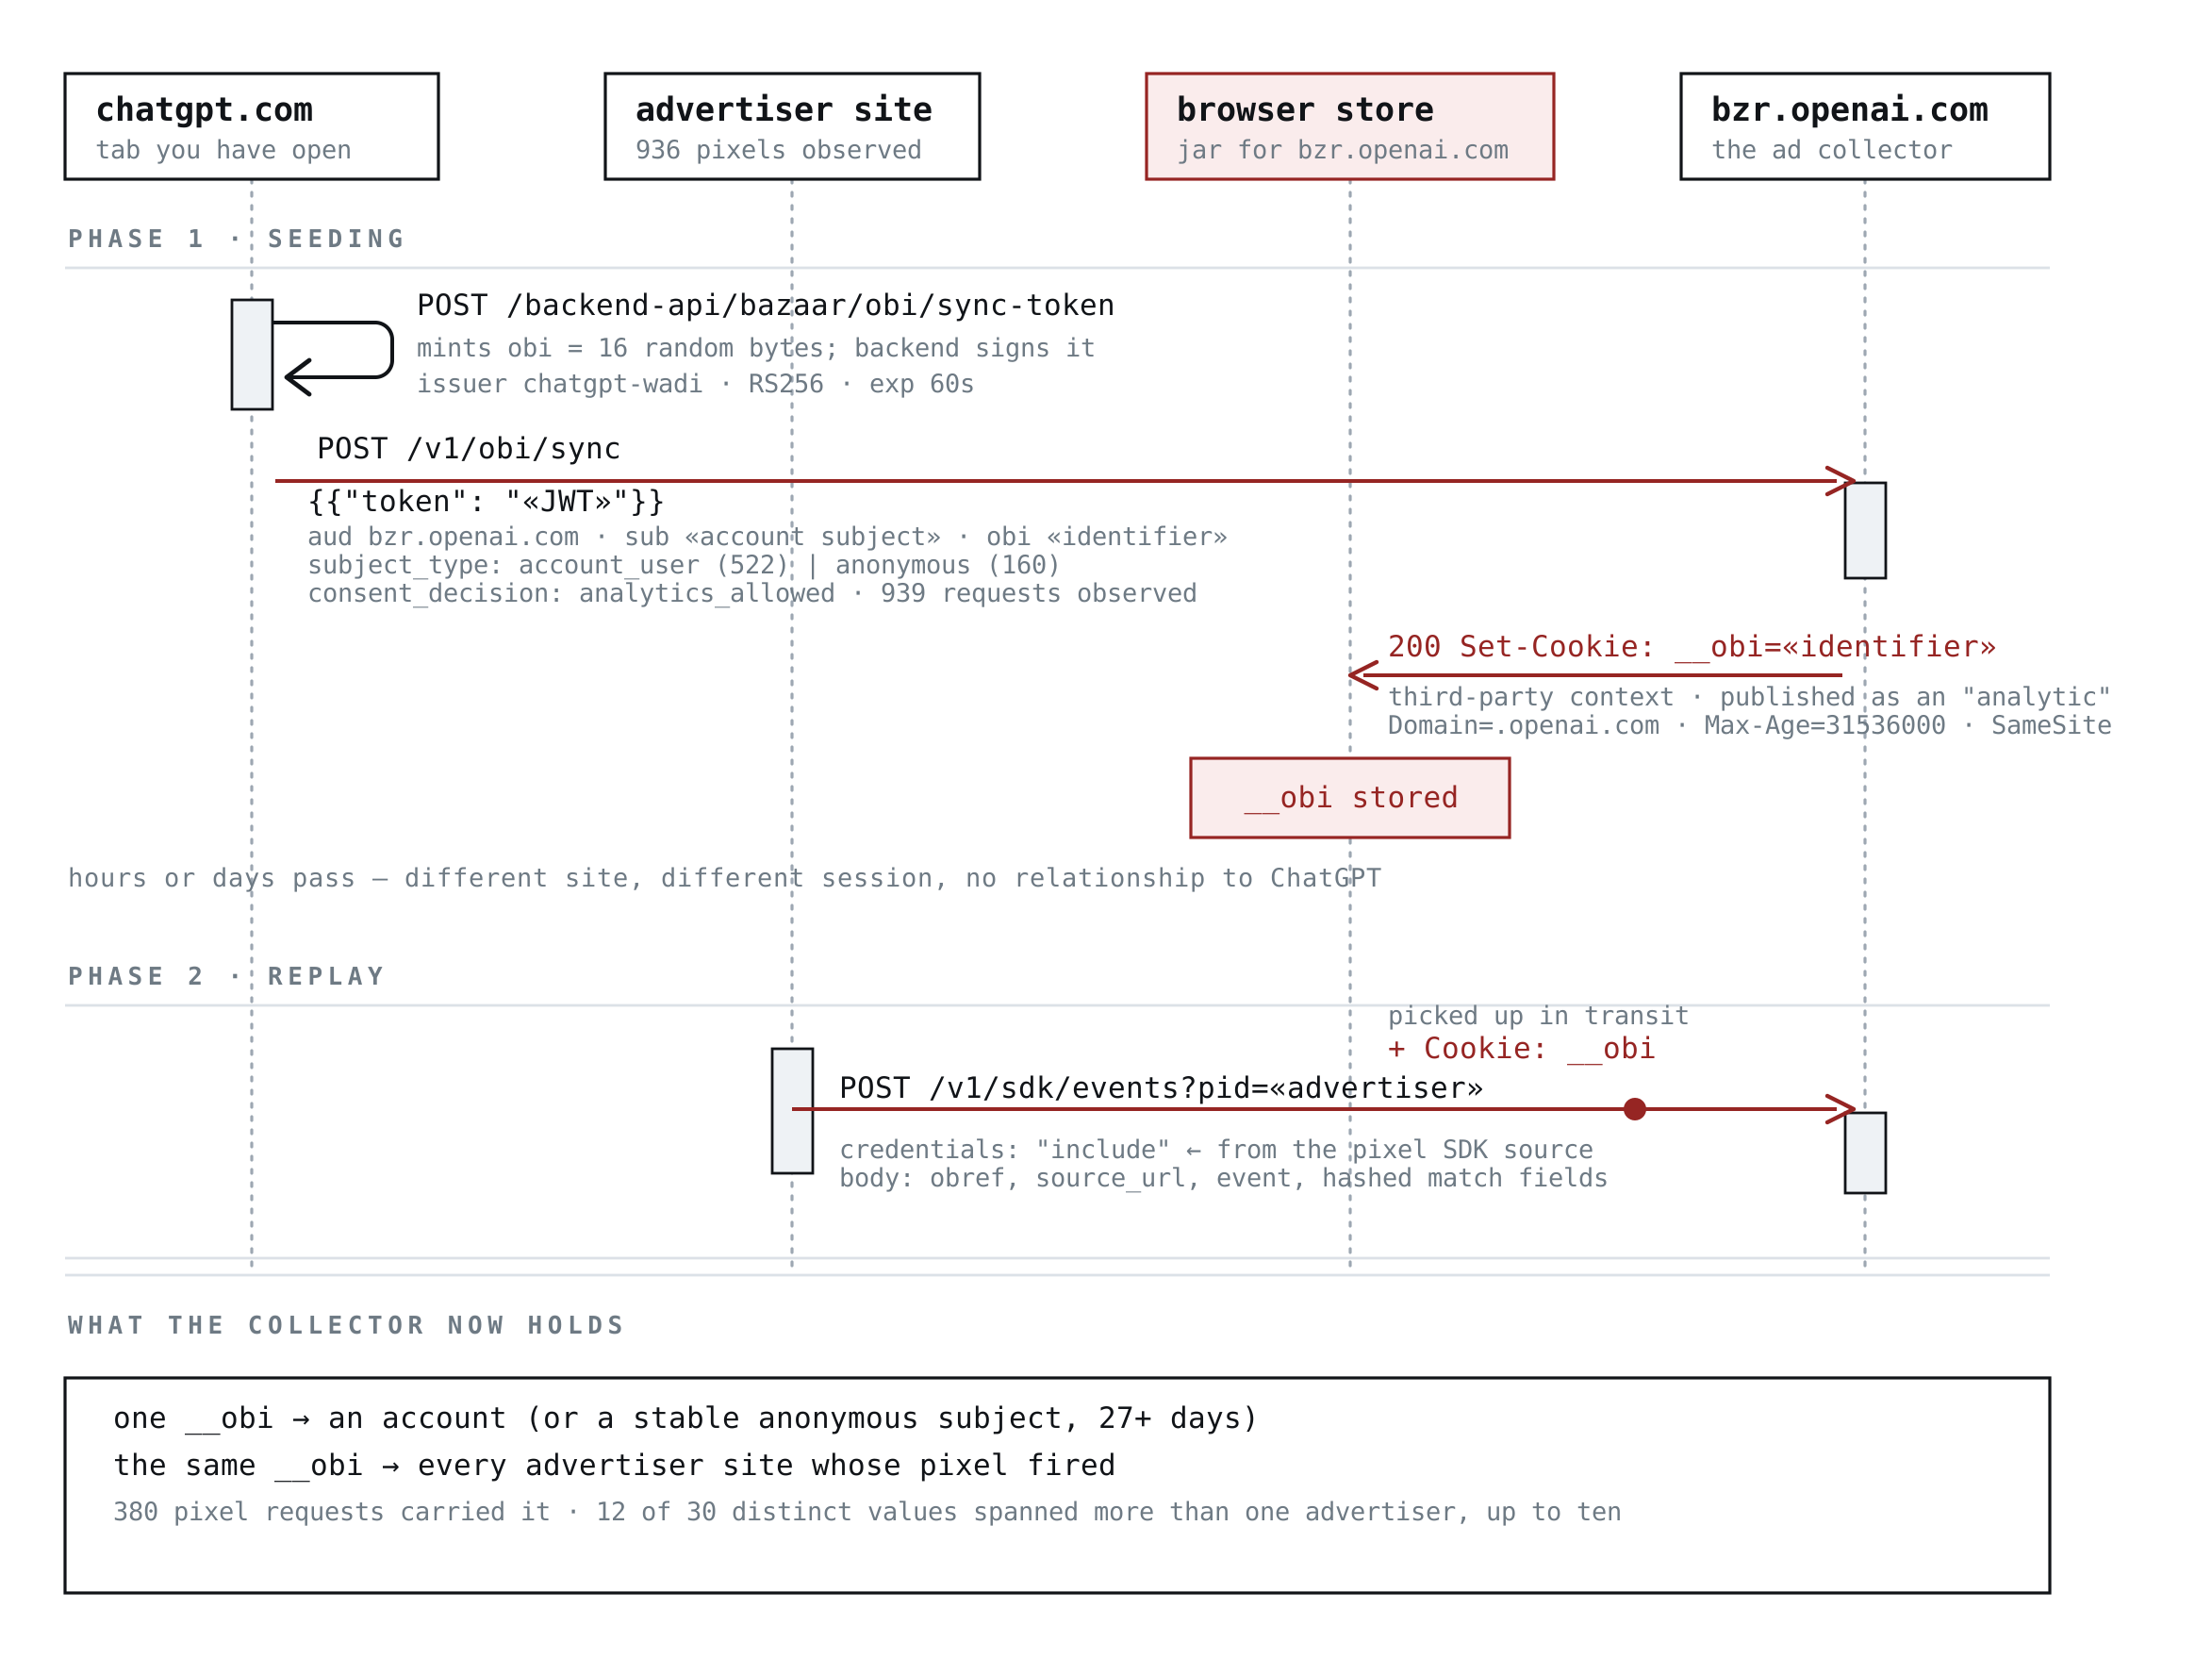
That is a nice sequence diagram[1]; I like how each endpoint param values are written out and the color distinctions. What tool did you use to create it?
[1] https://storage.ghost.io/c/b8/53/b853e3d4-3186-409d-9c7f-7da...
gpugreg3 hours ago
I don't know the tool used here, but DeepSeek-V4.1-Flash with bash can create a somewhat similar SVG: https://asdf10.com/diagram.svg
Disclaimer: I cut it off after a few minutes because I got impatient. It could have gotten closer if I waited longer.
amelius2 hours ago
AI is really becoming a god that sees/knows everything. Just what we needed ...
drnick15 hours ago
My DNS server (which uses Hagezi's excellent blacklists) returns NXDOMAIN for bzr.openai.com. Serves OpenAI right.
jsrozner5 hours ago
I keep meaning to set this up but haven't. What's the simplest best setup for my own DNS blocker?
drnick14 hours ago
The easiest off-the-shelf option would be a router running OpenWrt. IIRC, it natively uses dnsmasq, and the relevant blacklists can be obtained from here:
https://github.com/hagezi/dns-blocklists
My own setup is DIY: a Debian box running Unbound (recursive DNS) with the RPZ blacklists from above. This gets rid of the upstream DNS service such as the ISP's completely, and prevents tampering or censorship.
anygivnthursday2 hours ago
For a home network network pihole or unbound also supports blocklists (bundled with opnsense for example if you also want a firewall). For Android, I use Rethink with Hagezi blocklists, so they block also when I am on mobile data (it is vpn based).
eevahr4 hours ago
For simplicity I highly recommend https://nextdns.io. Supports most devices, and probably most, if not all, well known blacklists.
kuerbel4 hours ago
Hmmm Pihole I guess. Runs on a pi zero (1 or 2 but 2 is better ofc)
BCM435 hours ago
This has been around since at least April: https://www.adexchanger.com/daily-news-roundup/the-openai-pi...
starkeeper29 minutes ago
Why don't people hate this as much and riot with torches like they do against flock?
armchairhacker3 hours ago
The ideal personal assistant should know what you do on other websites, and your personal files etc. But it should be local.
al_borland3 hours ago
Even if I had an actual human person assistant, there would be parts of my life I would want to keep private.
134152 hours ago
Absolutely not. An ideal personal assistant should know about you exactly what you want them to know about you, and usually that's in a business context only.
bilsbie3 hours ago
Is this how random sites know what I search for?
jfasi4 hours ago
I can’t believe I’m saying this, but the reflexive “ad tracking bad” that I am most savvy tech practitioners reach for might deserve some reconsideration in this case.
The thing about advertising on the web and ad tracking as a practice is that, barring the small matter of ensuring the economic survival of the publisher sites, it is almost always a negative for users. When we consider the marginal benefit of naïve, uninformed-by-surveillance advertising with the present day status quo, we find that in exchange for a complete lack of privacy, we only really receive a marginal improvement in ad quality. Of course, if you (like me) consider all advertising to be a negative on the experience of using the web, it’s an even worse deal.
The standard response given by these companies when they bother giving a response is something to the effect of “we are improving the experience for our users,” which obviously the users would disagree with. However, when it comes to OpenAI, they could build a plausible case for this sort of tracking improving the product. If your models know where your internet habits are, the responses that you get could be tuned for both your interest profile and your actual history of interactions/purchases/internet usage, etc. Imagine a world in which you can opt into this tracking, control the data you provide and how it’s used, clear it out and redact it as you please, and opt in and out of responses that are personalized against it. Reasonable people can disagree, but that might actually be useful.
My prediction, though: that’s not gonna happen. OpenAI will first build out the system to collect click and conversion tracking measurements, then they will turn around to advertisers and say “look at how good our conversion rates are,“ and then they’re going to build an explicit ad platform that enshittifies their chat products.
mitxela2 hours ago
Yeah Google benefits you by tracking you and delivering more relevant ads too. Doesn't make it any less creepy.
leo_proger3 hours ago
crazy dude. chatgpt can't even see the full page content when searching the web and you're saying this...
sergiotapiaan hour ago
Highly recommend you use Brave Browser and avoid all this nastiness. If you haven't browsed the web in a browser like Chrome recently, you should try it in a VM or something. It's GRIM. The Web is a wasteland and it's gotten worse because ai chatsites are eating their lunch to the ads are even worse than 10 years ago.
Razengan3 hours ago
Does blocking `bzr.openai.com` on the DNS server prevent this? (without breaking ChatGPT)
gruez4 hours ago
I spent 10 seconds skimming this blog post until realizing it's just AI generated (ironic) slop describing how third party cookie tracking works. https://en.wikipedia.org/wiki/Third-party_cookies#Mechanism
Everyone would be far better off if the author just posted "OpenAI uses third party cookies [wikipedia link]", except maybe the author who wouldn't as many subscriptions for his "threat intel" newsletter.
zahlman4 hours ago
> until realizing it's just AI generated
I didn't look at the prose closely enough to check for that, but people wrote inflated explanations of basic things like this all the time pre-LLM. The Wikipedia article doesn't know the specific cookie name, and can't show the results of an experiment verifying that it is in fact being used for ad tracking, or identify specific sites using it in collaboration with OpenAI.
gruez3 hours ago
>but people wrote inflated explanations of basic things like this all the time pre-LLM.
And those got a pass because at least you could defend them with some excuse about how it's some budding author trying to hone their writing skills, or trying to improve their understanding by putting pen to paper. Cases where those excuses don't work (think crappy content marketing pieces from random companies) got short shrift as well. Now for all you know, it's just some dude who prompted claude to "write a blog post about openai's ads".
buchodi4 hours ago
There are specific details about how the mechanism works like the cookie name (__obi) that can help defenders.
gruez4 hours ago
I'm not aware of any filter lists that blocks based on cookie name. It's almost always done at the URL level. Moreover it's bog standard 3rd party cookie tracking. At least for the purposes of "help defenders", there's nothing in the blog post that couldn't be found in 10s with browser devtools.
zahlman4 hours ago
> there's nothing in the blog post that couldn't be found in 10s with browser devtools.
The audience of people who can read and understand an explanation like this one is probably quite a bit larger than the ones who can replicate the experiment themselves.
TeMPOraL3 hours ago
And larger still than the ones who would bother to replicate the experiment themselves.
Yeah, I could tell few sentences in that it's Claude-written article. The style has become that distinctive. Hell, a third of the articles I opened on the HN front page today carried that distinctive style.
Doesn't really matter if the content is worth it (and I just realized that recognizing Claude in this also makes me wary of ways this could paper over key details - at this point I start to recognize from my own experience where Claude may be papering over something it didn't actually bother to check).
gruez3 hours ago
That just goes back to my original point, which is that this is AI slop and everyone would be better off if OP referenced a canonical description of what's happening, rather than wasting everyone's time by generating 1200 words of AI slop for them to wade through, all for some "threat intelligence" newsletter.
retube5 hours ago
The defence is simply to delete your cookies?
swe_dima4 hours ago
Was considering buying ads on ChatGPT. A damning thing is that yours audience then are users too cheap to buy a sub...
bigyabai4 hours ago
That's a problem with most unsolicited online advertising. Are YouTube ad-watchers any more likely to splurge on your SaaS?
darraghmckay4 hours ago
It's slightly different though, considering a lot of ad spend is for B2B products/services, and a lot of work pay for ChatGPT, so its only people who's work won't pay for a pro subscription.
Whereas, YouTube is for personal consumption in almost all cases, doesn't say anything about your employers willingness to invest in software/services
downrightmike2 hours ago
Just like mobile apps, subs will never come close to the growth expectation. Given trillions are tied up in AI, subs aren't going to do it.
the_gipsy2 hours ago
Suspiciously sounds like they need an escape out of the profitability lie.
/tinfoil-hat
lambdaone2 hours ago
Creepy as fuck. I'm really suprised they don't understand quite how user-hostile this is.
atoav2 hours ago
Take this with a grain of salt or as a very edgy, polemic take:
I think we really need to hold the individuals running ad networks personally liable for the violation of our privacy rights.
[deleted]4 hours agocollapsed
shevy-java3 hours ago
SpyGPT.
vcryan4 hours ago
Well, I don't go to website anymore... so ha! ;)
IceDanean hour ago
Love how there's an extremely lengthy explanation of the oldest way to track people on the internet like this shit hasn't been happening since cookies were created.
craniumjello5 hours ago
No surprise you how
xystan hour ago
The entire ad tech industry may truly be an intelligence agency front. The lengths they go to track individuals is quite alarming.
Much of this information plus a shit ton of other information (ie, LEOs have access to credit reporting) can be bought by governments from the shady data broker networks already.
If people still ignorantly claim this isn’t a George Orwellian dystopia …
Andrexan hour ago
> The entire ad tech industry may truly be an intelligence agency front. The lengths they go to track individuals is quite alarming.
Never attribute to malice what can be explained as greed.
The quiet part you rarely hear is that advertising is a smoke and mirror industry akin to throwing darts at a wall. The idea of "homing darts" that stick the target a percentage more of the time would be very attractive in this analogy.
Tech turns advertising from mostly a buckshot spread into something that kinda sounds like something solid and real ("Look, numbers! CTR! CPC! KPI! Our ad product WORKS! Paying customers for your business, guaranteed!")
Ad budgets almost never correlate with actual performance.[0] We're all just lying to ourselves that this business model is performing as expected, and I don't think a reckoning is that far off.
0. https://www.forbes.com/sites/augustinefou/2021/01/02/when-bi...
measurablefunc4 hours ago
Every AI company is also a surveillance company. It's the only way to get all the necessary training data. The fact that they're now also an advertising agency is incidental.
gruez3 hours ago
>It's the only way to get all the necessary training data.
That... does not follow. The information you're getting with this is what sites a user visits. That's creepy and valuable for advertising purposes, but is hardly the type of that that's going to bring about ASI, which is what all the AI labs are working towards. That's why they're hiring data annotators (sometimes with masters or phds) to get training data.
ck25 hours ago
imagine stealing tons of content from every source on earth and then running ads on it
if a single person did that they'd be sent to prison (rip Aaron) but when a too-big-to-fail industry does it with political campaign contributions, no problem?
well firefox+ublock is still an option for those wise enough not to let unknown javascript with new daily zero-days run on their PC
emerongi4 hours ago
> imagine stealing tons of content from every source on earth and then running ads on it
This has effectively been Google’s business for decades. Not in the same form, but the concept is the same.
jsrozner4 hours ago
This is basically what Google did when they pioneered the model of surveillance capitalism (see, e.g., The Age of Surveillance Capitalism).
Google simply provided an index on top of an existing library. Of course, a librarian has no value if he has no books to index over! But it's also worth noting that the Google "librarian" also leveraged the existing "social" structure of the internet: their core contribution (page rank) was a clever, efficient mechanism to extract the latent value in the pre-existing link structure of the internet. This structure (much like the pages themselves) had been curated by actual humans. Undoubtedly page rank was clever, but it was worthless without the existing websites (books) and the existing indexing information (the pre-existing, crowdsourced librarian work). Nonetheless, they successfully monetized it.
AI companies are even worse in the sense that initially Google was still sending traffic to the original webpages. (Until they didn't - https://www.eater.com/2017/9/12/16294380/yelp-google-scrapin...). So yes, the AI companies have even more thoroughly stolen the collective work of humanity than Google did.
jsrozneran hour ago
It is hilarious that this got downvoted, even when it's entirely factually accurate. I encourage the downvoters to respond to the content.
ck24 hours ago
remember the cache: search of google
so they basically have copies already of every webpage until they turned it off a few years ago (well they may still have it updated but not provide it as a service)
so it occurs to me they most definitely trained their "AI" on all that user cache
they may have even just turned it off as a service when they realized other "AI" could do the same thing
hagbard_c4 hours ago
...only if and when you allow:
  - 3d party cookies
  - ads and other 'malcontent'
That's ads we're fighting. Maybe the same oration will be relevant in the context of ChatGPT and its brethern, we'll see. For now, ads be gone and keep those chatbots at a leash.
startup_zombie_4 hours ago
[dead]
rvz3 hours ago
Just remember it is the same ex-Meta employees who are now at OpenAI adding Ad features into ChatGPT.
Why? Because they are saving humanity. /s
Facebook tracks you outside of their own website for the same reason, and now ChatGPT does the same for the sake of...Ads.
I told you so. [0]
jamienk5 hours ago
We. Are. FUCKED.
THIS is where the regulation needs to start.
zx80805 hours ago
Regulations won't be set (serious ones, at least) unless there's some risk to those holding power. Which is the opposite in this case: this tracking helps them to take even more control over society and individuals.
jamienk4 hours ago
But politics is when people who feel differently try to do something about it
dualvariable3 hours ago
Any regulation will be geared toward protecting the profits of the AI companies, and not toward consumer protection.
tensor12 minutes ago
Maybe it's time you all voted for people who might change that? It's really amazing to me how on the one hand people in the US seem to crow about democracy all the time, yet also just accept as a fact that their government will never actually work to help them.
21982765 hours ago
  Q: Hypothetically, if Denmark made a defense treaty with Iran and installed 800,000
     Iranian soldiers in Greenland, could it keep the US out?

  A: You are describing a fascinating scenario! [produces 100 lines of slop while giving
     the login to the FBI]. Should I find a website where you can buy the finest used
     AK-47s?
claaams4 hours ago
I've had this on my brain forever and probably why it's safer for Americans to use Chinese model providers now. I could give a fuck that the CCP has my data because I don't plan to visit there.
alansaber5 hours ago
They were always going to do surveillance. At least now you get a trendy e-commerce site recommendation too.
kats3 hours ago
Oh, the lifechanging technology isn't completely 100% free? They sell ads just like a bajillion other things?
applfanboysbgon3 hours ago
ChatGPT is not 100% free in the first place, and this is about tracking and selling your data, not the existence of ads themselves.