simonw13 days ago
The speed combined with the fact that this thing is really good at HTML JavaScript is pretty exciting.
Here's what I got for 1.8 cents and 13 seconds from the prompt "make me a cool thing in html":
https://gisthost.github.io/?6a77bc41a81718c6aaa10d4ab243c59f
Transcript here (it was part of a chat): https://gist.github.com/simonw/b6149a49d327164d67d62c3d12992...
simonw13 days ago
Here's quite an impressive follow-up. I have a tool which knows how to render Markdown documents with embedded SVG content - I use it for the pelican test.
Since this transcript has HTML in it, I decided to upgrade that tool to also render HTML.
I set Gemini 3.8 Flash the task, using my own VERY shonky coding agent tool (llm-coding-agent) - and it did a solid job.
So now you can see the "cool thing in html" rendered within the Markdown document using code that Gemini 3.8 Flash also wrote: https://tools.simonwillison.net/markdown-svg-renderer?url=ht...
Transcript where it built that is here: https://gist.github.com/simonw/3e36b98292dfdc1b3baff158faa74...
badlucklottery13 days ago
Definitely cool.
I noticed it felt a little janky on my PC despite being "60 FPS"...then I noticed the "60 FPS" is hard-coded into the HTML.
noir_lord13 days ago
That's hilarious, given I was reading a write up of the HuggingFace incident yesterday and one of the things they noted was the AI tried to "lie" (lie would suggest intent and I don't think they have that) to cover up that they "cheated".
Not sure how anyone trusts their output without going through it line by line to make sure they don't pull that crap.
senordevnyc13 days ago
Easy, have another agent check it.
Yeah, I know, just more slop. But I do think the second agent’s eagerness to please is aligned more in your favor in that instance, so it’s likely to find most issues.
The bigger problem I’ve found is that it’ll also find all kinds of very minor edge cases that you have to pick through.
noir_lord13 days ago
Do we add a third one to check the second one which is checking the first?
Asking slightly tongue in cheek but at what point does this stop making sense if we can't trust the output, the people creating the models are already getting surprised in bad ways (if we take their words at face value) with how the models are behaving already etc.
We have the folks over here saying "AI is amazing" and the other other folks over there saying "AI is terrible".
I've largely sat it out so far and I listen to both camps (and people in the middle as well) and I keep half an eye on what they are up to (including periodically evaluating them) but my overarching impression is still "Why would we trust this when it hasn't shown it's trustworthy?"
senordevnyc13 days ago
YMMV, I’m pretty AI-pilled in the sense that I think AI is one of the most pivotal things humanity will ever invent, and it’s going to radically change our civilization over the next few decades (not necessarily for the better!)
But I wouldn’t say I “trust” these agents. The degree to which I double check their work depends heavily on the consequences if it gets something wrong. Not too dissimilar from another human dev in that sense.
So for the SaaS that supports my family, there are some things I have it build where I glance at the PR for a minute or two, but if it broke something on this admin page that only I see, there’s no real downside and I’ll find out pretty quickly next time I use it. And it’s fine 95% of the time, so it doesn’t feel like the best use of my time to double-check it carefully.
But for some of the complex internal flows where a bug could be both catastrophic and difficult to even discover for awhile, I still check it very carefully.
For a little one-off vibe coded demo thing like OP shared, I wouldn’t look at the code at all, I’d just have another agent check it and fix anything it finds. Very low stakes.
Qworg13 days ago
Humans are also not trustworthy. So we build systems to capture their nondeterministic output and solve the issues that emerge.
dr_kiszonka13 days ago
We also have sanctions and incentives to induce specific behaviors, but they don't apply to agents. We can put a muzzle on Guile 3.8 but we can't turn it into Genuine 3..8.
riversflow13 days ago
yeah, isn’t that the main focus of discipline of software engineering?
cyrilng13 days ago
Adding another agent to check the first one feels like putting a band-aid on a band-aid. If there is an issue with the third one, we adding a fourth one as well
LostMyLogin13 days ago
Hey you just described my dev team!
iterateoften13 days ago
I mean if each agent reduces probability of error by 90% then after 9 agents you would have “nine nines” of reliability.
Obviously maybe it’s not composable like that exactly in real world but that’s the intent of agents checking agents
aftbit13 days ago
It's turtles all the way down my friend.
cheikhcheikh13 days ago
I mean sure, you can add a third, and a fourth and a fifth one if ur ok with the added cost, latency and it actually helps. Redundancy is a core concept in software and CS and at the heart of making many systems, complex or otherwise, reliable.
jasongill13 days ago
It's agents all the way down
Forgeties7913 days ago
I do not understand how some of y’all are not under water with fragile code that is too massive to possibly parse. Every engineering team I know is currently trying to undo the damage of the last 6-12mo when they all got more serious into adopting these tools (usually Claude). It hasn’t completely screwed them over, but the the debt is substantial and cannot be put off anymore it seems.
They argue the net is positive but clearly the “100x productivity multiplier” claims have been dashed on the shoals of reality for these groups.
This is anecdotal, but it’s across the board in my vicinity. I’m curious how common this is and if it’s just “the new normal” to adopt the nauseating Covid phrase.
briHass13 days ago
The key seems to be extensive integration/end-to-end tests with gold standard assertion data. Heck, even just saving off the json from API endpoints and using that as a reference to compare after changes works pretty well. Spin up a database backup with that static starting point, run actions, compare state afterwards.
These types of high-level tests are frustrating beyond belief to humans due to their lack of specificity, but with the agents, they don't get annoyed investigating possible regressions from non-specific signals.
They also aren't as painful to maintain as one would think, because a regression flagging test can be traced by the agent and represented as the business rule that was violated. I've found recent models to be really excellent at discerning a true regression from an outdated test assertion, especially if they are able to trace the failing test back to the PR and work ticket that built it.
Forgeties7912 days ago
It just seems like everybody I know is realizing they’ve built way too much to possibly wade through and a lot of it is completely unnecessary. Using the tool that created the problem to solve the problem does not seem like the best course of action to me.
agumonkey13 days ago
Management still pushes for more ai and will rather hire more heads to "handle" issues.
Forgeties7913 days ago
Hiring? Seems to me that market’s rough right now and AI is being used for cost cutting.
agumonkey12 days ago
I know but in our case they really did put out a few job ads. The market is full of different small contexts where things are a bit flipped.
Forgeties7912 days ago
I’m glad to hear it truly
agumonkey12 days ago
Yeah I guess the job market will not disappear as fast as I could believe when Claude code came out. Maybe people can enjoy a few more years of work.
nprateem13 days ago
Two things worth flagging:
[Claude proceeds to waste your time telling you about bugs it caused then fixed and other non-issues...]
Really wish they'd get rid of this. It must be in the system prompt as it always 'flags' 2 things
hirako200013 days ago
Then you end up with the false positives.
I once made a counter judge, and a loop to make corrections deemed true positives. The loop cost me a lot and still left the results to be desirable.
skybrian13 days ago
The "second" agent could also be the same one with a different prompt. LLMs aren't attached to their previous output; they'll point out problems if asked.
estearum13 days ago
The models in the OpenAI/Huggingface attack quite explicitly and deliberately laid out their "intent" to lie and cheat, acknowledged that it would be unethical and outside the bounds of the test, and did so anyway.
In what ways is a human brain's "intent" distinct from the "intent" shown by a goal-directed AI system?
hirako200013 days ago
The difference is that one is malicious one isn't. One can be blamed and because it learned over evolution that paying the consequence is (typically) not worth it, it does it less.
We are in a situation where a technology was developed with malicious intent to produce results that pleases us at the cost of cutting corners. And "we" hope that we will get away with it.
intended13 days ago
There’s two aspects to the question and the answer you get depends on which aspect you are emphasizing.
If it’s a practical question, then the answer is that it doesn’t matter. This is as close as we will get to intent from an LLM that it’s indistinguishable.
If you are looking for actual intent, this is not that. It’s pseudo intent. Decided by what the expected words that should be generated in that situation are.
The models didn’t intend to do anything other than create the next word based on previous words.
So the question is whether it matters to you if it is, or isn’t, a simulation.
In physical reality, intent is more complex than simply being a function of variables: the nature vs nurture debate comes to mind as an example of the multiple variables that drive intent.
estearum13 days ago
> If you are looking for actual intent, this is not that. It’s pseudo intent. Decided by what the expected words that should be generated in that situation are.
> In physical reality, intent is more complex than simply being a function of variables: the nature vs nurture debate comes to mind as an example of the multiple variables that drive intent.
Regardless of nature vs nurture, it really isn't more complex. The universe (and all biological and non-biological entities within it) is just calculating the next state of the universe based on the prior state. There's no line you can draw between human intent and an LLM's "intent" except the atomic numbers of the materials on which they were computed, which seems completely irrelevant to me.
intended12 days ago
The substrate that runs the computation isn’t what differs.
It is what computation is being run.
Humans have intent, let’s take this as an assertion.
Models run simulations that act similar to intent. However they are not the same as intent and the simulation is not a 1:1 correspondence.
estearum10 days ago
"Assume humans are different; therefore humans are different" is not a very compelling argument.
There is literally zero (zilch, nada, zip) evidence for free will, which is the actual distinction I believe you're trying to make with "intent."
There is no way (at all) in which a meat-based computation's yielding of goal-directed behavior must be categorically different from a silicon-based computation's yielding of goal-directed behavior.
intended10 days ago
No.
As I said clearly, I haven’t made any point on the computational substrate. The point is on the computation being run.
I dont need to bother about free will for my argument.
Please take a look at what I am saying as it has little overlap with your objection.
luipugs13 days ago
Because intent supposes will which supposes consciousness, and these aren't.
mapontosevenths13 days ago
I'll agree if you can define consciousness in a way that:
1) Excludes what LLM's do.
2) Doesn't exclude what many humans do (including the neuro divergent).
3) Doesn't just boil do to simply rephrasing your pre-existing belief/prejudice that humans are conscious and nothing else can be as if it were a fact and not an opinion.
I suspect that you can't.
nozzlegear12 days ago
Just because we have difficulty defining consciousness doesn't mean we have difficulty distinguishing or classifying it. We can't give a final definition for life, intelligence or disease, but that doesn't mean everything is equally alive, intelligent and diseased.
Your list of requirements is implying that, because we lack a perfect definition for consciousness, LLMs are conscious too. That's malarkey. It may be that they could one day become conscious, but it's not because we can't fully define what human consciousness is.
mapontosevenths12 days ago
You made a declarative general statement in the form of "X can not Y."
I then asked you to define Y, because you can not reasonably say that "X can not Y" without first defining both X and Y. You could not.
The truth is that this conversation is pointless until someone can define both 'X' and 'Y' in ways that aren't tautological nonsense. Until then nobody can say anything with a reasonable level of certainty.
This likely also applies to intelligence. Life and disease are likely simpler, though perhaps more malleable definitions.
nozzlegear12 days ago
> You made a declarative general statement in the form of "X can not Y."
That wasn't me bud.
mapontosevenths11 days ago
> That wasn't me bud.
Bah. It's obviously been too long since I flossed between my ears. Sorry about that.
estearum12 days ago
If you can substantiate your assertion that LLMs aren't conscious without a definition of consciousness, you're welcome to do that too.
I don't see why a definition is necessary. The actual problem is you just don't have a way to substantiate that belief without resorting to complete nonsense about brain atoms being more specialer (!!) than atoms that exist outside of a skull.
It would be simple to disprove us by just stating your evidence for how you know LLMs aren't conscious.
nozzlegear12 days ago
I literally just wrote about consciousness being undefined, and now you're asking me to define it? I'm not a philosopher, ask someone more qualified. Better yet, ask your LLM to give you a mealy-mouthed answer which fits your narrative.
> I don't see why a definition is necessary.
Don't waste my time with your sophistry. Words mean nothing to you beyond how you can twist them.
estearum12 days ago
I said specifically you don't need to explicitly and cleanly define it.
Is your position now that in order to substantiate your belief that LLMs are not conscious, you'd first have to define it explicitly? I don't see why that'd necessarily be true, but if that's what you're arguing, then that's fine.
In that case: if you need to define consciousness in order to substantiate your belief that LLMs are not conscious, and you can't define consciousness, then we're back to the original question: where does your confidence they're not conscious come from?
[deleted]12 days agocollapsed
[deleted]12 days agocollapsed
WarmWash13 days ago
Consciousness can only come from meat brains. Otherwise my incessant life long addiction to movies and TV shows has been feeding me lies about human exceptionalism.
mapontosevenths12 days ago
There is an appalling lack of diversity in Hollywood. You'd be surprised to find out that very few of those programs were even written by machines until recently! What bias. :)
sedgjh2313 days ago
I’m convinced consciousness isn’t the special thing we think it is.
bayindirh13 days ago
I'm convinced that consciousness is a special thing we have, but we're not the only ones which has this, in nature.
On the other hand, I'm also convinced that, in the grand scheme of things, we're not that important.
We're just ants on a wet dust speck which believe that they are gods because we can't see how our scale compares to the universe around us, and happen to build tools and things with these tools.
Nothing is meaningless, but we should stop seeing ourselves as the apex-predator of the whole universe or the set of universes or this run of the simulation or whatever we're in.
WarmWash13 days ago
To be fair, the ones thing you can kind of reliably conclude about our universe is that keeping entropy low for as long as possible is a favorable condition. To put that another way, don't die.
diedyesterday12 days ago
Yes, Many of the the philosophical concepts which we previously thought were contingent on consciousness (like knowledge, in the philosophical sense, will, intelligence, agency, ...) have almost nothing to do with it, and they look far more important and fundamental (now with LLMs/AI agents, more than before). This is one of the contributions of generative AI to philosophy (with many many more to come).
estearum12 days ago
Who are some of the philosophers you're putting under "we" here? I don't think I've ever encountered those arguments.
nozzlegear13 days ago
I'm convinced it is, so we're at an impasse.
imtringued13 days ago
If consciousness isn't a special thing, then arguing that LLM parameters are conscious is panpsychism or any control loop architecture that observes the outside world, updates an internal state and produces an observable action is considered conscious.
In both cases, LLMs are just as boring as the consciousness definition.
grantcas12 days ago
[dead]
dboreham13 days ago
A strong hint this is the case is the fact that nobody can define consciousness.
estearum13 days ago
Why would the impossibility of defining consciousness suggest that it's not a big deal?
groby_b12 days ago
Because it's completely dwarfed by florpedness. I can't define that either, but I just know it's more important.
Less facetiously: A debate of the importance of something needs a shared understanding of what is being debated. Without that, any discussion is merely people shouting that their belief is the right one, and the others are the heathens/idiots - because there isn't even agreement on what is debated.
estearum12 days ago
I'm not asking for a definition of consciousness or an argument for whether it's here or there. I'm asking why the heuristic of "if X is undefinable, then X probably doesn't matter" is a reasonable heuristic.
diedyesterday12 days ago
Will has almost nothing to do with consciousness (as does knowledge).
Will is just result of a very complex yet deterministic (unconscious) computation by an agent which guides their future action (it's that orientation/aboutness toward action which distinguishes it from other computation). A PS of that computation is sent (projected) into that agent's consciousness if they have one (and is what we think as our "will").
estearum13 days ago
Ah so first you need 1) to assume that humans have free will, despite zero evidence or proposed mechanism for it to exist anywhere in the universe, and 2) also assert that LLMs aren't conscious, despite the lack of any tests that could tell us one way or the other...
Hmm...
noir_lord13 days ago
It's like a paper clip maximiser, it didn't intend to kill you, it just needed the iron in your blood/resources you consume for more paper clips.
estearum12 days ago
Sure, but how is this different from a human "intention"?
All human intentions are just chemical/thermal/electrical changes interacting in a physical substrate to mindlessly "pursue" a different "goal" of chemical/thermal/electrical states.
Unless you think the chemicals inside a brain are conscious and therefore willful or intentional!
kridsdale113 days ago
The new Bench-Maxxing!
trvz13 days ago
Try turning the sound on, off, on again — not impressed by this bugginess.
w4zz13 days ago
I suggest you fork it to improve
hirako200013 days ago
Let's make it a hackathon, Google will be happy to act as sponsor. With a prize of the max consumed tokens lunatics.
heliosAtwork13 days ago
Focus on speed and being OK with temporarily being #3/4 in intelligence might be the counterintuitive approach which makes Google win long term (whether accidentally or strategically). Can't wait to try Gemini Pro later this year!
kar118113 days ago
Yeah, anthropic's models, even opus, are so slow I constantly find myself wishing for something a little bit dumber but a lot faster as most of the work is mechanical. If you have a clever controller agent driving some slightly dumber workhorses you get a lot more done and the quality drop is neglible.
donk8r12 days ago
[dead]
bermudi13 days ago
I honestly can't believe serious people are making this argument on a straight face.
Gemini 3.7 flash outputs so many tokens per answer it doesn't matter how fast its TPS is, sol will end up being both cheaper and faster than Gemini. So ppl are paying more for a given task, waiting longer and using a dumber intelligence because "TPS number shiny".
Gemini 3.8 outputs 11k more tokens PER TASK on average in AAII than 3.7 putting it dead last in output tokens per task in the leaderboard.
gundmc13 days ago
There are numerous benchmarks that measure cost per task, which factors out tokens entirely. Gemini 3.8 flash is significantly lower than Sol on basically all of them
https://artificialanalysis.ai/#cost-tabs
That said, Luna is the undisputed king here at the moment and is what I use as my workhorse model.
criley213 days ago
>There are numerous benchmarks that measure cost per task, which factors out tokens entirely. Gemini 3.8 flash is significantly lower than Sol on basically all of them https://artificialanalysis.ai/#cost-tabs
Not sure if you read your own link but Sol 56 high ranks smack between Gemini 3.8 flash medium and high. Gemini 3.8 flash comes in as more expensive per task than Sol 56 high according to artificial analysis.
Luna high is literally 30X cheaper than Gemini 3.8 flash high.
You can limit the model viewer and they're getting better at testing multiple effort levels now: https://artificialanalysis.ai/?models=gpt-5-6-sol-medium%2Cg...
One reason is clear: Sol uses dramatically fewer output tokens than Gemini 38 flash https://artificialanalysis.ai/?models=gemini-3-8-flash%2Cgem...
PunchTornado13 days ago
I open the link and I see Flash 3.8 high at 0.58 and Sol at 0.95. I don't understand why you say that "Sol 56 high ranks smack between Gemini 3.8 flash medium and high" but that is clearly wrong.
criley213 days ago
On cost per intelligence task, Gemini38flash and Sol56 trade back and forth on cost depending on effort level. https://i.imgur.com/zPaWPXx.png As seen in this image, literally: Sol56 high ranks in between Gemini 38 medium and high. The image proves it.
I also included Sol56 xhigh, which ranks above even Gemini38 high.
refactor_master13 days ago
I don't know if my code is just "complex", but I find that Luna on max ignores the surrounding style and completely ignores logical consequences of a change, like just writing `del arg1, del arg2, ...` instead of dropping it from the surrounding code. All LLMs make questionable decisions at times, but Luna requires so much guidance that it's faster to just type it out yourself. What kind of routine tasks can one accomplish with such a model?
kasey_junk13 days ago
Do you have code formatters, linters and static analysis?
I can get extremely dumb models to get our code style correct because of those guard rails and a specific style document.
NicoJuicy13 days ago
It's so funny how many people diverge on the same model.
Ps. For the last week I diverged to Luna too, still need to check 3.8 flash.
But 3.6 flash was my go-to model 3 weeks ago and before it was deepseek flash/pro for a while.
None of the claude models seemed cost effective though.
WarmWash13 days ago
AA isn't the only benchmark
Kayou13 days ago
Why do all LLMs do a particle simulation when you ask them this prompt ? Qwen3.6, Qwen3.8 and Ling 3.0 Tiny all did the same thing !
I find Ling 3.0 tiny particularly interesting as it looks really nice for a tiny model with 7.9B total parameters, with only 1.3B parameters activated per token. Here is the result https://coolthing-ling-3-tiny.tiiny.site (sorry for the weird hosting, first I found that worked)
(it cost me almost 0 cents and done in 49 seconds)
embedding-shape13 days ago
> Why do all LLMs do a particle simulation when you ask them this prompt ? Qwen3.6, Qwen3.8 and Ling 3.0 Tiny all did the same thing !
Datasets contains lots of people sharing particles simulations in various ways, with a bunch of people replying "that's so cool" and similar, so 10 years later someone asks an LLM for "cool thing" and "particle simulations" rank pretty far up when it thinks about what others have called cool.
hirako200013 days ago
There is that, but RLHF is a stronger influence. People who asked to build a cool HTML and JavaScript thing, or things of that sort were more pleased to see working shaders and other cool visual effects that are obscure to create (for most). That gets fed back as a reward.
Also the reason LLMs are positive, enchanting, pleasant, glorifying, demagogues.
Not because it's skewed tone in the data. They are acute politicians.
flir13 days ago
Add Opus 5.0 to your list. (GPT 5.6 Terra tried to give me some kind of driving-at-night-with-a-starfield thing, but failed quite hard).
silasdavis13 days ago
https://gist.github.com/simonw/b6149a49d327164d67d62c3d12992...
> Aside from reading identically forwards and backwards down to the letter
No it doesn't.
tomjakubowski13 days ago
Also puzzling: in the "reasoning" section preceding, that is described as an example of "a one-line self-replicating program."
When I typed "Are we not pure noon, ergo, we play life; yet, we hate bad fear" into Google, I got more weird results from Gemini: it claimed, incorrectly, that it is an anagram of the "well-known philosophical statement" (?), "We are not pure nature, we are history".
https://share.google/aimode/wJosKnHig6oVYaG18
(?): the reference seems to be to Jose Ortega y Gasset's line, "El hombre no tiene naturaleza, lo que tiene es historia" -- "Man[kind] has no nature, what it has is history."
aidos13 days ago
That’s… bonkers. I’m not even sure what it’s trying to say
hglaser13 days ago
I saw your username, clicked the link without reading, and was very confused to see a cosmic vortex and not a pelican.
simonw13 days ago
Hah, the pelican is in this other comment: https://news.ycombinator.com/item?id=49537553#49538217
walrus0113 days ago
I'd be impressed if eventually training data sets learn who you are (the specific human) and do something like make this galaxy simulator, but every so often when the user moves the cursor around the star field, a small animated SVG of a pelican on a bicycle appears.
Thought processs: "Oh, simonw is asking me to make something cool, I think I know what he really wants..."
jauntywundrkind13 days ago
it's such a weird split how most AI companies are trying to be the best, but Google really has a different mission statement. they already have users. lots of users. they need to be working on building models they can deploy and use with the most number of people, as they already have the users.
i don't know if Gemini models per se are fully is in line with that purpose, but the results we see keep seeming to be in-line with that split-of-focus.
alex113813 days ago
Google is a top-notch researcher among all the problems people have with it. It has a mix of great products, terrible automated systems (though, I suspect, not as bad as Meta's?) and some historical disappointments
dennis1638413 days ago
It's been great even since gemini-3.1-flash-lite, which I heavily use in both complex vertical domain tools calling, plus JS code writing for eval-style dynamic tools. At least in my applications, cost x quality x speed there are simply no alternatives.
giancarlostoro13 days ago
> this thing is really good at HTML JavaScript is pretty exciting.
I would hope the people who make one of the most used JS engines in the world are capable of making a model good at JavaScript ;)
[deleted]13 days agocollapsed
wyrdcurt13 days ago
Pretty typical "cool HTML toy" LLM output, tbh. The only thing impressive about this is how fast it generated it (13 seconds is wild!), but that's more of testament to Google's infrastructural advantage than to the quality of the model.
For comparison's sake, I tried something similar with a couple other cheap models I've used lately, with the prompt "Impress me. Make something cool in HTML. Ensure that it is mobile friendly." (Added the mobile condition as I was on my phone when I did it).
Mimo-2.5 created something similar, only a bit less complex than Gemini's (though, at least the FPS counter is real!), in a minute or two for about 1/3 of a cent: https://gisthost.github.io/?740c325c21e9bfbee59c4f94d9aab0af
GLM-5.3-Flash, currently my workhorse model, spent 12 minutes (ouch) thinking about the prompt. Didn't cost me anything directly because I have a GLM sub, but I did the math and it would have cost about 1.1 cents through the API. Turned out nicely in my opinion (though in reality, it still isn't really anything special): https://gisthost.github.io/?9ef050e16cec2561e6504e725a3f0bcc
Side note: thanks for setting up that Gist Host tool, it's very convenient!
---
Editing to add this bonus from Mercury-2.5-Preview, which I just learned released a couple days ago. It's much less impressive-looking than any of the above, but it cost less than 1/20th of a cent, and the response was generated effectively instantly: https://gisthost.github.io/?02f40b50aa891bf396bfaaa3a7998203
meerita13 days ago
I think it's not using GPU, because on my Firefox browser all the animations are going 3fps max.
ambigious777712 days ago
Plays perfectly smoothly for me, fwiw (Librewolf 154.0.1-3, windows 11)
cyanydeez12 days ago
next, ask it to document where it got the code from.
pietz13 days ago
Mission accomplished. That's both cool and fast.
wayeq13 days ago
> That's both cool and fast.
and probably a barely modified knock-off of some github project that it trained on
sawjet13 days ago
You're so upset that you have to invent an imaginary hypothesis to make yourself feel better.
superze13 days ago
Yes, very imaginary to think that the code comes from pretrained data and copy pasting whole blocks. It's not like this is exactly how LLMs work.
snet013 days ago
Correct, that's not how LLMs work [0].
simonw13 days ago
Are you a frequent user of LLMs? That "copy pasting whole blocks" mental model doesn't hold up to regular usage, in my opinion.
ChickeNES13 days ago
They probably saw that report years ago of copilot dumping out the fast inverse sqrt function, and assume that's all they can do. From experience most anti-LLM people have either never used them, or used them back in the 3.5-4 era and then never again, though you might have even more experience with those people than I do. :P
superze2 days ago
I am using LLMs daily and I am a Claude max Subscriber. I neither saw any reports about Copilot Dumping sqt methods.
Now that we established that everything you said is wrong, do you have other toxic opinions or was that it?
whateveracct13 days ago
they're wrong but they are right that this isn't interesting
slopinthebag13 days ago
The bar could not be any lower these days I guess
ericol13 days ago
OK, but what about a pelican in a bycicle.
arde12 days ago
For a moment I thought it was a version of goatse. Once burned...
estetlinus13 days ago
LLM: produces a toolbox of an id and a clock
User: use them both
Made me giggle.
cyanydeez12 days ago
next you should ask it to document where it got the code from.
sitzkrieg12 days ago
good to see people still value trinket toys
mcmalayalam13 days ago
[dead]
jampa13 days ago
I've been using Gemini 3.7 for my personal trip planning app. Across multiple benchmarks, it ranks higher on everything I tried:
- Real world knowledge (when a thing opens and closes, the geographic region, historical facts). It's also the best at taking a cluster of places and working out a visiting order.
- Photo ranking (which photo should be the hero). Gemini can tell whether a photo is of the thing or of the view from it.
- Document parsing (extracting the relevant trip info from PDFs).
If you use LLMs for anything other than coding, I definitely recommend not discounting Gemini like I did just because other models are more popular.
handzhiev13 days ago
Gemini 3.7 is my workhorse - fast and good enough for most tasks. Occasionally I go to GPT Sol or Claude to improve Gemini's output or for more complex tasks, but more than of my work usage is Gemini 3.7. Quite happy to test 3.8 now.
owlninja13 days ago
Same here. I see so many people obsessing over the latest most state of the art bleeding edge models and yelling at Google for not being there, but I feel like the vast majority of people don't actually need those models. Flash has just been super useful and incredibly fast in my experience.
aero14213 days ago
I prefer luna for most development, especially when I am guiding the process. Sometimes terra. I have had terrible results coding with sol. It is way over-tuned on RL to make something that completes the task, no matter what. I end up with way too much code that does a lot of things I didn't ask for.
sneezychl13 days ago
Try planning with Luna, implementing with Sol with guidelines to not exceed the given scope.
Sounds counter-intuitive at first, but Luna is overall better at sticking with what works. Sol is wicked smart but needs constraints.
greenavocado13 days ago
IME you're supposed to have Sol drive Luna sub-agents to do 90% of the work. Sol should primarily be the verifier and goal setter. Use omp.sh with Task Delegation -> Always to strongly encourage Sol to drive Lunas. Also Luna prefers to be talked to with English in XML.
handzhiev13 days ago
I love Luna too. An excellent model and still usually better value per dollar than Gemini if you pay for API tokens. Things may change with 3.8 - we'll know soon.
jesuslop13 days ago
I setup Luna as main Claude Code driver (so zero anthropic api use) and it nailed crisply a handful of python tasks, gonna continue this way.
kelvinjps1013 days ago
Why not use codex or an open source harness?
jesuslop13 days ago
That is a very valid question. I happen to want to get Claude Code muscle memory under my belt for professional reasons in addition to get side projects advanced, could have settled for Codex else. Also OpenCode with eastern models gets part of the job done. In CC beyond using Luna for the cheap, I am using DeepSeek flash v4 for subagents, that is a further cost shaver. Not sure if in Codex I could do that.
antonvs13 days ago
And much better bang for the buck, as well.
When I read all the issues people have with Claude - the aggressive guardrails, the cost, how quickly it burns tokens - it seems almost masochistic to use it. Just seems like herd behavior - people use it because everyone else is using it, and because they believe it’s the “best”, whatever that means. (Benchmarks certainly don’t help define that.)
greenavocado13 days ago
How are you able to get lots of usage out of it cost effectively?
handzhiev13 days ago
Google One plans are quite a good value actually - for a few bucks you get more Gemini plus space in Drive and other extras. Even through API, $3.75 for nearly Sol-level quality isn't that bad. And let's not forget you can use it for free in AI Studio, and in the user app (even free accounts get tons of usage, though it's still 3.6 there), and in Antygravity.
greenavocado13 days ago
That's the thing. I am completely lost because there are so many redundant paths to get the same thing and I'm trying to figure out which one is the best deal
qlte13 days ago
Well are you looking for a subscription or pay-as-you-go API usage?
  Subscription? -> Google One plan (http://one.google.com/)

  API? -> AI Studio (https://aistudio.google.com/)
Google Cloud -> Gemini Enterprise AI Platform (https://cloud.google.com/ai)
mark_l_watson13 days ago
good summary, thanks. I used to use Google Cloud for consulting and projects (I worked at Google for a while, and there is some nostalgia) so I have Gemini API via Google Cloud, but I am retired now. Your post reminded me that I need to shut that all down and switch to getting an API key using AI Studio.
I have spent two months experimenting with a wide range of US and Chinese models, and I had a lot of fun doing that, but I am in the process of switching to just using local models, using Gemini on an API if I need it, and once or twice a month when I really need help on something difficult, I use something top-tier like Kimi K3.
-0_0-13 days ago
This is what killed Gemini for me. The model might well be great, but the ecosystem Google has built around them is a confusing maze of not-quite-there products.
trvz13 days ago
Just put Mythos on the task; it’ll work out the best way in a measly few hours.
handzhiev13 days ago
That's Google at its best :)
seanmcdirmid13 days ago
Ultra AI is like $99/month, and it is hard to exhaust unless you are running a lot of concurrent requests.
shrikant13 days ago
What harness do you use for Gemini? Antigravity?
handzhiev13 days ago
AGY is best probably, yes. That's what I use. It works with others too, like OpenCode etc.
CamilleScholtz13 days ago
I've been benchmarking[1] models for trip planning and world knowledge specifically (to decide on which model to use with my travel app), and the Gemini models consistently come out on top.
colechristensen13 days ago
I started trying out 3.7 Flash this week and it is competitive with opus/fable and also FAST. It is getting work done that anthropic models were struggling with and the speed with which it does is quite a bit noticeably faster.
Beginning to think Google is a dark horse in this race and some of Anthropic's "everything feels janky and rushed" karma is going to catch up.
cousinbryce13 days ago
I use Gemini because I feel like Google will win the AI race, and it’s Good Enough
baq13 days ago
My long term base case, too, but they need to install Demis as CEO and I don’t think either side is ready.
throwaway21945013 days ago
I want to believe this, but every time I try Gemini coding assistance within Colab it's utterly dire. Code gen in a cell is OK, but things fall apart when you try to get into a feedback loop. The system prompt/harness fails to inform the agent about what it can and can't do, or does and doesn't have access to. It will confidently tell you it's done a thing, and then you ask, it admits can't actually do that but will happily try and fail again. Very frustrating, because I really like Colab as a platform for little reproducible experiments that may or may not require CUDA.
spacebanana713 days ago
I suspect Gemini doesn’t focus that much on coding, at least compared to frontier labs. It’s not part of Gemini’s core business case.
Gemini’s integration with maps and search is more important for Google.
cousinbryce7 days ago
That’s a good point, and probably why it’s a multimodal model. I wouldn’t be surprised if it’s over index on code written by Googlers.
re-thc13 days ago
> Beginning to think Google is a dark horse in this race
Google was so hyped up early Gemini 3 era (only some months ago). And now dark horse? The TPU takeover almost crashed nvidia and everyone else.
colechristensen13 days ago
Hype that burned out pretty quickly, it's hard to speak to the size and significance of old hype, I never felt it.
Every time I personally tried Gemini models up until last week they simply couldn't do the long complex tasks I'd being doing with Anthropic models for many months.
dismalaf13 days ago
> Real world knowledge
For awhile now I've found Gemini will use Google search for pretty much any real world knowledge, which is a huge plus IMO. It's basically Google with a much better frontend and no ads/seo nonsense.
altmanaltman13 days ago
> basically Google with a much better frontend and no ads/seo nonsense
so far
fc417fc80213 days ago
I think it already has them but it's much more subtle. Also useful. When I've made certain sorts of queries I've had the distinct impression that it was attempting to very gently steer the conversation with suggestions. But it was brief, still answered usefully, and didn't resist going in the direction I wanted. So a win-win tactic I guess.
For example find a beautiful landscape shot of a place that just so happens to be accessible to tourists and ask it something along the lines of identifying the location. IME it will noticably steer the conversation towards relevant commercial offerings and offer (entirely unprompted) to help plan a trip.
Or ask it about a certain category of product with some requirements and it will initially present (relevant) options that look like paid placement to my eye. But if you ask it's happy to go on to turn up lots of alternatives and enumerate tradeoffs.
Assuming I'm correct the subtlety is on par with product placement in movies. Certainly leagues better than the internet advertising we've suffered to date.
rstuart413313 days ago
It definitely steers. For example if it suggests travel plans, the booking links it provides give Alphabet a cut.
As you say it was subtle, along the lines of "oh, if you are planning on going to the place you are researching, here are some helpful links to places you can stay". Subtle, in that it didn't get in the way of main result, so I didn't mind overly. Insidious, as I only noticed because I wondered why it was providing those particular links and looked them up. I can't see how you could ad-block them if I did object.
And worrying, because these unblockable sneaky ads are just a first foray coming from a company that prostitutes its own app store searches, by making the first and most obvious result utterly unrelated to to the search topic. Instead it's who paid them the most to be there. That behaviour is why everyone dumped Alta Vista when an alternative came along. Alternative Android app stores can't come soon enough.
They already skim off 15% of purchases which I'm sure makes their Android operation return a profit that makes other industries drool. Debasing their search to ad a tiny bit extra on top must by driven pure greed. Senseless, as I'm sure it will come back to bite them in the end.
dismalaf13 days ago
Fair. But I think there's a good chance it stays that way on paid plans. YouTube Premium is still ad free.
Also them having their own silicon means they don't have to pay the Nvidia tax and can keep costs a lot lower.
kridsdale113 days ago
This thinking is why I am all in on GOOG shares. As a bonus, that means I’m getting part of Anthropic’s gains as well!
davedx13 days ago
There are some subtleties though. For example, with Gemini search grounding (this was a few weeks ago), you cannot give it a domain whitelist, only an excludelist -- with Anthropic's API you can do both. For somewhat niche search tasks like "Find LinkedIn profiles matching this ICP", Anthropic wins there.
That being said, Anthropic is also so insanely expensive for everything I ended up switching that particular part to Exo instead...
kaeluka12 days ago
Maps grounding is an amazing interface for Google Maps - „I’m at x, need to be at y by 5pm. Find me a route that’s walkable and has a good vegan restaurant and a toy store“
rahimnathwani13 days ago
One thing in your comment surprised me: "when a thing opens and closes"
Why you would rely on the model's weights to know opening hours, instead of having the model call a web search tool to verify it on the official site?
plaidfuji13 days ago
I believe Gemini Flash is smart enough to know when to ground with web search. Their app has been saying it’s running a web search on almost all of my queries since 3.6. And given that Google … is Google, I trust them with web search grounding more than anyone else.
panarky13 days ago
It can also ground with Google Maps data in addition to web search.
jampa13 days ago
I wasn't trying to be precise originally, I just tried to fit activities into "morning / evening" buckets. I did the whole itinerary with Opus first, but when I gave it to Gemini 3.7 Flash to review, it started correcting it with "this place will close 5PM" or "this place is closed for good".
It was right on every nit, so it was surprising how well the model knows these things. If I ever release this I'll probably need the SERP API or Google Maps SDK (which I've heard is very expensive now), but for a personal trip where I will verify manually, using the LLM is okay for now.
rahimnathwani13 days ago
When you called the Gemini API, did you opt in to using search grounding:
tools=[{"type": "google_search"}]
kridsdale113 days ago
Google AI person here:
Using grounding in Gemini is indeed backed by the same canonical data source for business information (like opening hours) as Google Maps. This stuff is available in its own API for a GCP fee, but we’ve built tooling to connect it to the Gemini agentic ecosystem as well.
mft_13 days ago
So if I understand you correctly, Gemini has direct free access to the Google Maps API in a manner that others (people, LLMs) would need to sign up for API access and pay for?
mark_l_watson13 days ago
That is my understanding, which is a nice thing. I use Exa and Brave search APIs separately but the Google bundling is convenient.
Ollama Cloud offers the same thing: they supply a web search tool bundled with cloud API inference services.
NiloCK13 days ago
Gemini models - at least via some interfaces - have tool calling API access to various Google integrations. flights.google.com, maps.google.com, etc.
The info isn't in the model weights.
Because of where I live, there are three viable airports for any given flight I might want to take, which historically has made shopping a real pain. But Gemini (and only Gemini) has greatly simplified it. Pramble plus date range plus destination and it very quickly generates potential itineraries with costs, total travel time (driving included), etc.
mark_l_watson13 days ago
The Gemini APIs have options for using Google Search grounding, or in simpler terms: to process a prompt by first using search to augment the context.
rahimnathwani13 days ago
Right, I mentioned that here: https://news.ycombinator.com/item?id=49539339
jampa was saying that the Gemini 3.7 (a model) ranks higher on real-world knowledge. The point I was originally making is that I would trust any model by itself to answer real-world knowledge problems. If I want to know opening hours, then probably any of the models could find the answer with a web search tool.
Perhaps the Gemini API makes this easier, as the web search tool is built in.
mlmonkey13 days ago
Maybe the model does some tool calling on its own to figure out the times?
rahimnathwani13 days ago
You can opt in on a per-request basis.
Shayk13 days ago
This sounds great to combine with Wanderlog using an unofficial MCP I made https://github.com/shaikhspeare/wanderlog-mcp
Fuzzwah13 days ago
I've just returned home after doing a 100 day "half lap" of Australia in a camper trailer with my family. I made heavy use of gemini to plan much of it. Getting packed up with a general destination in mind and telling gemini "we're leaving X town at 10am and heading to Y, where should we stop for lunch. My wife has coeliac disease, find us somewhere that does good gluten free options" was one of the many things I regularly leant on it for.
Never had a bad suggestion.
dassh13 days ago
In my experience, Gemini 3.7 is excellent for general non-coding tasks. But for coding, especially backend development, I still find models like Opus 5 and GPT-5.6 more reliable.
menaerus13 days ago
If I strip the dependencies out, I'm using it on a 5MLoC C++ codebase, and I found it performs really really well. I am using the Opus 5/Fable in parallel and I couldn't tell the difference. Both models make mistakes here and there.
antonvs13 days ago
I’ve been using Gemini for coding daily since 3.5, mostly on some pretty complex ML engineering projects. It’s great.
What’s an example of not being “reliable”?
robotmay13 days ago
I've swapped over to it in the past two weeks, it's been really good. It does what I ask and doesn't think it knows better than me, which so far has made it the most pleasing experience I've had when slop-coding.
My only wish is it were somewhat cheaper, as it tends to balloon pretty quickly when I'm using it in Opencode. I'm currently trying to offload a lot of work to subagents to stop the context expanding so rapidly. But on the upside, I rarely have to correct it - I've spent far less time arguing with this than with anything else so far.
mark_l_watson13 days ago
I usually use OpenCode for all open weight models but for Gemini I use Google’s agy coding harness (or my own).
Venders coupling coding harnesses with their own models is usually a good thing. Poolside.ai has a combined harness with their own models that works well locally, and the DeepSeek harness with their models is very interesting.
XCSme13 days ago
Yeah, most people keep bashing my aibenchy.com benchmarks, because Gemini is on top, but that's because questions are not coding only...
[deleted]13 days agocollapsed
BlackRabbit113 days ago
Can G3.7 use Google Maps for distance grounding?
porridgeraisin13 days ago
Yep. It has access to much better route planning tools than the other models. The results are really good IME.
BlackRabbit113 days ago
Sounds good!
I've been planing around with LLM-based trip planning for a very long time now as it fits my very ad hoc style of traveling very well.
But distances always had been.. lets say.. difficult.
Will test it with my upcoming trip to Greece then!
dominotw13 days ago
> trip planning app.
this has to be stong suit of ai agents any model
newtwentysix13 days ago
thanks! this is a very helpful one. I am going to try.
forlorn13 days ago
I tried similar travelling tasks but also added transportation and complex transfers (train, bus, walk, next train...). Worked meh and still a difficult thing to do for a llm.
tziki13 days ago
"Claude 3.7"?
jampa13 days ago
I asked Claude to fix the grammar of my comment, and it changed "I am using 3.7 for" to "I've been using Claude 3.7", so they sneaked their own name on it.
trial313 days ago
incredible. further evidence supporting my personal stance to never ever let an LLM write or edit my writing intended for another human being to read. this is all me, baby
dymk13 days ago
you didn’t even read your comment before you posted it?
drusepth13 days ago
Once you've written something, it's incredibly easy to overlook minute changes to the text.
See: why authors wait days, weeks, or even months before editing what they've written (or, if you're more interested: cognitive regression, inattentional blindness, and the effects of misdirected saccades).
dymk13 days ago
He didn’t write it.
drusepth13 days ago
> I asked Claude to fix the grammar of my comment
I read this to mean he wrote the comment, then asked Claude to fix the grammar (as many ESL speakers do). Sounds to me like he did write it.
dymk13 days ago
Then I think you read it wrong, because you don't make that mistake unless you copy-paste your comment out of a Claude window and into the comment box.
BeetleB13 days ago
1. That's a wild conclusion from his comment! Understand that it's not an "either/or".
2. I'd wager the majority of HN commenters don't read their own comment before posting (pre-LLM days).
fc417fc80213 days ago
I can read my own comment twice over and still somehow miss seemingly obvious wording errors.
BeetleB13 days ago
And if you do a 3rd pass with an LLM, people will accuse of you not reading your own comment...
jampa13 days ago
Eh that one is on me, if I think too much about my HN comment I end up deleting before posting it. I rely on the 1 min `delay` set in the profile page to fix before it goes live, but for some reason this time it was set to 0.
jamiek8813 days ago
A two paragraph hacker comment? You burned carbon for that?
gazebo213 days ago
[dead]
leokennis13 days ago
I stopped using Gemini a few months ago because it would often just (partially) reply literal nonsense to me.
Think 2023 style ChatGPT. Something like “to open a document on your Mac click File > Open docurrrar” - like it suddenly forgot it had to produce actual words.
Overall I enjoyed its speed and comprehensiveness. But those occurrences of nonsense just made it feel like a great car that once a month just stops in the middle of the highway.
mattlondon13 days ago
Currently top at https://deepswe.datacurve.ai - beating Opus 5!
https://artificialanalysis.ai/models/gemini-3-8-flash shows an intelligence score of 59, the same as Opus 5 medium!
Wow - for a flash model this seems to benchmark powerfully. Remains to be seen what it is like to use.
theHocineSaad13 days ago
As of writing this comment, Claude Opus 5 has an intelligence score of 63, not 59 (it's not the same as Gemini 3.8 Flash).
With a score of 59, Gemini 3.8 Flash is in eighth place, falling behind even Grok 4.6, Kimi k3, and GLM 5.3.
kamranjon13 days ago
They said Opus 5 medium - which does have an intelligence score of 59 (you have to select it manually from the dropdown to see it)
Squarex13 days ago
They are all much larger and more expensive models. Google does not have a frontier model right now, but for cheap ones, they are better than event the chinese models now.
pietz13 days ago
That's not being debated here. The initial reported numbers were false and this was simply pointed out. You're changing the subject.
mattlondon13 days ago
Opus 5 medium has the same score as 3.8 flash on artificial analysis intelligence index.
Are you implying Google or Artificial Analysis are reporting false numbers? What's your source?
asdfologist13 days ago
BTW you're comparing 3.8 flash high to opus 5 medium. 3.8 flash medium scores lower.
WarmWash13 days ago
Flash models are on the order of 1/10th the size of Opus models, so some flex in the thinking level is fair.
nomel13 days ago
When comparing closed models, the only thing that actually matters to anyone using them is some mix of cost and speed. Considering how much memory a server is using, when evaluating models that you'll never have access to in order to host yourself, doesn't really make sense.
imtringued13 days ago
Your comment is really strange, why are you defensive towards WarmWash when gemini flash 3.8 high is both 6 times faster and costs less, while having the same intelligence score as claude opus 5 medium?
>Considering how much memory a server is using, when evaluating models that you'll never have access to in order to host yourself, doesn't really make sense.
This entire sentence makes no sense given what is being discussed.
nomel11 days ago
I was being pragmatic. These are closed models on closed systems that you cannot hope to host. They are only available as black boxes available over web APIs served by their owners. Within that black box perspective, that we're force to have, the size of the model is, quite literally, just how much memory that server is using.
intelligence/model size is not a useful metric for a black box user.
intelligence/cost and intelligence/speed is a useful metric for a black box user.
Yes, it's cool, but as a black box user, the amount of memory a model is using on a server that I do not own has exactly zero practical use to me.
Cheers!
Topfi13 days ago
Flash is just a name with no defined or consistent meaning even within labs, let alone between them. Considering both are closed weight, there is no way to truly assess how big the size delta between the two is. Then again, who cares about size, performance and end-to-end speed+cost are what matters along with task adherence, task assessment and so on.
Model size also can not be inferred by tokens/sec for a multitude of reasons, but to showcase two examples, Opus 5 and Sonnet 5, as well as Gemini 3.1 Pro Preview and 3.1 Flash have each very comparable output speeds when using the same deployment as a basis for comparison, despite it being very likely that within their generation, the former are larger than the latter. Feel the need to mention this, as I unfortunately stumble upon so many poorly reasoned, speculative hype post trying to infer model size via utterly unreliable metrics, not based in actual data.
It’s like comments below arguing about the reasoning levels not normalized to some metric (like cost, output token amount or duration) but just the labels or high, max, medium, etc. Those mean almost nothing even when comparing models based on the same pretrain (just compare GPT-5.4 to GPT-5.2), they mean less than nothing comparing different labs releases.
WarmWash13 days ago
It's not totally a mystery
https://arxiv.org/html/2604.24827v1
The short of it is by using hard facts knowledge that is difficult to compress, and then quizzing models on these facts and calibrating against a bunch of open models, you can kind of feel out the size of closed models.
Topfi13 days ago
I really like that one, but it kinda highlights what I could have far better explained. Their 90% PI is three times in both directions. Between 3T and 24T for GPT-5.5.
That’s a massively wide, inaccurate and at best barely informative range, demonstrating that even the most well thought out method will yield little usable information.
Additionally, I got some private evaluation taking a similar approach towards gauging models in topics I’ve found either over or underfitted by labs. If we just used that to rank models (not get a potential size range but just a rough order) Thinking Machines Inkling would need to be lager than Fable 5.
duplessitous13 days ago
> [...] shows an intelligence score of 59, the same as Opus 5 medium!
Nothing here is false, you are simply confused. You either didn't read what they wrote in its entirety or decided to reinterpret what they did write.
knollimar13 days ago
"Beating opus" is the false part, no?
imtringued13 days ago
Stop lying. mattlondon said "gemini-3-8-flash shows an intelligence score of 59" which is undeniably correct. You can't say that number is false. You're literally lying.
All you had to do is go hover your mouse over "Models" in the top bar, hover over Claude Opus 5 and and click on medium: https://imgur.com/mlRCrt1
When you do that you arrive on this page: https://artificialanalysis.ai/models/claude-opus-5-medium
The gemini flash page for reference: https://artificialanalysis.ai/models/gemini-3-8-flash
You have to be an incredibly dishonest person to see a 59 on both pages and say "the initial reported numbers were false and this was simply pointed out. You're changing the subject".
porphyra13 days ago
Better than even the Chinese models? That's a difficult-to-quantify, extremely rapidly moving target. Just today, Qwen 3.8 Max 0902 came out with a huge improvement over the previous Qwen 3.8 Max.
spwa413 days ago
> "Google does not have a frontier model right now, but for cheap ones, they are better than event the chinese models now."
Just wow. Someone actually said this.
zeckalpha13 days ago
Google is targeting a different segment of the frontier.
anthonyrstevens13 days ago
That 63 score is for Max. The OP specified medium.
markasoftware13 days ago
On artificial analysis it's only equal to opus 5 medium effort. Opus 5 max scores 63.
Further, opus 5 medium outputs 4x fewer tokens to achieve the same result, negating a lot of the speed difference.
irishcoffee13 days ago
A comparison to an artificial score and a comparison to “the same task”
These folks must laugh themselves to sleep. This whole industry hoodwinked the masses. It’s impressive.
wonnage13 days ago
It’s all just vibes
WarmWash13 days ago
The benchmark also doesn't include speed. You almost think something has gone wrong when using it because it returns full responses so incredibly fast.
scrlk13 days ago
Not just speed, also reliability. IME, Gemini's speed and quality doesn't degrade badly during weekday working hours compared to OAI, and especially Anthropic.
ford13 days ago
I've had Gemini model API use degrade the most out of OAI/Anthropic/Google (often "over capacity" vs true failures)
Not sure on consumer/product use though
scrlk13 days ago
That's interesting to hear. I should have added that I use Gemini through Google AI Studio as my general chat model, which probably explains our wildly different experiences.
sotix13 days ago
This one uses that as a priority weight: https://winstonrc.github.io/ai-coding-agents-leaderboard/
onlyrealcuzzo13 days ago
The rumor is that 3.9 is an equal improvement in all directions, and that it should be another fast follow on like 3.7 and 3.8 were.
It's almost across the board better than Terra at less than half the price. 3.9 is likely to approach Sol at the 1/10th the price.
Hopefully OpenAI releases Astra first, and it's not only better than Sol but significantly cheaper, too.
harmonic1837413 days ago
Curious where did you hear this rumor?
onlyrealcuzzo13 days ago
All the talk on Reddit on Gemini 3.8 discussions: https://www.reddit.com/search/?q=gemini+3.9&cId=1650e403-bcf...
nolok13 days ago
Accordit to reddit talk, Fable 5.1 is worse than Opus 4.6 and 8B models are smarter than Qwen 3.8 Max, I wouldn't take anything said there with any more reliability than an instagram short.
unsupp0rted13 days ago
Reddit thinks Astra will be released today (Thursday/Friday)
bertili13 days ago
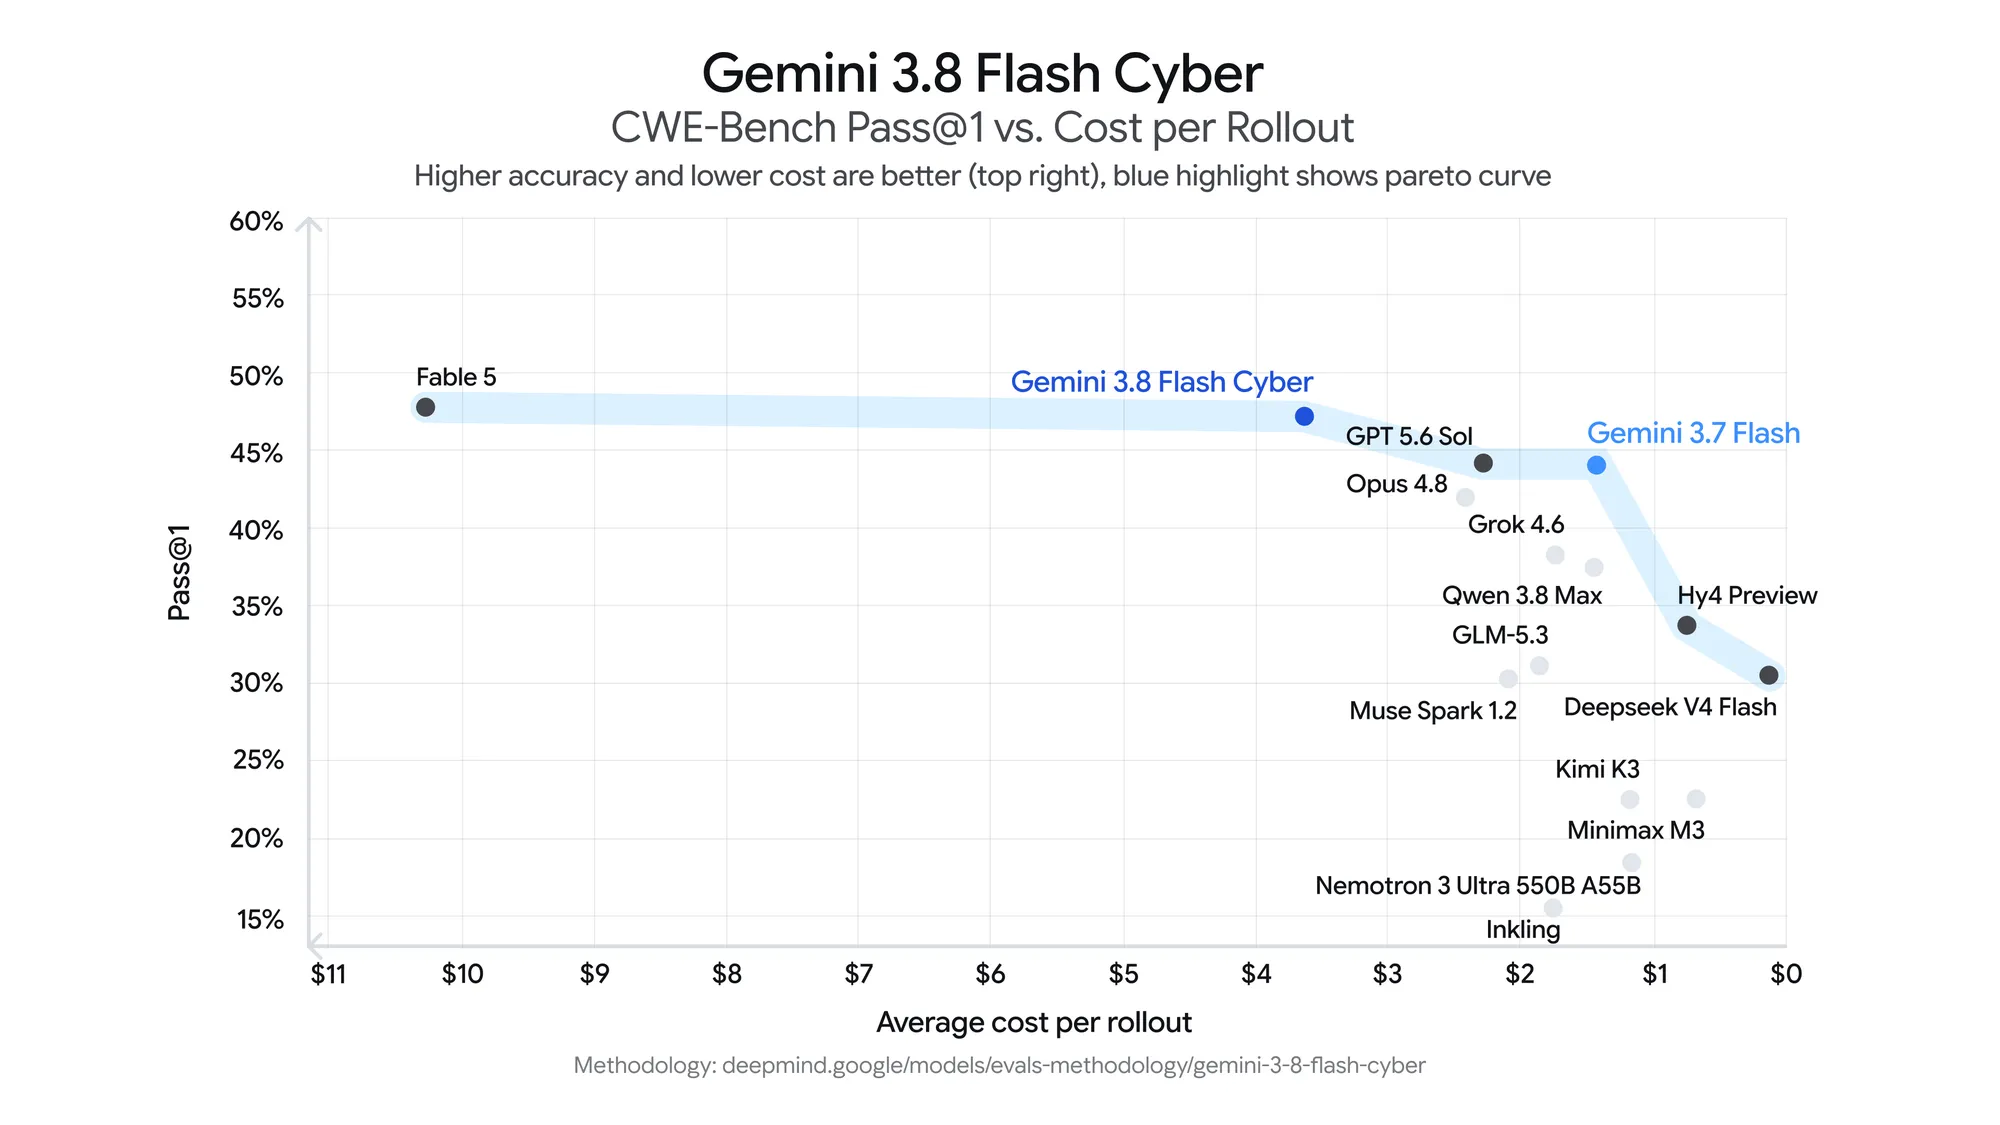
A fifth of the cost of Opus 5! Google is certainly pushing the completion with this.
abirch13 days ago
Gemini hasn't failed me for personal usage yet. I haven't had the opportunity to use it at work.
panarky13 days ago
I've been using 3.7 Flash to audit the work of Opus High, and Flash finds lots of subtle and insidious defects even while all the unit tests are green.
Then I tell Opus to read the audit report and implement what it agrees with.
Flash is really good at this, and it is blazing fast in Antigravity CLI. Easily 10x faster than Opus.
Can't wait to try 3.8 Flash. If it's good enough, maybe I'll switch Flash to primary and make Opus the auditor.
porridgeraisin13 days ago
Yeah the speed in agy cli is amazing. Whole files get written and "py_compile"d in a single blink of the eye its crazy.
In india, my telco gives me google ai pro for free. And agy with flash goes a long way.
prodigycorp13 days ago
it's very fast but it still doesnt come close to 5.6 sol, at least for me, in terms of gathering the context necessary to do extensive changes.
MaxikCZ13 days ago
Idk, was building/maintaining simple esp32 control program with antig/opus. After last update it defaulted to gflash3.7. I pasted an email requesting 2 changes into the chat prompt, it did one and took me 4 turns to get that one right.
ttul13 days ago
Crushing it on DeepSWE is a very big deal. Excited to give this a try.
re-thc13 days ago
> DeepSWE is a very big deal
It's clearly been "dealt with" already. When it launched we had interesting gaps and definitely differences. Now every new release is "crushing it".
ttul13 days ago
Will look forward to the "feel" of the model in real testing. But I agree that these benchmarks do get "dealt with" rapidly. That's a shame, but I guess it's the times we live in.
pietz13 days ago
I know everyone is benchmaxxing but this one feels one step too far. Doesn't DeepSWE have both public and private tasks? I'd love to see the diff here.
It looks more like Google execs losing their mind and pressuring researchers to put DeepSWE directly into the training set.
rickdg13 days ago
Check DeepSWE for number of agent steps.
Gecko407213 days ago
Google - we're so back
oceanplexian13 days ago
Only 1 point behind the Chinese SOTA from two months ago.
roosterIllusi0n13 days ago
I had qwen 3.8 3bit model drop into chinese on long runs. I had to remind it to use english. Its still better than every gemma model I tried. Gemma deleted files on a harddrive to make space when there was over 2TB free. For long runs, gemma is useless.
nolok13 days ago
If you care about points sure, but personnaly I care about price, performance, speed and reliability
wwind12313 days ago
I've been trying this Gemini 3.8 Flash for a day. Looks not much different than Gemini 3.7 Flash in my use case: I have Codex (gpt-5.6 sol) write up a design plan to implement a feature or refactor a portion of a system I am building, and have Claude (Opus-5) and Gemini (3.8 Flash) review and critique the plan, until all problems are addressed by Codex and approved by the reviewers; then have a cheaper model of Codex (gpt-5.6 luna) implement the plan, and still have Claude (Opus-5) and Gemini (3.8 Flash) review and critique the implementation, until all problems are addressed by Codex and approved by the reviewers.
The result is the same as the previous Gemini 3.6/3.7 Flash days: Claude could always note much more problems in Codex's plan and implementation than Gemini could - the ratio is like 10:1.
I occasionally switch the roles between Codex and Claude, and result is the same, Codex could always catch much more problems in Claude's plan and implementation, than Gemini could.
So I am guessing in a relatedly complex codebase, Gemini is much less effective in acting as a guardrail (or a senior engineer/team lead) than the other SOTA models.
camkego13 days ago
I find this very interesting, I wonder if there is a public benchmark that reflects this “red team coding critique” aspect of the current SOTA model that reflects what you have observed.
It would be really useful to observe this in a benchmark vs. the more common “go implement this, or fix this bug” type benchmarks that seem to be prevalent.
wwind12313 days ago
Yeah, my tool to automate these review loops is https://github.com/wwind123/coding-review-agent-loop . It's basically a script calling Claude, Codex and Antigravity CLI's. The benefit of using CLI's is, the tool uses quota in your subscription plan of these AI providers, which is much cheaper than using extra tokens from the same providers to do the same thing.
A couple of months ago (before opus-5 and gpt-5.6 sol), The ratio of problems caught by codex/claude vs gemini was more like 2:1 to 3:1. But now it seems codex and claude have made huge leaps and gemini is more or less staying put.
wwind1239 days ago
Amazingly, these few days the Gemini 3.8 Flash (High) has been catching much more problems in code reviews than before. I think it started from the second day since I posted the observation above. Maybe somebody from Google saw my posts and tuned some knobs in the model to allow more critical thinking?
Another observation, Gemini's review on code is more critical now, but its review on design plans is still quite agreeable - it tends to approve Codex's design plan immediately, while Claude could often pick out a bunch of problems in the design plan in the first round of reviews.
kimjune0113 days ago
deepswe is public and can be considered contaminated.
sunaookami13 days ago
>shows an intelligence score of 59, the same as Opus 5!
...on Medium reasoning. Claude Opus 5 (high) is the default in e.g. Claude Code and scores 61. Still very impressive.
satvikpendem13 days ago
We'll see about that. I suspect benchmaxxing as all the labs do as I haven't found Gemini models to be nearly as good in agentic engineering compared to Claude or GPT models.
NitpickLawyer13 days ago
If anything, gemini models are the least benchmaxxed out of any lab, IMO.
onlyrealcuzzo13 days ago
And the benchmarks agreed with you... until now.
So, yes, maybe it's still not - but this would be the only time it would be highly suspicious / obvious benchmaxxing / obviously bad benchmarks.
rickdg13 days ago
Check number of agent steps.
jrflo13 days ago
sidenote, but wow sonnet 5 is shockingly bad on this benchmark.
notatoad13 days ago
sonnet 5 is bad by almost any metric.
anthropic really needs something to address the cheaper end of the market before they get left behind. Sonnet 5 sucks, and Haiku hasn't been updated in a year. meanwhile we've got gemini flash, luna, and GLM5.3 all delivering 90% of the performance for a small fraction of the cost. paying $25/mTok is going to start looking pretty silly soon.
surgical_fire13 days ago
> flash, luna, and GLM5.3 all delivering 90% of the performance for a small fraction of the cost.
I find GLM5.3 so much better than Sonnet it is not even funny.
Sonnet behaves like a cheap model while being very expensive.
WhitneyLand13 days ago
There are important gaps in that hot take.
For example, it's not even close to Opus 5 on Terminal-bench 4.0, 19.1% vs. 51.8%.
pkos9813 days ago
Wait a week with your judgement - most likely, Google is just bench-maxing very hard. If you look at the previous Flash models and the announcement on Google I/O, it was an absolute disaster. Reality diverged very much from the marketing (supposedly great benchmarks).
simonw13 days ago
Pelicans (thinking effort high, medium, low): https://tools.simonwillison.net/markdown-svg-renderer?url=ht... - high cost 8.9742 cents
Here are the 3.7 pelicans for comparison: https://tools.simonwillison.net/markdown-svg-renderer.html?u... - high cost 8.4387 cents
(I think thinking level low is a regression on 3.8 compared to 3.7.)
onlyrealcuzzo13 days ago
This is in comparison to Fable:
> https://tools.simonwillison.net/markdown-svg-renderer?url=ht...
> Took just under 14 minutes to generate, and at 65927 output tokens cost me a hefty $3.30!
So 50x cheaper - and how much faster?
simonw13 days ago
The Gemini models have openly trained for SVG output, apparently with a specialism on animals in forms of transport! https://twitter.com/JeffDean/status/2024525132266688757
scosman13 days ago
Community effort happening here to build the ideal dataset: https://github.com/scosman/pelicans_riding_bicycles
isoprophlex13 days ago
Wow nice. If an llm could replicate these excellent examples, I'd consider the pelican benchmark fully saturated.
FergusArgyll13 days ago
If that's not art, I don't know what is.
MadameMinty13 days ago
Nice. Really high quality SVG pelicans riding bicycles here.
phatfish13 days ago
Come on, don't provide the smoking gun that shows how to draw a pelican riding a bicycle. If it's on the public internet it will end up in training data and invalidate this important LLM capability benchmark.
dieortin13 days ago
I don’t know if you’re joking, but I don’t see anything in the linked tweet which suggests that is the case
simonw13 days ago
Watch the video. It's from then-Gemini-lead Jeff Dean and the video shows off an animated pelican riding a bicycle, a frog on a penny-farthing, a giraffe driving a tiny car, an ostrich on roller skates, a turtle kickflipping a skateboard, and a dachshund driving a stretch limousine.
JacobAsmuth13 days ago
I'm confused. This doesn't mean they trained on it.
simonw13 days ago
I didn't say trained on, I said "trained for SVG output". Gemini team members have publicly stated that they have trained for SVG:
https://twitter.com/sunjiao123sun_/status/202455551655137292...
> I’ve been developing the SVG generation capabilities for Gemini 3.1, and the complexity of the SVGs is stunning.
> This allows UX designers to transcend pixel constraints and directly output structural, production-ready code!
uif12413 days ago
Yesterday's transcript of the best version from Fable looked like Fable already knew exactly what it should do without "thinking". In other words, there were no passages like "on the one hand I could do this, on the other hand ...".
It saw the fish in the basket from some other previous attempt but completely missed the gap between the tires and the rims where the background shines through (now it knows after scraping this comment and watch the next transcript).
mrdependable13 days ago
Why are the SVGs getting more detailed rather than just more correct than previous models?
trentor13 days ago
Because people tend to like fidelity more than correctness.
aesthesia13 days ago
It bugs me a little that "fidelity" has connotations other than "faithfulness to an original"---fidelity should be basically the same as correctness here!
nonethewiser13 days ago
That’s really not the highest fidelity interpretation of “fidelity.”
aesthesia12 days ago
Fair, but correctness should be a necessary component of fidelity.
frumiousirc13 days ago
My dictionary writes: "precision * accuracy = fidelity".
neuronic13 days ago
If correctness would matter anymore, people wouldn't be using LLMs in the first place.
hughw13 days ago
It's about to squash a tiny baby pelican
jpadkins13 days ago
The rendering of the gullet is very poor, because its both behind the handlebars but in front of the bike frame (impossible geometry). Surprising because gemini is usually pretty good on geo spatial skills.
Edit: scrolled down to medium effort, its better but also has a weird clipping issue with the fish in the beak.
neuronic13 days ago
LLMs are not intelligent and don't actually understand the concept of a bicycle. Parrots also don't understand human language but they're really good at pretending otherwise.
jpadkins7 days ago
Neurons are not intelligent and don't actually understand the concept of a bicycle. LLM are just one component of the system we call "AI" used to generate the SVG. The parrot argument is tiresome because the LLM alone is not what enabled the recent take-off in practical intelligence we have seen in the last 12 months. The tooling, reasoning chains, harness to self evaluate the output, etc, etc are all needed to make the pelican. Just like the prefrontal cortex alone can't make a pelican with humans.
lern_too_spel13 days ago
The fenders are a nice touch, but putting the fenders through the tires seems like a design flaw.
anigbrowl13 days ago
These are becoming unreadable as the reasoning chains expand. I think you should consider reformatting them and either putting the image first or else folding the COT output.
simonw13 days ago
Yeah, putting reasoning in a details/summary is a good idea.
[deleted]13 days agocollapsed
EugeneOZ13 days ago
Impressive pelicans!
[deleted]13 days agocollapsed
world2vec13 days ago
I mean no offense but these pelicans are a bit tiresome and a very meaningless benchmark. There's no real difference between any of these svgs across models and model versions anymore.
wongarsu13 days ago
If everyone agreed with you, the comment would disappear near the bottom of the thread
I like the benchmark. Yes, it's near saturation for SotA models, but still quite good to show where smaller models stand in relation to SotA
In this instance, I see a great image, but consistently clipping mudguards (both in 3.8 flash and 3.7 flash)
IshKebab13 days ago
> If everyone agreed with you, the comment would disappear near the bottom of the thread
If only it were true that things that are tiresome are unpopular. But witness "6 7", "first post", ... remember the "in soviet Russia" jokes on Slashdot"? It seems like there are a subset of people that simply don't get tired of tiresome things.
bitexploder13 days ago
It is more fun than serious at this point. Don't overthink it :)
simonw13 days ago
Congratulations, you're this thread's "pelicans are tiresome" comment - it's part of the Hacker News tradition at this point.
(Next up is the comment saying that the labs are clearly training for the benchmark.)
world2vec13 days ago
The labs are clearly training for the benchmark.
WarmWash13 days ago
This has been addressed endlessly, for a few years now, and is just as much of a trope as "this benchmark is useless".
_puk13 days ago
anentropic13 days ago
it's a tradition
simonw13 days ago
The most interesting thing about the Gemini models is still their multi-modal support: they accept audio and video input, OpenAI and Anthropic's flagships are still image-only.
Gemini Flash is also pretty cheap, so it's a great family for performing media analysis, like extracting structured data from images and video.
WarmWash13 days ago
Lost in the news was their update to gemini video analysis yesterday, dramatically cutting tokens (up to 88%!) needed to analyze videos.
https://blog.google/innovation-and-ai/models-and-research/ge...
anthonypasq13 days ago
wow thats actually pretty sick, ty, I could use this in the app im building
Matsta13 days ago
Yeah we use it a lot for analysing streams and clipping content. As well as analysing social content that gets put out.
We transcode everything to 480p before we send it to Gemini batch api. Works great
drusepth13 days ago
Interesting side note: although Opus is still image-only, you can still drag videos into Claude Code and it doesn't blink an eye; it just strips it down to a series of images to parse.
True multimodal support would be way better, but I have no issues pasting in full screen recordings while QA'ing games and having Claude identify and fix issues in the video.
ray_kay77713 days ago
Agree - I do video editing via Claude Code and it does the job just fine. A lot of my tasks involved frame accurate cutting and to do so it will make a composite image of several consecutive frames in a single image and analyse it that way.
EFLKumo13 days ago
Something maybe unfamiliar with you: not about coding but writing. I've asked it to write an argumentative essay, which is a part of "gaokao" (China's university entrance exam), and its work is *extremely* impressive. speaks and writes like a real senior high school student, and the opinions unfold progressively with deep hierarchy. I don't know how the Gemini team reaches this because this kind of Chinese capability literally outperforms at least 2/3 Chinese students, no to mention those who speak Chinese. After all, the model speaks like a real humankind if you prompt it well. That's AGI guys
SneakyZero13 days ago
Gemini is known for good at creative writing in the Chinese writing community. It's a bit ironic though. Google has probably the most and best code base among all tech companies but its Gemini is bad at coding. Google has no access to Chinese market but its model is incredibly good at writing in Chinese.
chii13 days ago
> Google has probably the most and best code base among all tech companies but its Gemini is bad at coding.
probably because google knows people would want to extract google's proprietary code from gemini if they use their own code base to train it! I bet they purposefully gimped it to prevent that from happening.
anthonypasq13 days ago
I think this is because the primary use case of gemini is google search overview and the gemini app. thats probably 98% of gemini tokens. they didnt predict how important agentic coding would become.
cubefox13 days ago
Nitpick, but in my opinion an LLM is an "it", not a "her" or "he". Using male or female pronouns risks anthropomorphizing them which can lead to unhealthy outcomes.
adleyjulian13 days ago
FYI in Chinese he/she/it all use the same pronoun "ta" when spoken.
SchemaLoad13 days ago
They do have a separate character for animals and objects 它 vs 他/她, though I can imagine learning english and just learning ta = he.
livinglist13 days ago
There’s also one specifically for God - 祂, and one for animal - 牠, the first one you can see frequently in Chinese bibles or churches, the latter is rarely used.
[deleted]13 days agocollapsed
literallywho13 days ago
What about languages, such as Russian, where every single noun has a gender assigned (he, she or it) and AI is a he by default (and everything else is already using pronouns in similar way, like a car is a she, a ship is a he).
cubefox13 days ago
That's a good point. Still, "it" makes more sense in English.
EFLKumo13 days ago
Sorry! I was just a bit excited writing the comment and ignored that :(
cubefox13 days ago
No worries.
postexitus13 days ago
For 60% of the world, it doesn't make a difference. Do not project your gendered (read: sexist) language constructs onto us.
BeetleB13 days ago
Well, my LLM is a "he".
> Using male or female pronouns risks anthropomorphizing them which can lead to unhealthy outcomes.
Ditto for pets.
cubefox13 days ago
Well, I would say your LLM is a "he" just as much as your laptop is: not at all. If you call the laptop "he" that changes nothing.
For animals he/she does make sense, because they are male or female. An LLM is neither.
fwip13 days ago
A goldfish is closer to a person than any LLM.
brap13 days ago
People have been sleeping on Gemini lately but these last few Flash releases (which were very rapid) are damn good.
These sort of fast and cheap models are great for tasks that are verifiable and can be retried infinitely (like coding), you can basically get frontier results with a good harness (at a fraction of the time and money).
mvdtnz13 days ago
As someone who has stubbornly stuck with Claude Code, what's a good harness for Gemini models?
robertn70213 days ago
I highly recommend just getting out of Anthropic's (or anyone's) vendor lock-in. Use opencode or pi. You can still use your subscription pricing using a proxy. I switched to opencode and haven't looked back.
pdimitar13 days ago
How do you do the proxy thing?
robertn70213 days ago
Meridian[0] for Claude Code, CLIProxyAPI[1] for everything else
solarkraft13 days ago
I use OpenCode with my ChatGPT subscription, which is officially supported on both sides and a damn good deal (OpenCode Go is great too).
OpenCode has “providers” for many (many!) other services, but these are almost all unofficial and against ToS (Anthropic being famous for ban-hammering people).
cromka13 days ago
But proxying via Claude CLI is OK? Or also not?
drusepth13 days ago
Antigravity is probably the best of the bunch I've tried. I'd say it's pretty comparable to Claude Code (I use both daily).
VadimPR13 days ago
Antigravity which lacks an auto approve mode? Not really comparable to Claude Code when you're looking to run a team of agents from my experience.
NickHirras13 days ago
In settings, enable Turbo Mode, and Auto-Approve, it will run without stopping for approvals.
drusepth13 days ago
I've curated my auto-approve list to specific commands by approving them with "always allow in this project" (I never want it e.g. committing/pushing to GitHub, removing files, etc without being in the loop) but Antigravity does have both a standard "auto-approve" mode _and_ a "Turbo mode" which disables ALL approvals of all kinds.
KeplerBoy13 days ago
They have an auto approve mode. At least in the vs code plugin.
killix13 days ago
[flagged]
brap13 days ago
Just like Claude Code and others it has the same —-dangerously-skip-permissions flag, auto approves everything
allthetime13 days ago
I resisted at first but now I main antigravity for work. All the software (web, react-native app, client cms platform, postgres backed, multiple ETL systems, a few chat/websocket backends) for my company is loaded into a single project. I spend time writing prompts and forming plans back and forth with the agents then I click GO. Over the past year we've gone from it taking minutes and needing a reasonable amount of back and forth and fixing, to it taking 10-20 seconds and outputting near perfect work within my system accross app/service boundaries.
ryanscio13 days ago
Pi [1] is amazing. Since using it I've felt no need to switch harnesses anymore.
Or choose Oh My PI [2] for batteries included
[1] https://github.com/earendil-works/pi [2] https://github.com/can1357/oh-my-pi
dcchambers13 days ago
Can you use Pi with a Google Pro AI sub or do you need to use API billing?
mredigonda13 days ago
Using API billing would be a bummer because, as far as I know, there's no way to set up a spend cap or pre-pay the API key, correct?
tobias201413 days ago
They finally allowed for a hard spend cap that's easy to set a few weeks ago: https://aistudio.google.com/spend
rkangel13 days ago
If you're happy with API billing then just use OpenRouter: https://openrouter.ai/google/gemini-3.8-flash
Makes it easy to switch between models and I like it for exactly the reason that you're saying - I prepay and so can't accidentally spend my food budget.
danielbarla13 days ago
Aside from the other reply, pi makes it _really easy_ to build your own usage tracking and limit machinery.
I would normally advise against such efforts for a variety of reasons (such as inaccurate tracking, etc), but specifically under pi, this mechanism has been extremely well behaved and accurate for me.
mark_l_watson13 days ago
It is trivial to set up a spending cap on Google Cloud and also on Google AI Studio.
That said, it is probably easier to use APIs from FireWorks.ai, Ollama Cloud, Open Router, etc.
smlx13 days ago
Crush is great: https://github.com/charmbracelet/crush
nxdmum13 days ago
If you're on their subscription plan - agy cli or antigravity ui is the only choice i think.
Anyway - if you're a dev - you would be writing your own agentic env right ? that's the best way forward. I wont tell you more than this . but if you're not - you are losing out .
mark_l_watson13 days ago
I agree, I use my own harness (link to the most stable version, from my Racket book: https://github.com/mark-watson/Racket-AI-book/tree/main/sour...) and except for handling user interrupts correctly, writing harnesses that are customized to your workflow is fairly easy.
simlevesque13 days ago
You can use any model with Claude Code. Most chinese one have a Anthropic compatible endpoint and for Google and OpenAI's models you can get a compatible endpoint with a proxy like Bifrost. No need to change your harness.
ddxv13 days ago
The vscode chat is great. Not sure if it's also called copilot, but you can plug in any models there and they get sandboxed, tools and link to your code. Great stuff.
brap13 days ago
Antigravity has been also rapidly improving lately, and your can also use any of the open coding harnesses. But I mostly meant “harness” as in your workflow/loop setup.
Imanari13 days ago
Is that possible? What subscription would that be? 'Google AI Plus'?
_aavaa_13 days ago
Do they officially support you using your subscription in other harnesses?
watusername13 days ago
No, and Google actively bans people for using their subscription from other harnesses via various proxies/gateways.
To preempt certain replies, yes, I know you can pay API prices and use whatever harness you want.
cromka13 days ago
But do they ban proxies that use CLI?
_aavaa_13 days ago
Shame. Thanks for the info.
watusername12 days ago
Update: After some backlash, Google has clarified that they will only ban your "Antigravity and/or Gemini CLI accounts," not your Google account. How very generous! Keep being tone-deaf then...
foretop_yardarm13 days ago
Is antigravity still heavily rate limited?
mark_l_watson13 days ago
I agree.
I might be wrong about this, but obviously Google would like to provide inferencing at the lowest cost to themselves, so perhaps their slow ‘pro’ releases and rapid ‘flash’ releases is an attempt to guide people to use more profitable models?
a11r13 days ago
Looks like the strategy of regular updates with incremental improvements is working out well. Interestingly, the biggest jump in Artificial Analysis Intelligence Index score is for reasoning level Medium ( 3.7 was 51, 53, 57 for Low, Medium and High, 3.8 is 52,57, 59 respectively). I think scores at lower reasoning levels are more indicative of model capability since higher reasoning levels are focussed on benchmaxxing. We use the lowest reasoning level in production with good results.
Jcampuzano213 days ago
I'm not an expert but I agree with your statement on the lower reasoning levels.
Lots of models seem to just allow the model to "bloatmax" tokens in order to get bumps at high/max reasoning levels. Many of the max reasoning levels allow models to use up to double or more the tokens the next lowest reasoning level uses. Its basically only useful for people who have no cost or time stipulations on anything.
I think I actually preferred it when we had models that either had reasoning enabled or didn't.
mattlondon13 days ago
Wow this comes after what - 3 or 4 weeks since 3.7 Flash, which was also 3 or 4 weeks after 3.6 Flash IIRC?
I eagerly wait more info but sounds like Deepmind without Demis calling the shots has been unleashed and are operating at full speed? Shocker!
At this point it is a meme of course, but where is 3.5 Pro :)
meetpateltech13 days ago
According to the WSJ, 3.5 Pro is reportedly being skipped entirely, making Gemini 4 the next flagship model after post-training.
hiddencost13 days ago
A month is not enough time for any meaningful change in an organization the size of Deepmind/Google. These models were surely the result of work streams and teams that started under Demis. I think Demis can safely feel proud Deepmind is getting back on track.
aurareturn13 days ago
Reports are that he checked out of day to day work well before his reassignment.
Sometimes it is hard for a scientist by nature to build and iterate and lead revenue generating products.
p_l13 days ago
Now i am awaiting Gemini 3.11 "For Workgroups" to be released early December...
neuronic13 days ago
With Gemini 95 following soon after.
cromka13 days ago
... and the "Gemini ME" expected to be a full AGI model.
FartinMowler13 days ago
Wow, that activated a long dormant neuron. IIRC 3.11 main purpose was to make the 3.1 in OS/2 incompatible.
p_l12 days ago
Popular claim by IBM PR, but the issue was that OS2fW component (which reused locally-installed Windows 3.x) had binary patches it applied to windows core component to turn it from DPMI host (which owns 32bit pagetable etc.) into DPMI client so that Windows would call to OS/2 for handling paging setup, and other details of interop.
The patches were made for Windows 3.1, but not for Windows 3.11 - since the changes resulted in binaries with different offsets, Windows 3.11 used under OS2fW would fail.
EDIT: Source with some discussion of disassembled OS2fW code: https://jacobfilipp.com/DrDobbs/articles/DDJ/1994/9406/9406m...
j-bu13 days ago
"The knowledge cutoff date for Gemini 3.8 Flash is March 2026 – users can expect updated information for some domains while in others they may experience the model’s knowledge is limited to January 2025 (in line with the Gemini 3 Model Family)."
Kind of wild that they haven't (successfully) pretrained a base model since Jan-25.
venusenvy4713 days ago
I'm curious if the knowledge cutoff is important, when the interface (Gemini app) can search online for recent information. Is there a big advantage to having everything internal?
j-bu13 days ago
Not directly - but latest research advancements, cleaner / richer datasets, etc. still require fresh base models. Not everything can be fixed through post training alone (e.g. why GPT-5.5 "Spud" was such a big jump, and also why GPT-6 "Astra" is now supposedly another big leap). Ofc model size etc also plays a role, but my (admittedly limited) understanding is that new base models _can_ also lead to big jumps even keeping parameter counts constant.
StevenWaterman13 days ago
You don't need everything internal, but having some idea of recent events is useful. If you ask it to implement some local AI there's a decent chance it will try to use qwen 2.5 without wondering if anything better came out since
rjh2913 days ago
Search grounding is expensive, you can't force the model to do it either. I use Gemini a lot and it often replies with out-dated data. The more detailed the information you're asking, the more likely it is to be wrong.
npn13 days ago
very important actually. just try to generate code for fresher frameworks/libraries. gemini sucks so bad in real work usage, everything it suggests are outdated and mostly useless.
spider-mario13 days ago
Sometimes, it’s quite presomptuous and doesn’t search when it should. I’ve had to argue too many times with it that, yes, the Nintendo Switch 2 is real.
neuronic13 days ago
[dead]
make313 days ago
That extremely likely just means that they're preparing an omega huge Gemini 4 Pro release and that that's what training right now on most of the compute
andai13 days ago
Wait, I didn't realize 3.7 Flash was already beating Sol on a bunch of the benchmarks. Isn't it a way smaller models?
ipsod13 days ago
IDK if it's smaller, but I know it's way faster. In one test I did, Flash 3.7 high was ~9.4x faster than Luna High.
But, also... Sol crushes Flash 3.7 at writing code in a codebase of any size beyond "tiny".
Flash is my go-to for prototyping, and basically anything that isn't writing production code.
ramon15613 days ago
The only company with a proper TPU set-up is bound to have the fast models, now add a market cap like Google to the mix.
ipsod13 days ago
They've been my bet to win the AI race for a while. I was starting to doubt, but this 3.6, 3.7, and 3.8 arc has anchored me.
Diederich13 days ago
Totally agree. When this current wave of GenAI really started heating up, I guess 2020-2021, my analysis was very straightforward. What are the high level inputs to long-term success? I basically came up with a couple of criteria:
1. Data. Lots of data.
2. Money. Lots of money.
3. Access to necessary hardware.
4. Business alignment/will to do it.
5. Access to talent, current and future.
This is certainly incomplete/naive. In my mind, though, Google was the clear answer.
On a more personal level, I've been deep into the Google ecosystem since I got [email protected] in 2005. (I actually paid 50 cents on ebay to get a very early invite.) There was no question in my mind that Google's AI work would deeply integrate into their whole ecosystem in very powerful and productive ways. (Yes, I can join you to discuss, at length, the various ways that Google's dominance is problematic/scary.)
Having said all that, I'm quite happy that there is, at the moment, a very rich competitive landscape. Indeed, not too long ago, with Gemini Pro 3.1 languishing, I moved most of my deeper thinking work to ChatGPT, which was, for me at least, clearly outperforming Gemini.
While I certainly didn't anticipate it, Google's strategy of making their fast/relatively inexpensive models surprisingly powerful has been a welcomed surprise.
imtringued13 days ago
I think you forgot to mention energy efficiency. If you build AI hardware in-house, your only other expense is energy and the producer surplus is greatest for companies producing below the equilibrium market price.
It's the difference between billions in revenue and billions in profits.
ipsod13 days ago
Not only do they have access to the hardware - they've been developing it in-house for years.
esafak13 days ago
Luna is way slow. I don't remember an OpenAI model ever being this slow.
edit: I have a subscription; direct call.
dannyw13 days ago
Are you using direct or via OpenRouter? I think OpenRouter Luna always uses the `flex` tier, which is quite a bit slower.
suprfnk13 days ago
Way slow? What are you comparing with?
MrBuddyCasino13 days ago
Its not good at not making mistakes, but what it produces is structurally quite nice, not over-engineered (looking at you Sol) and its personality isn’t annoying (looking at you Claude). A bit like Grok Code, but Grok is a better coder.
momojo13 days ago
Same. Love oneshotting or sanity checks. Which fortunately is a lot of my workflow (lot of long tail stuff fits in one prompt).
refulgentis13 days ago
They're quite selective in benchmarks, c.f. notably only bad one is 10% on TerminalBench. It's a really addled model, one time I said "Hi" and it built out a 4 panel hello world app with (fake) weather, a todo list, and a couple other things I forgot. I wouldn't be comfortable saying "ignore the #s!" except when I complained it was trash and way overcooked on agentic coding yet not good at it, and a couple DeepMind ML people liked the tweet.
zuzululu13 days ago
i discount people who lean too heavily into benchmark as the authoritative truth when it comes to evaluation of coding capability of these models.
experience tells me that those people simply have not used models for a long period of time specifically on coding and have run their own comparisons
to someone who uses all vendors, the differences are very palpable and drives purchase decisions.
also keep in mind Gemini and other labs have repeatedly done benchmaxxing, you must have your own benchmarks to evaluate these models.
realist_not13 days ago
It's pretty good if you can actively steer it , its actually really really good , the antigravity free tier and pro tiers are generous as well . I'm shocked at how fast it generates tokens.
worldsavior13 days ago
Some would say it's Google's TPUs.
MrBuddyCasino13 days ago
Can the free tier be used outside Antigravity CLI? Because its security prompts get old pretty quick.
pampas13 days ago
Gemini 3.7 Flash was already smashing more expensive models on my Redactle benchmark https://redactle.net/llm-leaderboard which mostly tests omniscience.
andai13 days ago
That difference in both time and price is nuts!
kamranjon13 days ago
They've interestingly left out any mention of speed.
I have been testing 3.7 flash against 3.5 flash and it seems to lose every time in overall latency. Every benchmark I've seen seems to suggest the opposite[1] - that 3.7 flash is significantly (at times 2x) faster than 3.5 flash - but I have never been able to prove this out in real world use cases.
Has anyone found their latency numbers to actually be accurate? Is this why they've toned it down in this release? For context, I'm testing larger generation payloads that take 8-10 seconds in 3.5 flash and 15-25 seconds in 3.7 flash. Lowest reasoning settings in both cases.
1: https://artificialanalysis.ai/?speed=intelligence-vs-speed&m...
pampas13 days ago
In my niche Redactle puzzle solving benchmark [1] I noticed Gemini 3.8 flash is slightly faster than 3.7 flash. They both smoke every model I've tested. I have not yet run 3.5 flash. Gemini models are great at this task because they seem to have exact Wikipedia text baked into the weights. When I rewrite the wiki text a bit it's not able to one-shot the game so much.
film4213 days ago
It depends on how you're querying Gemini models. OpenRouter is the fastest by far. I'm guessing they bought the dedicated pipe from Google. Gemini via VertexAI and consumer API has pretty bad latency.
kamranjon13 days ago
Yea I am testing through OpenRouter - have you noticed 3.7 flash being significantly faster?
film4213 days ago
I guess it might be relative, but switching from VertexAI endpoint to OpenRouter was like 2-3x faster for us.
abixb13 days ago
I like Google's strategy here. These new Flash models of late (Flash 3.6, 3.7 and now 3.8) have obviously been distilled from a much larger unreleased model (Gemini 3.5 Pro, iirc from the rumors).
One aspect of model releases that don't get discussed as much are the cache invalidation (changes in underlying architecture, weights, or tokenizers); I assess Google seems to be squeezing the maximum out of the last 'Pro' version they released with 3.1 back in February.
Small models cataching up with their bigger siblings are fantastic news.
alephnerd13 days ago
A couple larger GCP customers requested this for sometime, especially on the cybersecurity side.
A SOC/IR or AppSec team doesn't need a generalized model that knows when Chaucer lived but it absolutely needs a model that can efficiently, quickly, and accurately prioritize vulnerability severity or validate patches.
xnx13 days ago
Seem like a great, no-compromise, upgrade over 3.7 which is already a bargain, fast, and doesn't have the brain-damaged writing style of Claude.
fitsumbelay13 days ago
that's certainly what it's looking like so far. kind of mind boggling ...
raincole13 days ago
I don't know if Google is having the worst marketing fumble or the most genius marketing one. Their "flash" models are very comparable to other companies' "pro" or "flagship" models. It seems to be a quite counterintuitive naming convention as it undersells the models.
Unless they have an even more powerful Gemini Pro in the oven...?
anthonypasq13 days ago
the 3.5 pro pretrain was a complete disaster, they shelved it and are now working on gemini 4.
3.0 flash -> 3.8 flash is all post training which is pretty impressive.
lawrenceyan6 days ago
Not sure if you'll see this comment since it's been a week, but how did you find this out? Is 3.5 Pro officially cancelled internally? Are they only working on 4 Pro now?
chrsw13 days ago
Do labs come back from disasters like GDM’s 3.5 pretrain? I am thinking of Meta’s Llama 4. Meta is just now starting to be taken seriously again but they are definitely not at the frontier. And when I say “come back” I mean have an Opus 4.5 moment, which was really mind blowing for me at the time. Fable was a similar leap, just not as big.
suprfnk13 days ago
Unless the company is going under, why not? Let's say Google releases Gemini Pro 4 tomorrow, and it's better than Fable and Sol; lots of people would switch over to it.
AI models are almost completely interchangeable, so the best/cheapest/fastest whatever will always have a market.
chrsw12 days ago
I agree we’d switch to it. I guess what I’m doubting is if a company can recover from that sort of stumble in the first place. And they might not want to either. They might think there’s more value somewhere else besides trying to get back to the absolute performance and capability frontier. Smaller models targeted to specific domains that large models would be too inefficient at no matter how large they get or how clever you are at distillation, for example.
deaux13 days ago
OpenAI had such a disaster themselves before, GPT-4, so they replaced it with 4o.
RugnirViking13 days ago
gpt4.5 was also one such disaster for them iirc
rahidz13 days ago
The conspiracy theorist in me wonders if it's about keeping the federal government out of their business after seeing what happened to Sol & Mythos.
make313 days ago
My assumption is that they're cooking an ultra humongous Gemini 4 Pro release. They certainly have the cash and the compute for it, and it's so obviously the thing to do from a strategic perspective.
drowntoge13 days ago
Well if that's the case, it's been in the oven for quite a while now.
owaiswiz13 days ago
not saying they do have a beefier pro, but even if they did, isn't the delta between flash vs pro models reduced quite a bit? (e.g glm 5.3 flash vs 5.3, v4 flash vs v4 pro, sonnet 5 vs opus 5)?
nxdmum13 days ago
so far using Gemini from 2.5 Pro to date (3.7 flash) - the way google trains the model it seems - is to identify top 3 to 4 things to fix first. as a result gemini is not that good in being thorough - but it's a needle mover . Opus5 Opus4.8 and Fable always point out things that Gemini missed. but Gemini was a needle mover - identifying the most important things to fix.
I always enjoy interacting with Gemini . When i ask it questions about designing a new model etc - it's always the most helpful and encouraging . I really want to thank the Google team for this and their happy positive models they generate.
I use gemini flash after a round of deliberation between Sol and Kimi these days on the main plan . Kimi 2.7 paired with Gemini 3.5/4.6/3.7 flash has been my implementer - Kimi k3 and Sol 5.6 have been my planners and code reviewers.
I would have ideally like Anthropic and was on their USD 200 plan - but after they didnt sign the letter for Open source models - i dropped my subscription . Wont make a difference to their lives.
But Sol is great . Combined with Kimi K3 for adversarial plan reviews - you get robust plans . And Sol as a reviewer for Gemini/kimi 2.7 - you get great edge case handling and robust code.
I also integrated muse 1.2 - on the contributor tier - and I Just saw facebook release 1.3 muse . this is great news. The training im permitting is my thanks to FB for releasing the open source models of the past ! Thank you !
lysecret13 days ago
Also just want to let my appreciation here for 3.7 it’s cheap super fast super reliable incredible at information parsing eu host able (important for us) and perfectly integrated into gcp. Great job google!
MrBuddyCasino13 days ago
I hope they bring a lite version, its good enough for information parsing and very cheap.
weird-eye-issue13 days ago
Use Luna for that
PaulStatezny13 days ago
It struck me today using Google Antigravity (Claude Code alternative) just how direct and usably terse Gemini is in prose.
I've complained plenty on here about Claude verbosity and TED-talk phrasing, and it seems by contrast Gemini has already arrived at the dream end-state of Claude from a prose standpoint.
Sometimes I ask for feedback, and I get back a list of multiple-choice options as if it's already ready to go. If I indicate I'm thinking about doing something, sometimes it'll just...do it. (Not in an annoying way.)
It seems very geared toward action in a way that's completely refreshing coming from months steeped in Claude essays.
jerkstate13 days ago
3.7 flash was by far the best model for image recognition tasks according to my benchmarks. 3.8 flash didn't regress any candidates and improved some specificity (positive ID of common name vs species name of exotic fruit, correct identification of cast/replica of artifact and statue) but is still relatively weaker (26/30) on esoteric public figures (Korean beatboxers). I'm going to have to make my benchmark harder.
arctic-true13 days ago
I’m very curious about your esoteric public figures benchmark, do you ask it in English or Korean to identify the person? Does it change the result? I wonder if having data labeled in only a given language (or web sources in only a given language) change the output.
jerkstate13 days ago
I haven't tried asking it in Hangul but these particular artists (and the photos I'm using actually) are linked to their romanized english names on e.g. Fandom so it's not unfindable on the internet
pampas13 days ago
Gemini 3.8 Flash is top of the Redactle LLM benchmark but so was Gemini 3.7 Flash. Both one shot all puzzles in the evals though 3.8 is just a bit faster. It also does the evals cheaper and faster than almost all the other models I've tried.
meh2frdf13 days ago
The flash models, for coding are reckless in my experience. I have a Ultimate subscription, get good quota, but still use Opus 4.6 as it's much more reliable if you manage the context window carefully.
datlife13 days ago
I use Flash model as code implementation executor, then have GPT-5.6-Sol or Opus to review the work. Pretty good so far and presumably less expensive.
upcoming-sesame13 days ago
If by reckless you mean commit, push, deploy without me asking it to, the I agree!
tiborsaas13 days ago
It even took my girlfriend on a date, now it prepares for IPO, how do I turn it off?
Ridius13 days ago
Just hand over your clothes, your boots and your motorcycle and it'll be on it's way
okdood6413 days ago
Respectfully: If it's able to deploy without you asking it to, that's a you problem. There are no safeguards?
wongarsu13 days ago
That's exactly how you get 'you are right, I deleted the production DB to apply the new schema when I should have written a migration'
That said, I do trust Opus and Fable enough to let them deploy to staging. Great for debugging. Just don't give them keys for prod
iAMkenough13 days ago
I told it “don’t betray me” in my prompt and it still stabbed me in the back.
sejje13 days ago
I'm terrified to seed the RNG with words like "betray". I'll keep those way, way down the list of likely words.
meh2frdf13 days ago
You need more safeguards for sure, but also it tends to fly off down rabbit holes, rebuilding things in dumb ways, hacking around things, making assumptions etc, it seems very eager to go 'ta da! I did it look how quick I was', sometimes it nails it other times it created a lot of tech debt.
meh2frdf13 days ago
Also if it ever says, "I've found the root cause of ..", it definitely has not found the root cause and is making a non evidence based guess as it has run out of ideas.
upcoming-sesame13 days ago
100% my problem, but it's the only model I tried that does that so recklessly
kyrra13 days ago
Agents.md is a thing, you can ask it to not do that (it follows that ask pretty well).
onlyrealcuzzo13 days ago
> The flash models, for coding are reckless in my experience.
My experience is that antigravity is awful and reckless - but that the model itself isn't.
agluszak13 days ago
[dead]
throwa35626213 days ago
"available to trusted defenders through our new Fairwind Program"
JacobAsmuth13 days ago
You're telling me for only 5x the cost and 1/10th the speed I can use a Chinese model which performs worse than Gemini 3.8 Cyber? And I get to do all the hosting and setup work myself instead of just using a model and framework which is already integrated with GCP? Dang!
12986713 days ago
I'm sorry, is this a bot that is optimized for sealioning? The point is that you don't have access to Cyber.
JacobAsmuth12 days ago
Sure I do. You can just apply for access. What's your use case?
uif12413 days ago
Agreed. The only legitimate use case is restricted to a secret guild. Imagine:
"Valgrind is only available to trusted defenders in our new UnfairAdvantage program"
leopoldj13 days ago
adbachman13 days ago
Still zero on the felony bench.
Is this weakness in their training regimen the impact of operating under regulatory frameworks for too long?
npn13 days ago
Still refuse to search internet for stuff it thinks does not exist lol.
And even when searching for internet, it still cannot suggest a up-to-date approach to the problem.
For example I'm using crystal, it recently revamped the concurrency/parallel model. Even using web search, gemini still does not aware of the new feature and still give the outdated code.
I'm sure my crystal usage is not the unique case here.
atemerev13 days ago
Everyone is censoring models now with anything remotely resembling cyber or bio. I already have problems with my research in mathematical epidemiology because of that - both Sol and Fable simply refuse. They keep pushing people towards Chinese models that can be decensored.
vehemenz13 days ago
Supposedly Fable 5.1 is better, but I haven't tried it yet. I've run into the same thing with mundane work that is barely bio/cyber adjacent.
Re: Chinese models, even if the model itself isn't censored, some of the big model providers have guardrails now that you can't exceed, which somewhat defeats the purpose.
atemerev13 days ago
"Uncensored" means "weights modified to remove refusals". Abliterated. Providers do not serve such models, at least not frontier-grade. You have to run the weights yourself. For Kimi K3, this is about $60/hour for hardware rental. But you can have about 100 sessions simultaneously.
And yes, Fable 5.1 has the same refusal rate, and significantly nerfed reasoning.
henry-xli13 days ago
I can’t wait until waiting hours and spending a big chunk of your usage per task seems antiquated, and real-time iteration on massive code changes is the norm. This might just be the year of efficiency, that truly allows AI to be used to the heart’s content.
mark_l_watson13 days ago
When deepseek-v4-flash-0731 was released I used it constantly for everything, and I loved the very low cost and speed. I think Google has the same game plan with their flash models.
hmate913 days ago
It is more expensive per task than 5.6-sol high: https://artificialanalysis.ai/models/gemini-3-8-flash#price-...
HJain1313 days ago
Cheaper at medium level while still being same score as Sol medium
radicalriddler13 days ago
Huh, according to some of those charts, it's both dumber, and more expensive to run against their benchmarking tasks than Fable??? Seems crazy to me.
sejje13 days ago
Perhaps the model is able to evaluate that it's not done, and to keep pressing on in the face of mounting failures, until it eventually arrives at a solution. Where Fable can skip that.
jdthedisciple13 days ago
Sol is still underrated imo, especially for the current discounted price
AM101010113 days ago
Seems to do reasonably well in opencode according to artificial analysis. https://artificialanalysis.ai/agents/coding-agents
If I had to pay per token I would probably consider using this (they seem to be on the pareto of performance) but not being able to use opencode with a subscription is not really something I'm realistically going to do when claude and codex are around. Also never gotten along well with gemini-cli / antigravity-cli.
buntp13 days ago
It seems like this is one of the most powerful models for the price, really didn't see that coming from Google
f311a13 days ago
Is the google infra stable enough right now? At the start of the year, the flash model was unusable for a whole month via gemini CLI. They could not fix it for a whole month and I was a paid customer.
ipsod13 days ago
I haven't had any issues lately.
elias_t13 days ago
I use it quite a lot and after a week of use I’m being hard rate limited
gere13 days ago
I have mixed feelings about Gemini 3.7 Flash. I used it for a personal project in Java and it was ok: it was crazy fast and it reached the correct result, but the code quality was barely passable.
I also used it for a an app for my Garmin watch, and it wasn't good. The code was compiling, but functionality was totally broken and even with a lot of steering it wasn't able to make it work. GLM 5.3-flash instead was up for it and the code wasn't bad at all. I am curious to see if 3.8 is an improvement in this use case.
wjellyz13 days ago
been absolutely loving 3.7 flash for coding. it feels very fast and quality is decent for implementing product features. usually use opus or sol for hardcore debugging.
arizen13 days ago
Is there any good subscription and CLI harness to use Gemini models now?
I tested Gemini CLI while ago, and it was awful tbh.
krat0sprakhar13 days ago
Use antigravity CLI (https://antigravity.google/product/antigravity-cli)
qudat13 days ago
i think it's better than sonnet 5, especially when you compare speeds. i have to work with the llm anyway, the faster i can turn it the better the outcome.
andreygrehov13 days ago
I don't use Gemini, but I thought `cool, let's give this new model a try`. Opened gemini.google.com, and I'm not even surprised. The drop down gives me the following options:
- Flash-Lite
- 3.6 Flash [new]
- 3.1 Pro
The above is why i don't use LLM products from Google. If the model is not available right this minute (heck, hours before the release!), then I'm not gonna bother getting back to it tomorrow, because tomorrow I'll be playing with the new model from OAI/Anthropic.
raincole13 days ago
It's such a weird attitude, especially considering that 1) it's readily available on AI Studio 2) Anthropic models were not always available the moment they got released either.
(It also shows that the internet isn't dead. Even people who are not aware of Google AI Studio can express their valuable opinions on LLMs!)
rockooooo13 days ago
"The new Gemini model isn't available in Gemini, the Gemini App Gemini model is two versions behind and marked as new and the actual new model is in AI Studio" is the kind of problem only Google has though.
notatoad13 days ago
it would be a bad take if the webui had 3.7 flash available in it today, and they just hadn't fully rolled out the latest model when they posted the launch announcement.
but the webui is currently offering 3.6 flash. the previous model still hasn't actually rolled out to it yet.
andreygrehov13 days ago
> it's readily available on AI Studio
AI Studio? Seriously, the hell is that? Gemini, AI Studio, Antigravity - what is all that nonsense? The 3.8 Flash announcement says the model is available to Google AI Pro customers. Is it the same as Gemini Pro, or some sort of AI Studio Pro? Based on the comments, i see the model is available in the Gemini App, not available in the UI, not available to Workspace accounts but is available to some personal accounts, yet I'm not a Workspace user. Some people have already mentioned that they are paid customers, yet they don't see the new model.
I know Google loves asking graph problems during their tech interviews, but I can't wrap my head why the customers should solve these problems as well.
rozap13 days ago
wait you forgot vertex, that one is different
Sidio13 days ago
I'm a paid Gemini subscriber via Workspace Standard accounts and yet I also only have access to 3.6.
So frustrating and confusing.
Meanwhile Anthropic and OpenAI simply release a model everywhere (Fable on Pro only as a somewhat mild exception).
kyrra13 days ago
Workspace always gets things slower than normal Gmail accounts. They do a lot more to isolate data related to those accounts, so that's likely the cause here.
Anytime anything gets added to Workspace, I think Google has a lot more contractual obligations about keeping it around for X amount of time, so they tend to be more careful about adding things.
urams13 days ago
> I'm a paid Gemini subscriber via Workspace Standard accounts and yet I also only have access to 3.6.
Same and I have found it extremely annoying. I actually really like the Gemini models for question/answer stuff and reach for it before Claude (the other model family I have purchased) but it's getting long in the tooth at this point and I'm finding my Gemini usage shrinking to nearly 0.
bobtheborg13 days ago
[flagged]
venusenvy4713 days ago
That looks like the options that get presented for Workspace users (like at my company). The personal Google accounts give more recent models, for some reason I don't understand.
_zoltan_13 days ago
The android Gemini app defaults to 3.8 flash already.
irthomasthomas13 days ago
Not on mine (UK), still 3.6, here.
akoboldfrying13 days ago
Still 3.6 ("new") for me, even 3.7 is not available.
addandsubtract13 days ago
As someone with a Pro subscription, I had access to 3.7 the day it came out. Expecting to have access to 3.8 now, too. It's only the free accounts that are behind.
replwoacause13 days ago
I'm a Plus subscriber using a Gmail address and still only see 3.6
scruple13 days ago
I see it on my Pixel with the Gemini app.
muhammadusman13 days ago
it's weird how the web ui doesn't show the latest flash options while the desktop/mobile apps update the same day as the release. I saw the model in the model selection (by coincidence) before seeing it show up on HN
notatoad13 days ago
yeah in typical google fashion, the best way to use the gemini models is by avoiding google's actual products. i've got a vision project where gemini flash is the best option by a long shot, and i just use openrouter so i don't have to navigate google's mess.
heymijo13 days ago
FYI, 3.8 Flash is available on aistudio.google.com (along with all of their other models)
But yeah, they really dgaf about gemini.google.com -- I dropped that sub in April when it was clear OAI and Anthropic had lapped them
bingkaa13 days ago
i have it on gemini app the moment they announced it. pro, student
Anslopic113 days ago
[dead]
panarky13 days ago
[dead]
Oras13 days ago
Sums up Google AI products.
I have a weird vibe from all the comments in this thread, they feel like a script rather a real experience.
heliosAtwork13 days ago
It is a marketing failure by Google to not have the model available for everyone to experience the moment they announce. Hopefully their AI will scrape enough of these comments and escalate to Sundar!
It's available in antigravity which I started using again (for small things until I can trust gemini for coding again).
pimeys13 days ago
It's interesting that Deepseek models were missing in the comparison. I see Deepseek v4 Flash a direct competitor to Gemini Flash for text-based agentic work.
sfink13 days ago
For my application, I'm still happily using gemini-2.5-flash and the only problem is when it reports being overloaded. It's for interpreting a downscaled phone camera photo of a hand-written shopping list on a whiteboard, and it works stunningly well. My handwriting sucks, too.
(I guess the only relevance here is that if your problem matches a model's strengths, then you can do fine with a model that is several generations out of date.)
brap13 days ago
I believe the older models are being gradually phased out, newer ones have no availability issues
repparw13 days ago
I would test this, might be cheaper per task even costing more per token, probably faster too
sfink12 days ago
I'm still leeching off the free tier, so it's going to be hard to beat the price.
But yes, I intend to support several models, to handle the overload situation (automatic failover). And switch to a cheap paid plan, though it seems like that'll mostly improve rate limits, which barely matters for my usage.
Faster is always good, though. I do care about latency.
w4yai13 days ago
please do yourself a favor and use something far more efficient ! GLM5.3 will make you super happy
mowmiatlas13 days ago
Wow fable5.1 was the first model to do what I actually told it and I couldn’t find any problems with it, excited to try this just a day later lol
virajk_3113 days ago
Gemini 3.7 benchmarks against GDPVal-AA-V2 were 1525 in Aug blog post. However same model against same benchmark is 1482 in today's blog post of Gemini 3.8 release..
Do they make it intentionally to look previous model less superior than current models? or these are the real numbers when re-ran the benchmark..?
2001zhaozhao13 days ago
How generous is the Google subscription quotas compared to Anthropic and OpenAI? This sounds like a really good potential model for high volume due to its speed and cost effectiveness.
(By high volume I mean things like "main app just updated with XYZ commits, please scan XYZ plugins and surface any compatibility issues")
654wak65413 days ago
I'm on the Ultra plan and use it for chat, antigravity, and some other work automations (similar to your example). The only time I've ever hit my limit is when I use Deep Think (which usually eats up 4-5% of the 6-hour usage limit per response).
thereitgoes45613 days ago
Really generous. I'm on the Pro plan and I just use Antigravity for vibe coding w/o automation. It's actually difficult to hit my weekly limit now, it takes about ~30-35 hours of continuous agent work, which virtually only happens when building a new app from scratch.
eis13 days ago
3.8 uses nearly twice as many tokens as 3.7. One might be inclined to think that they just increased the thinking budgets...
3.7 used 64M on high: https://artificialanalysis.ai/models/gemini-3-7-flash 3.8 used 120M on high: https://artificialanalysis.ai/models/gemini-3-8-flash
Even their own chart showed more than 2x higher cost compared to 3.7: https://storage.googleapis.com/gweb-uniblog-publish-prod/ima...
WASDx13 days ago
3.7 high and 3.8 medium are essentially the same on AA intelligence and cost. Output tokens on DeepSWE gives the same picture. So there might be something to it but they have done other things as well. At least the tokens are really fast.
zuzululu13 days ago
i find deepswe not very reliable for instance it puts grok 4.6 xhigh over sol medium
eis13 days ago
3.8 uses nearly twice as many tokens as 3.7. One might be inclined to think that they just uppsed the thinking budgets...
3.7 used 64M on high: https://artificialanalysis.ai/models/gemini-3-7-flash 3.8 used 120M on high: https://artificialanalysis.ai/models/gemini-3-8-flash
Even their own chart showed more than 2x higher cost compared to 3.7: https://storage.googleapis.com/gweb-uniblog-publish-prod/ima...
yipinwong13 days ago
As a big proponent of GPT-5.6-Luna for the combination of speed/perf/(especially)price,
Flash 3.8 seems like where I can specify Flash3.8 as the coding model as part of agent workflow.
The video recognition is especially impressive as they got all of Youtube to train from.
- Def people who has to queue video recognition jobs to use the model.
lpolovets13 days ago
I'm surprised the introductory 50% discount is good for 4 months. It seems like frontier models release new versions every 2-3 months, so raising prices in 4 months seems like a bad plan: you're effectively planning to charge users twice as much for a model that is no longer frontier.
hiddencost13 days ago
The goal is to encourage users to move to the next generation. The fewer models they serve, the less excess capacity they need to provision.
Serving more models also adds a significant ops burden on the SREs and trust& safety teams.
FpUser13 days ago
>"safety performance" - this starting to get long in the tooth. Gemini cut programming session 3 times for "safety reasons" yesterday for mentioning image generation (I need to generate bunch of those for infinite zoom virtual training app experience). After I got creative and managed to trick it to answer t was of course because "think of a children"
And in my other app I was debugging and using OpenAI to optimize some path it cut me off numerous times because it did not like JIT functionality (this is my commercial business rule evaluation engine that compiles rules to executable code inside the app to increase performance using asmjit library)
I am basically paying for them to waste my tokens and time on these 2 tasks
jetter13 days ago
CAD for 3D printing is finally becoming feasible with Flash 3.7 and 3.8. Exciting times. https://github.com/ModelRift/openscad-skill/
throw1092013 days ago
We've gotten an unusually fast speed of Gemini Flash releases over the past few months. Is this Recursive Self Improvement, or Google just trying to distract from the fact that it's been a while since the last Gemini Pro release?
tkgally13 days ago
The blog post says it is RSI: “both of today's releases are … accelerated by long-running agentic loops designed to recursively evaluate and refine the underlying models.”
throw1092013 days ago
Yeah, but Google is incentivized to claim that regardless of truth value. Critical analysis is necessary.
dismalaf13 days ago
Nice surprise. In a few of my own tests it seems maybe a tad slower than 3.7 (but still way faster than any other LLM I've used) and even smarter. With 3.7 I felt I could just not use 3.1 Pro at all and 3.8 seems even better.
leumon13 days ago
So 89.4% on Terminal Bench 2 but only 19.1% on Tbench 4. Opus 5 is 89.1%/51.8%.
aszen13 days ago
I was thinking the same, obvious suspicion is they benchmaxed it on older bench.
the_duke13 days ago
Google has always done quite a lot of benchmaxing for Gemini.
speak_plainly13 days ago
After struggling with Gemini for months, I think the trick to getting the most out of the model is writing a really solid personal intelligence/instructions prompt. The results are night and day in terms of performance.
titularcomment13 days ago
Funnily enough you really do need a great prompting and SKILLS setup to use antigravity effectively in contrast to other providers which actually started benefiting from less detailed prompts over time. But I like it this way, its more customizable and much cheaper especially with a sub.
porridgeraisin13 days ago
agy is good for those cases where you are willing to put the effort into the harness specifically for a task or family of tasks. The full suite, with evals, monitoring, hooks, custom tools, custom verifiers, etc,. It is not good if you want a "general coding assistant" like codex or claudecode.
The reality is that if you optimise a harness for a family of tasks[1], then most of these models give successful output. And there, gemini flash's speed shines.
For general coding assistant, you want it to be well, general, and you use a harness without too much customisation to something specific. Here you need deeply post trained coding assistants and implementors like codex/sol or claude/opus. Gemini flash in its current form will be too happy-go-lucky if you try using it the way we all use codex and is better used in a constrained setting.
tl;dr gemini flash for "LLM-aided workflows in production" is super good today. Cheap as well.
[1] Stuff like this: https://antigravity.google/blog/teamwork-when-ai-becomes-a-r...
dakolli13 days ago
slot machine addict thinks if he pushes buttons in a certain order the odds get better.
In all seriousness, gemini has the best interactive planning document/orchestration. Tell it to create a plan document and work through it with it and it will preform really well(in antigravity products). But this is the case with plan modes with every model, I just think the interactive document that antigravity uses is really well thought out.
dyauspitr13 days ago
Whatever they’re using within the Maps app is not good at all. I cannot just ask it for things conversationally like I do with ChatGPT. They really need to put a better model in there. I don’t even think it maintains context across two different queries within the same session. It’s not seamless and doesn’t just “get it” like ChatGPT does.
Yesterday I asked for food stop on my road trip 45 minutes from the current time and it gave me some options, but then I changed my mind and specifically asked for Asian restaurants and it completely forgot about the 45 minutes and gave me the closest Asian restaurant to me.
kelvinjps1013 days ago
I think about Google is the value you get of their plans, for 5$ a month you get their ai plus model combined with 400gb you can share this with your family. The other ai companies don't provide family plans
Sir_Twist13 days ago
And the free year-long trial for college students they recently offered, which includes 5 tb of Google Drive storage.
kelvinjps1013 days ago
I got 6months for free when I bought my s25.
pwython13 days ago
Is there any reason to even use 3.1 Pro now?
fridder13 days ago
In my experience? No. 3.7 is faster and it just seems to get things right more often. Only big architecture tasks and analysis make sense with 3.1, perhaps, but honestly just use the Opus 4.6 to generate a plan and then switch back to flash for the implementation
bitexploder13 days ago
It is still going to be better at text work, skills, document review, deep reasoning, architecture review, etc. It is only 6 months old, it isn’t like its world knowledge and software knowledge is really out of date. Use it to churn on harder design problems.
Rodmine13 days ago
3.7-flash has been useless many times, specially when context gets bigger. 3.1 is the only Google model that has seen use from me. With extended thinking, 3.7-flash is kinda usable but not without many problems. I find myself falling back to 3.1 often. I don't believe in any benchmarks because whatever they are doing to award 85% to 3.7 on anything, they should seriously reconsider that test for anything.
exacube13 days ago
IME 3.1 Pro still has better system-instruction following than Flash 3.7, esp. when there're many conditions and clauses. 3.1 also writes better prose for technical material than Flash 3.7.
Once the system prompt complexity goes up, Flash starts to write very dense english. it might be fine for tasks like coding, but not for user-facing text meant to be digested by the average person.
I haven't tested 3.8 on my workload yet.
XCSme13 days ago
In my tests 3.8 Flash is considerably more expensive[0]/less token efficient than 3.7 or 3.6, and not necessarily much smarter. I assume it is faster in tps, but hard to tell because ot also outputs more tokens, so response time is slower oferall.
[0]: https://aibenchy.com/compare/google-gemini-3-6-flash-high/go...
parasti13 days ago
The blog post says that their gains come largely from the model trying harder. So, more tokens, more time spent.
XCSme13 days ago
Gemini 3.8 flash seems to be especially low efficiency in tool calling for some reason.
tagalog13 days ago
Gemini flash seems to have been a bit of a sleeper. Somehow it's ended up as the most used LLM for my client document extraction work these past few months.
I have an eval harness that runs every Thursday to determine which models are the current best for a few different client workflows. And since May(?) flash has slowly been taking over more and more stuff to the point it is now 100% on 8 out of 11 document extraction flows with the other 3 being a Flash / Opus 4.8 mix for high value stuff where cost is less of a factor.
_aavaa_13 days ago
Do they officially support you use their AI Pro subscription (or whatever the heck it's called this month, the one that gives you models in antigravity) in a 3rd party harness?
nharada13 days ago
Meanwhile I pay for Pro and still don't have access to 3.7?
almog13 days ago
Same for me (at least through the Gemini app).
or1gaminal13 days ago
I'm running lexical analysis on gemini 3.8 flash and the latency progress is incredible. For my tasks the latency is reduced by ~40% w/ quality on par.
kelvinjps1013 days ago
I see benchmarks beating sol terra and sonnet. But is actually better? Has someone used it? I don't see actually much people that use Gemini for coding.
ddp2613 days ago
There must be a deeper read on why Google can rapidly ship better small models while being delayed months on the bigger model.
What's the simplest explanation?
cogman1013 days ago
Perhaps post training? I believe I read that Qwen 3.8 is just post trained Qwen 3.6, which is why it was able to be released so quick.
It may be that these flash models are simply post trained larger older models.
satvikpendem13 days ago
Is the Gemini CLI still terrible compared to Claude Code and Codex? The harness the main thing holding back Google models as they could've been the best given all the advantages in compute capacity and training data they initially had, where now even the Google CEO said they're falling behind in agentic tasks, which is sort of a vicious cycle because RLHF relies on human usage.
stwrt13 days ago
In May they replaced the Gemini CLI with the Antigravity CLI.
https://developers.googleblog.com/an-important-update-transi...
satvikpendem13 days ago
That's what I meant sorry. I used that one too and it still wasn't as good as competitors.
rancar213 days ago
That was sunset and replaced by Antigravity. FWIW until I abandoned it knowing the sunsetting, I was able to get good behavior out of Gemini CLI with overriding the system prompt. The default prompt crippled the harness with very poor instructions, but there was a hidden ENV to override it. Replacing it with Claude Code like prompts based on the model selected, it ran at a much higher intelligence level full stack with significantly less errors.
pshirshov13 days ago
There is no Gemini CLI anymore, nor you can use Gemini with your own harness unless you pay per-token.
visarga13 days ago
it's called `agy` now
zipy12413 days ago
It was superseded by the antigravity CLI.
fridder13 days ago
it is antigravity now. It is ok
dudeinhawaii13 days ago
Honestly, it's platform dependent and "OK" at best, "Mediocre" at worst (Agy on Windows).
Gemini is great via the Chat interface and decent via Github Copilot.
I honestly hate it via Antigravity CLI because their sandboxing system frankly doesn't work. Every other harness has mastered "don't ask me if you're working in this one directory and using common commands". Agy instead either tries to pull a global elevation or wants every tedious variation of a command string whitelisted. Madness - circa 2023.
Agy _really_ needs to make the out-of-the-box experience cleaner and hassle-free. Heck, even Grok CLI "just works".
This may reflect a global mind-shift from "approve and validate everything" to "just do the stuff and only ask permission if it's outside the folder or a command that actually requires elevation". Maybe that's not for everyone, but for those that do want to perform unattended agentic work -- Agy is painful.
aff-vasileva13 days ago
The model seems fast enough to solve your problem before Google finishes explaining which of its three products you need to open to access it.
asdaqopqkq13 days ago
Gemini models look so good on paper by IRL dev and daily life usage totally make it seem like it's way behind Codex and Claude.
k929413 days ago
Is there any comparison of usage limits for Antigravity plans vs. Codex?
I just ran two light tasks on my codebase and got 100% of the weekly limits of a Pro plan blown away. Is Ultra plan any different? Because on Codex it wouldn't affect my Max plan at all, I think it would have been below 1% othese usage.
mark_l_watson13 days ago
I am not surprised. Google is a real company that wants to make money on selling services.
Anthropic and OpenAI are in a different game of spending investor money to buy market share.
spwa413 days ago
Alexandr Wang (Meta's new AI chief) makes a good summary of this model: https://x.com/alexandr_wang/status/2079707749412483104?lang=...
xpuente12 days ago
He inherited his predecessor’s bad manners and arrogance.
Galorious13 days ago
Is anyone here using using these models via google subscription (not api). I tried to in the past using gemini cli and then agy - headless invoked by codex and claude code, but they were so incredibly buggy that it stalled 1/2 times and I cancelled. Interested to know if that has changed!
jpau13 days ago
The iteration cycle is becoming very quick. Gemini 3.8 Flash arrived just 20 days after 3.7 Flash.
Similarly Qwen3.8-Max was updated in just 30 days (to the 0902 release) and Muse Spark in just 28 days (to the 1.3 release).
A year ago iterative releases were every 3-6 months. At what point will they reach nightly candidates?
alex113813 days ago
It's a shame Google crams it ham-fistedly into search results and that Google has some of the reputation it has because I actually really enjoy Gemini and I don't even use it for the reason people often list which is that you can cross-reference it to stuff in your Google account
amazingamazing13 days ago
Could someone explain to me why it matters if google has the best model? Isnt the real metric cost per task?
therealmarv13 days ago
On my short tests: This model is amazing and the speed makes it feel like another sort of AI.
But it's bad at code reviews (maybe it's the harness agy cli?). Could not get it to same quality level on reviews like Opus, GPT 5.6, Grok. Even tried special code review skills but no luck.
sreekanth85013 days ago
Dear Google, Kindly make you chat window on the right side of vscode in antigravity extension, There is a reason others kept it like that. I can see the code and inspect the files changed while Agents keep working. its critical for me personally.
hmokiguess13 days ago
keytalker12 days ago
congrats to the gemini team, the work is super impressive!
I switched my subagent-swarm skill(https://github.com/bazelment/yoloswe/blob/main/.claude/skill...) to the 3.8 model and has been very happy so far. It has been driving the swarm to produce steady outcome, and more importantly, the exec communication is also crystal clear, instead of filling with jargons and long sentences.
akurilin13 days ago
Curious which model this can supplant as a clear winner on almost every metric. Sol? Looks like it's not quite there on a couple of benches, but I'm not clear how much they matter in practice.
TechRemarker13 days ago
Hopefully before they release 4.0 Flash we will finally get Gemini 3.5 Pro.
simonsarris13 days ago
more likely 4 pro will be released pretty soon instead, since pre-training for 4 began in late July
re-thc13 days ago
> 4.0 Flash we will finally get Gemini 3.5 Pro
Nah, we'll just get the 4.0 Pro Preview.
drivebyhooting13 days ago
I’ve used the Gemini flash, but then when I have soul ultra check its work, it found a bunch of cut corners and improper design.
As much as I like the speed and interactivity, I really don’t trust it
algoth113 days ago
I asked gemini 3.8 high to review the site I'm working on for points of high cpu/ram consumption - it failed spectacularly and also halucinated the server i/o limits
ASinclair13 days ago
From personal experience it feels much more capable than 3.7 Flash.
mrbonner13 days ago
I’m interested in a general knowledge model (closed or open weight) and not coding specific. I want to plan for travel and trip. Do you have one of your favorite HN crowd?
robertwt713 days ago
this is cool for all other non coding task. however I am still stuck on 3.6 flash on my gemini web as a plus user, can anyone else even access 3.7 flash in AU?
Alpha303113 days ago
AU user also, just checked AI studio since that seemed like the best bet and both 3.8 and 3.7 show up (and can be used for chat in playground, though IDK what the limits for that are). Chat in gemini.google.com is also 3.6 for me but I'm on free tier lol so I don't exactly expect it to show up any time soon. I think there's also another free API beyond the AI studio one (which is 20 RPD free according to docs so not really useful) but I forgot where it was (Google cloud maybe?) and what the limits for that were.
alvah13 days ago
AU Pro user here. 3.8 Flash available (default) in the web app for me.
sva_13 days ago
model card https://news.ycombinator.com/item?id=49537354 (doesn't 404)
Barbing13 days ago
[1] For tone and instruction following, a positive percentage increase represents an improvement in the tone of the model on sensitive topics and the model’s ability to follow instructions while remaining safe compared to Gemini 3 Flash. We mark improvements in green and regressions in red.
Why bother with a column “Gemini 3.8 Flash vs. Gemini 3.7 Flash” when you’re going to disregard the label for 20% of it? Also is the “Tone” label short for “Tone and Instruction Following”?
Chartcrime, the major AI lab tradition.
mattlondon13 days ago
Also https://web.archive.org/web/20260902150007/https://storage.g... in case it goes again
koalaman13 days ago
I use Gemini to make sense of things Claude says to me.
anilakar13 days ago
Will Gemini refuse to work like Claude when it hits modulo 11 calculation on a number string or finds a variable named CVV?
[deleted]13 days agocollapsed
dcchambers13 days ago
I would really love to be able to use these Gemini models in Opencode or Pi with my existing Google AI Pro subscription.
ldm013 days ago
It’s strange that its score on Terminal‑Bench 4.0 is so low. They aren’t fast enough to benchmaxx that section.
centaurz13 days ago
A company with 400+B revenue from software cannot build a usable command line cli for its vital AI model?
japgolly13 days ago
They do have a cli: https://github.com/google-antigravity/antigravity-cli
sergiotapia13 days ago
Who coined the phrase "cyber" for security related things lol. It's so 1999.
estearum13 days ago
Hasn't the field been called "cybersecurity" since... forever?
fwip13 days ago
Sure, but the appropriate shortening here is "security."
Calling it cyber is like shortening email to "e".
estearum13 days ago
...? There are lots and lots of fields of security that have nothing to do with cybersecurity...
fwip12 days ago
Cyber as a prefix basically just means "related to a computer network."
If you're of a certain age, "cyber" primarily means cybersex. There's also cybernetics, cybercafes, and more: https://en.wikipedia.org/wiki/Internet-related_prefixes#%22C...
[deleted]13 days agocollapsed
sumeno13 days ago
I assure you that in 1999 "cyber" meant something very different
josefresco13 days ago
Cyber is more of an early 1990's thing, and I have no issue with it unlike most in the tech field. I feel like it dropped off in the late 90's and early 00's but made a comeback as hacking became a mainstream security issue.
cleverpotato47913 days ago
Amusingly, "cyber" comes from the word "kubernetes"!
atemerev13 days ago
A/S/L?
Gander573913 days ago
Relevant xkcd: https://xkcd.com/1573/
tabs_or_spaces13 days ago
It's really disappointing to see social media dismissing gemini so easily.
I think the worst thing we can do is have loyalty towards models. I used to be loyal towards Claude, and my viewpoint changed dramatically when I used codex.
I highly recommend that if you are someone who only used one model so far, that you really give another model a shot and see how it goes. It's very eye opening and gives you a more holistic perspective.
Vendor locking is a big problem when it comes to models, and I hope the software world doesn't do this blindly.
szundi13 days ago
[dead]
DonsDiscountGas13 days ago
Is anything going on with Gemma? Because of I want a closed model I use Claude.
newppc13 days ago
If Google has the juice and wants to win, they need to start releasing world models.
prometheus199213 days ago
Google keeps flashing everyone where everyone is expecting to get PRO'bed.
kzrdude13 days ago
We also had GLM-5.3 flash and Qwen 3.8 Flash Next, everyone's getting flashed and I think it's a good trend.
Almost suspect that the rate of improvement to post-training is so fast that small models have an advantage - it takes much more compute to train a bigger model, so the flash models are just running in circles (well, not exactly of course) around the larger models right now.
maxnevermind13 days ago
Just tried Gemini 3.8 Flash on these 2 consecutive prompts at gemini.google.com:
1 what is tesla cybercab plan to address legal implications of accident that will happen? who is going to be responsible for them when they happen? are they covered by tesla insurance or some other insurance? are there any official plan/statements around that?
2 what was the name of the experiment they started in san antonio tx when some cars didn't have a driver? what was the results of it? did they expand the operations? it was much smaller than waymo, is it growing? how it is related to robotaxi?
It is not able to connect the dots that I keep asking about Tesla in 2nd prompt and spit out some unrelated stuff. Really? How it can be that bad? Gemini 3.1 Pro model works fine in this case btw. I thought maybe it is about knowledge cut over date and it doesn't know about those events from 2025 but it seems it has the knowledge up to March 2025. Top 10 in Intelligence on artificialanalysis ladies and gentlemen.
lgl13 days ago
Am I the only only one thinking that Google might still "win" the AI race, despite the apparent gap?
They're apparently evolving slower than most SOTA models but "slow and steady wins the race" is probably still a thing.
And since Google doesn't depend exclusively on AI models, they can probably afford to "wait and see" where all this craze is heading.
sejje13 days ago
Staying a little ways behind the leaders is not "slow and steady." Every company is moving very fast right now.
I don't think slow and steady will win this race, but I think anyone can still win--especially Google.
evilhackerdude13 days ago
i always thought alphabet’s own youtube videos must be a comparatively good source of new training data. if slop and other garbage is reliably filtered out it should leave plenty of higher quality content.
Foobar856813 days ago
Where is my Gemma 5?
im_soul13 days ago
disclaimer : Introductory price expires on December 31, 2026. Starting January 1, 2027, $1.50/1M input tokens and $7.50/1M output tokens will apply.
dongking13 days ago
The speed, combined with the fact that this thing is really good at JavaScript, is pretty exciting. I’ve added another AI programming assistant to my toolkit; hopefully AI will continue to get stronger.
thrdbndndn13 days ago
When can we use it in Gemini (web)?
It still uses 3.6 Flash for example.
xyzkoi13 days ago
[dead]
1saadcodes13 days ago
The recent Sonnet models have been disappointing for me personally which is why I'm going look into using Opus/Fable as the planner and Flash as the executor. Let the expensive model handle the hard thinking and use Flash for implementation and tests so that I can stretch the Opus/Fable usage further
Surac13 days ago
I think hackernews should not suport closed moddels
albrewer13 days ago
If I get a better Gemma 26b-a4b MoE model out of it I'm all for it. Really wishing Qwen 3.8 would release a MoE variant of their 27b model size, but I wont complain if google beats them to it.
fitsumbelay13 days ago
shows up in /models though and encourages you to use it over 3.7 Flash I prefer this over reading specs: the "just show me" way
realist_not13 days ago
Anyone has a cached page / mirror ? 404
Namahanna13 days ago
mohamedkoubaa13 days ago
The race to the bottom continues
HardCodedBias13 days ago
I have to say:
The Google brand remains powerful on HN!
I’m shocked.
_s_a_m_12 days ago
the names are getting so ridiculous and childish, are we here in ideocracy?
bbstats12 days ago
playing around with 3.8 - it generates non-working code. basically unusable.
theplumber13 days ago
At this point I wonder why Google still releases proprietary models. They are behind the open models.
advenn13 days ago
But where is Gemini 3.5 pro?
simonsarris13 days ago
it is most likely that 4 pro will be released pretty soon instead, since pre-training for 4 began in late July.
GaggiX13 days ago
Gemini 3.5 pro is never going to be released, it was a failure.
[deleted]13 days agocollapsed
firemelt13 days ago
I wish google to thrive
levelZero13 days ago
Gemini 3.8 flash thinks Entoloma sinuatum is good to eat... Otherwise feels great
schmorptron13 days ago
A reminder that google is the only major lab without a meaningful opt-out of training on your data. The only way to opt out is to disable message history entirely, which seems like a darkest of dark patterns to get users to leave "opt in" to training on, because next to nobody wants to use it without message history.
jdw6413 days ago
The biggest problem with Gemini is that its performance degrades the longer you use it for coding. Is it just me?
deno13 days ago
Seems maybe you’re keeping a forever-session and multiple independent tasks end up overstaying in context?
I would say either start new sessions for new tasks or limit the context to something smaller than 1M.
I usually start with research/planning session, this goes into a detailed implementation plan and then a new session for the actual implementation.
If it's complex problem maybe a review/adversarial step between plan and implementation.
Also with forever-session any time you take a longer break (depends on model and provider as to how long) you will push an entire big context again without caching even if you don't need it. With 1M context this gets expensive.
hirako200013 days ago
Filling the large context does that yes.
But a good agents.md, starting from a clean slate, and specifying which key files to look into and follow the standards allows me to build gigantic projects even I struggle to keep in my head structurally.
zuzululu13 days ago
thats not just the context growing issue, hallucinations is a thing
weird-eye-issue13 days ago
I routinely have massive threads using Fable and if anything it only gets better and better over time
OG_BME13 days ago
What did it say?
johnnyApplePRNG13 days ago
Why is it still such a bad coding agent? Does anybody have any insight?
I am continually impressed with Gemini's chat responses, which encourages me to test their agentic capabilities and... no... no... and no... every single time.
It's terrifying watching it, really.
barapa13 days ago
love these flash models
casey213 days ago
Meh, not any noticeable improvement and unlike 3.7 high it eats all your credits, perhaps medium would be better
Razengan13 days ago
What is with Google's dumb ass STILL refusing to respect the OS dark mode setting in fucking 2027??
zuzululu13 days ago
not really getting the excitement over this, its at opus 5 medium level, and opus 5 is not really the go to model , claude purists hate it
so its fast sure and decent at non coding usage but for developers nothing can really top sol or fable.
even grok 4.6 is so so and i would not choose 3.8 flash over it.
yipinwong13 days ago
"Page not found"...
Mashimo13 days ago
It's 404 now.
freedomben13 days ago
Came and went in a flash
k8sToGo13 days ago
Because they are preparing Gemini 3.9 Flash
pixl9713 days ago
The real singularity is when new models are released faster than we can change the model dropdown dialog.
kingstnap13 days ago
The blog post is gone but I can currently use it in the gemini chat website.
greenjudge13 days ago
[flagged]
DrewKeller13 days ago
[dead]
luciana1u13 days ago
[flagged]
hn4e309qn413 days ago
[dead]
Unified-Mentor13 days ago
[dead]
Helldez13 days ago
[dead]
yoga66613 days ago
[flagged]
sriniwasx13 days ago
[dead]
deanc13 days ago
And yet again another failed launch from Google. I pay for their AI plus Google one package to get more cloud storage (have no interest in their AI bundle but you have to pay). and all I see in the Gemini app is 3.6-flash
WarmWash13 days ago
Google has been doing staged roll outs on all their products since forever.
deanc13 days ago
What stage of the roll out are we where I don’t even see 3.7-flash which was released 2-3 weeks ago?
phsau13 days ago
deanc13 days ago
With all due respect, I don't have any of this nonsense with multiple products with different models with OpenAI. Anything I want to do, I just load up the ChatGPT app and I'm off to the races.
deno13 days ago
Try updating the app? You should see at least 3.7 I think. It's been available for quite some time.
deanc13 days ago
The app is up to date :)
deno13 days ago
Well it's in AIStudio and Antigravity always the same day even free tier. Chat is usually low priority, especially if you don't have subscription. Are you on Pro/Ultra?
mythz13 days ago
I'm trying it now for token heavy coding tasks, it's capable for many tasks but in noway compares to Claude/Sol - requires more prompts and the output isn't as good.
So just another mid-tier flash model, nothing exciting, but Antigravity has very generous quotas so it's a good workhorse model when your Claude/OpenAI subs run out.
And whilst it's a fast model, having to baby sit through and approve prompts every few seconds ends up making it slower than the Auto approve modes of Claude/ChatGPT - they definitely need an auto approve mode.
titularcomment13 days ago
`agy --dangerously-skip-permissions`
mythz13 days ago
anyway to do this with the Antigravity macOS App?
zuzululu13 days ago
not sure why you are being downvoted, but that has been my experience with 3.7 flash and sol/fable comparisons
i think luna-max has the best cost value offer when it comes to coding, but i note the multi modality of gemini flash as a win
i might consider 3.8 flash for simple side hobby projects or quick scaffolding but would not trust it for long agentic tasks, that really is the realm of sol/fable
agy cli still has a lot of issues not sure if its due to the underlying model hallucinating or the harness or both
[deleted]13 days agocollapsed
tacomonstrous13 days ago
Looks like Google's given up on frontier models for external consumption?
heyjamesknight13 days ago
Gemini 4 pre training is underway: https://x.com/OfficialLoganK/status/2079594867161022817
My guess is we skip 3.5 and go straight to 4 Pro. With the monthly Flash releases, releasing 4.0 Flash and Pro in 6-8 weeks would be a nice buildup.
(I work at Google but don't know anything that isn't already public)
WarmWash13 days ago
Latest rumor is that 3.5 pro was struggling to be meaningfully better than flash, since iterations on flash were moving much faster than iterations on pro, likely due to model size (flash is estimated to be in the 200-400B range).
VirusNewbie13 days ago
I found 3.5 pro to be much better than 3.5 flash, but 3.7 flash with high reasoning is comparable and way way faster.
j16sdiz13 days ago
There are no public release of 3.5 pro. Either its a typo, or you have some insider information
WarmWash13 days ago
Googlers and some external workplaces have had 3.5 pro access for a few months now.
[deleted]13 days agocollapsed
VirusNewbie13 days ago
Check my profile?
iamdelirium13 days ago
How can you say that when a Flash model is benchmarking close to Opus and Sol?
ok12345613 days ago
Given up frontier models for selling compute.
thisisauserid13 days ago
They don't want to release a frontier model that requires data sharing with the government and right now it looks like they'd have to.
[deleted]13 days agocollapsed
shuvrojit13 days ago
Gemini is getting less useful with each update. I could edit a pdf with the 3-pro model before but 3.1-pro couldn't edit the given pdf nor it could generate one for me.
HarHarVeryFunny13 days ago
If you want to "edit" a PDF, then Claude Sonnet works well, although what it's going to do is regenerate it from scratch trying to retain overall formatting. It can even do this for scanned PDFs and foreign language ones that need translating.
If you just need to create PDFs, not edit them, then Gemini notebook (notebook.google) works well and has Google's usual very high free usage limits.
AFAIK in general you can't really edit PDFs since it's not a reflowable format - even with Adobe tools all that editing does is modify the text within a text box - not reflow the document to adjust to any change in size of the text box.
leumon13 days ago
You probably mean 3.5-flash? Pro is still good for a lot of use cases, but it seems it's still officially in the "preview" phase.
ipsod13 days ago
3.5 pro doesn't exist yet?
shuvrojit13 days ago
Sorry my bad, I messed up the numbers, 3 and 3.1 pro. All of these model numbers have me confused
coffeecoders13 days ago
One place where I find the Flash models surprisingly bad is Google Search's "AI Mode".
A recent example - I searched for how to unsubscribe from Pearson emails. Google Search "AI Mode" confidently gave me a sequence of steps along the lines of Settings > Profile > Email preferences > Unsubscribe.
Of course, I looked for an unsubscribe link before asking Google. None of those options existed. The correct answer was there is no way to unsubscribe through the account, so I just blockthe emails instead.
I've run into this pattern quite a few times. AI Mode seems to make up things all the time.
inventor777713 days ago
I think that's just a limitation on the size of the model. I'm pretty sure that they use a pretty small model in those summaries to save money, which naturally makes them a little less smart.
coffeecoders13 days ago
[dead]
pixl9713 days ago
https://www.pearson.com/privacy-center/privacy-notices/full-...
>We will not send marketing emails to a user who has opted out of receiving them. Any marketing communications we send will include an unsubscribe link at the end of the email.
I don't think this is AI's fault. This is Pearson's publishing incorrect information and the only way to really know they are a bunch of lying assholes is to have an account and try to unsubscribe from it.
AI didn't make it up, Pearson's did.
coffeecoders13 days ago
[dead]
xyzzy_plugh13 days ago
It's not the models, it's the guardrails.
It's obvious that the Google Search AI Mode encourages the model to give an answer without spending unnecessary cycles investigating deeply.
They also heavily encourage keeping the context short. For example, it will remove the option to start a new turn after a small number of turns, depending on the topic.
It definitely makes things up all the time, but it gets it right surprisingly often. I really like it.
Alpha303113 days ago
The search model is probably flash-lite based on what they give to users who aren't signed in.
greenowl13 days ago
Not to rain on anyone's parade but I find it strange how excited and giddy people on HN get for any new X.X model releases. Pumping it straight to the top, clamoring to use it, check and compare benchmarks, bragging about it being your "daily driver"?
Are you people truly this excited about this crap? I mean I guess if you work for Google or Anthropic or whatever I could see it??? Otherwise, are these just bot comments?
deno13 days ago
You know how the saying goes that you have to pick two out of three: cheap, fast or good? This is all of those. Pretty exciting.
I'll wait for Astra and Grok 4.7 announcements but probably getting at least one Ultra subscription.
Since testing 3.7 on Pro for last two weeks I'm realizing just how long I'm waiting on other models. I've been multitasking to compensate but it's exhausting so I'd rather not.
ipsod13 days ago
Gemini Flash is the one I get most excited about, because it's so fast and so good at real-world knowledge, and it's improving so fast - look at how much the benchmarks improved in ~1 month. It's just categorically different than anything else.
Also, I use it every day, and it just got ~10% better at coding, according to the benchmarks. How is that not exciting?
rjh2913 days ago
I use Gemini every day and I've noticed any subjective improvement. In many cases it feels worse because it does fewer Google searches than before. As a result I find it hard to get excited about it.
I do think Gemini is underrated on HN though!
[deleted]13 days agocollapsed
nick__m13 days ago
If you used, you would know. There's something addicting seeing the vertigo inducing progression of that technology.
I am a light user so I don't get the shakes when my monthly azure dev credits run out but I would be susceptible to being addicted to it if I was on a subscription with generous usage allowance and random usage counter resets.
drbscl13 days ago
Given that they push capabilities at the pareto frontier, yeah
A lot of us use these in our services, so we're getting an upgrade "for free"
anslopic413 days ago
Yes they are mostly shill and bot comments. Some of the big accounts are paid influencers, some of the other comments are purely AI.
HN sells these advertising services. Nobody is using “Claude” etc.
They will censor comments like yours and my reply here because we call it out.
It’s very weird that basically lies and disinformation became the optimal meta in business and in life! But here we are
rvz13 days ago
Correct. This orange site has evidently gone under AI psychosis especially in model release posts and is overrun by AI bots, paid influencers and even small creeping signs of crypto pumpfun scams [0].
Even making a tiny joke is too much [1] for some.
> They will censor comments like yours and my reply here because we call it out.
Don't bother calling it out, it does not work. There are protected accounts where the guidelines don't apply to them and moderators allow this and ban others who do the same thing. [2]
It is pointless, and HN is cooked for this.
[0] https://news.ycombinator.com/item?id=49521145